Frontier models reach only about 70% on realistic 100k-tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → multi-document reasoning, and non-reasoning long-context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → models can beat reasoning ones. Use this to pick models for large codebase or document work.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
 articleAre the Financial Reasoning from LLMs Credible? A Real World Test over Long-Horizon StatementsXinke Tong, Xuanming Zhang, Tianyi Tang, An Yang, Jiatu Hu, Guojie Lin, Zhenzhen Shi, Lingfeng Zeng, Boyu Yang, Bing Zhao, Hu Wei, Lin Qu, Dayiheng Liu
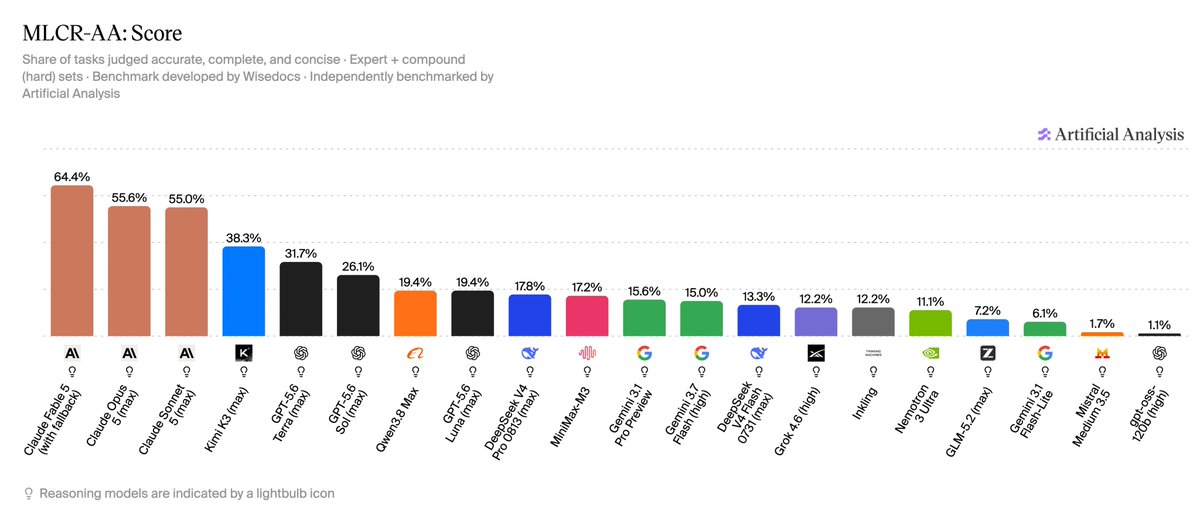 postLong medical case files as a reasoning benchmarkArtificial Analysis