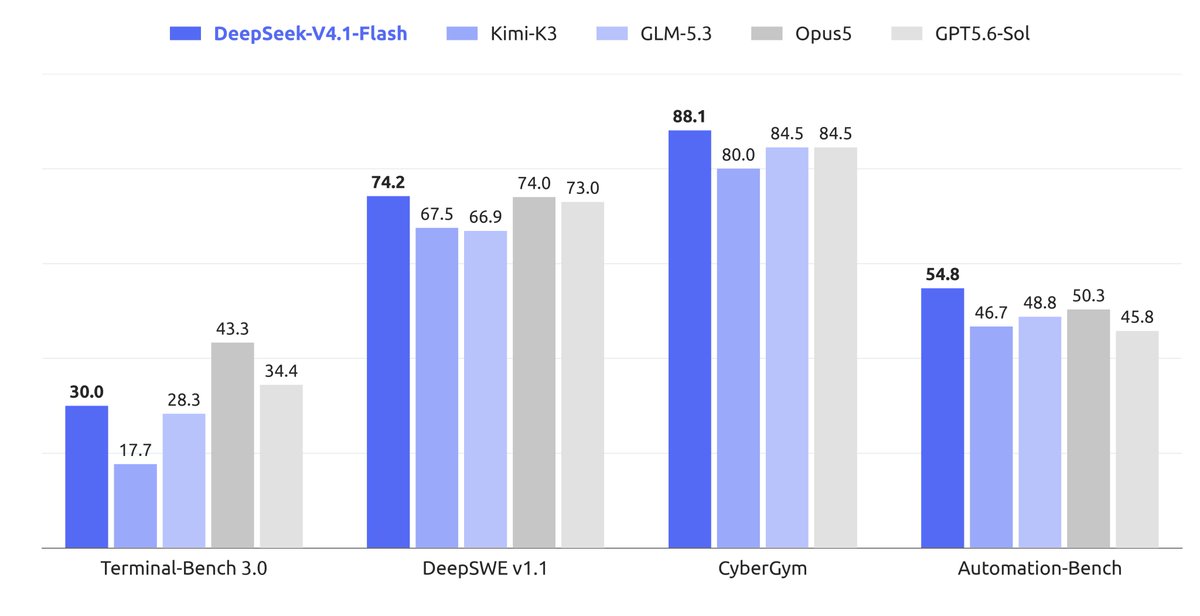
[AINews] DeepSeek v4.1-Flash: 763B-P8B-D16B novel causal Encoder–Decoder architecture with vision marks the Return of the Whale
- Source
- latent.space
- Date

Context
DeepSeek's V4.1-Flash uses different amounts of active model computation when reading a prompt and generating an answer. Its model documentation describes an encoder that processes inputs and a decoder whose global memory comes from the encoder's final representations. The company reports eight billion active parameters per input text unit during prompt processing and sixteen billion during generation.
That distinction matters for tasks with long inputs: processing the supplied material need not use the same active computation as producing the response. DeepSeek presents the architecture as an efficiency improvement for such workloads. These active counts describe computation used at a step, rather than the size of the complete stored model.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.


Checking sign-in…
Loading comments…