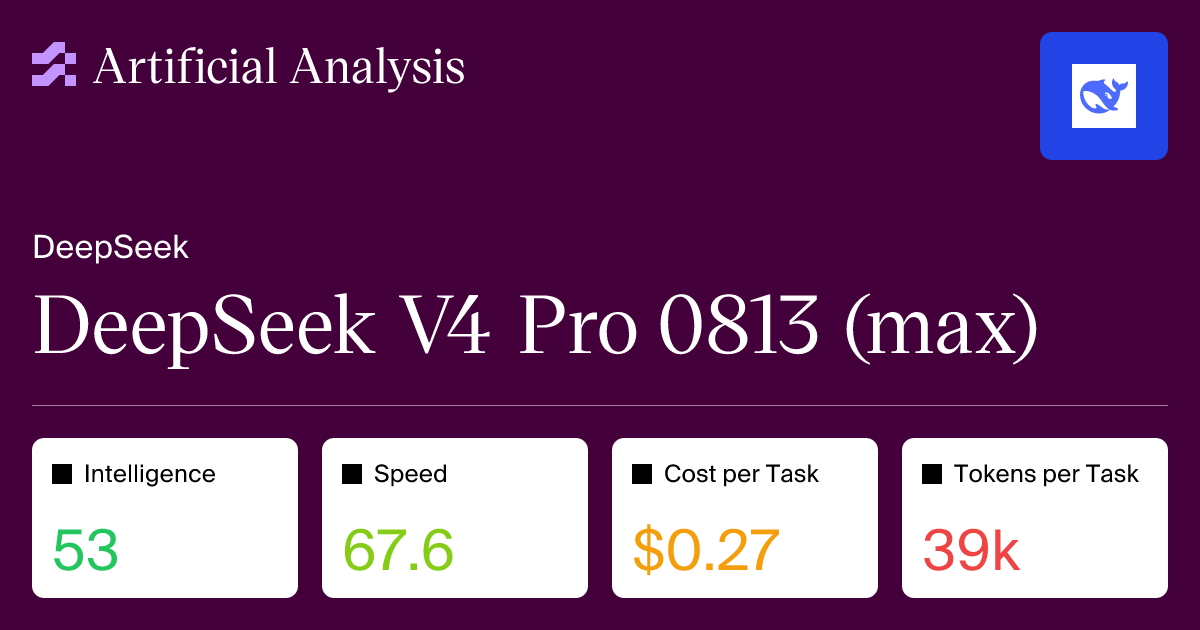
The index now scores agentic work and reports cost, time and tokens per task, so model comparisons reflect what an AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → run actually costs. For example, DeepSeek V4 Pro costs $0.04 per task against $1.78 for Opus 4.8.
Key takeaways · AI-distilled
Artificial Analysis removed saturated IFBench from Intelligence Index v4.1 in June 2026 while continuing to publish standalone results. A benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → can remain informative without distinguishing the frontier enough for an aggregate ranking.
Intelligence Index v4.1 increased the emphasis on agentic work. Its June 2026 weights assigned 20% to GDPval-AA v2, 16% to Terminal-Bench 2.1 and 14% to tau3-Bench Banking.
The June 2026 GDPval-AA v2 revision set human performance to 1000 Elo, rotated frontier-model judges and raised the turn limit from 100 to 250. These changes alter how agentic results should be interpreted.
Artificial Analysis defined cost, time and tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → per task by dividing total Intelligence Index usage by its task count. Its June 2026 update also began reporting cached inputs, which affect the cost comparison.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.