[AINews] Claude Opus 5: Fable-level performance at Opus price (half Fable)
- Source
- latent.space
- Author
- Latent Space
- Date
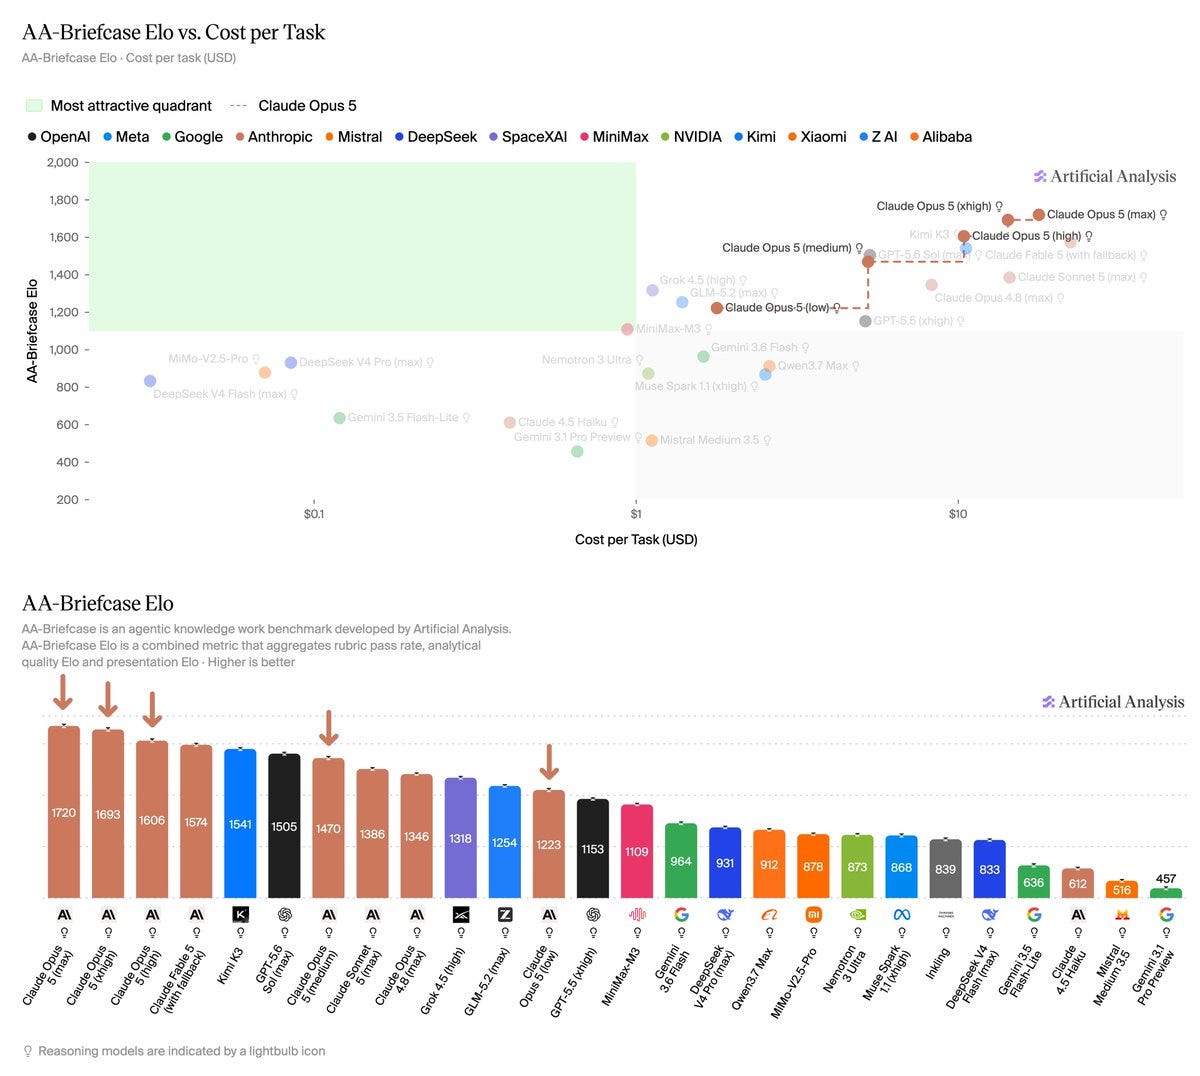
Context
Anthropic's Claude Opus 5 launch presented a specific efficiency claim: on CursorBench 3.2 at maximum effort, the company reported performance within 0.5% of Fable 5's peak score at half the cost per task. That comparison appears in its July 24 announcement.
The announcement also describes effort settings that trade speed and model usage against performance. Those settings matter when interpreting the roundup's near-Fable headline: the reported saving belongs to a particular and configuration. It supports testing whether similar work can be completed more cheaply, rather than assuming every workload receives the same saving.
- Epoch scored Opus 5 at 159 on its Capabilities Index against Fable 5's 161, but tied the two at 161 on the software-engineering split. The gap is in general capability, not coding.
- Opus 5 landed only about one ECI point above Opus 4.8 while practitioners described it as broadly better, which is the case for the argument that current public benchmarks are saturating and need to get harder.
- One evaluator found Opus 5 scoring higher on FrontierCode at medium effort than at high effort, breaking the assumption that more monotonically helps. If that holds, your effort setting is a deployment decision, not a dial to max out.
- Aggregate indices compress coding versus non-coding , effort scaling, best-of-n gains, tool reliability and cost into one number. Opus 5 shows the cost: the single score hid a model that is stronger at software engineering than the headline implies.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- test-time compute — Spending more computation when the model answers — thinking longer, trying multiple attempts — to buy accuracy without training a bigger model.
- agent skill — A reusable instruction file that teaches an agent how to do one job well — the procedure, the tools, and what counts as done.
“Community response noted the model appears only +1 ECI point vs Opus 4.8 , which some readers considered too small relative to qualitative gains”
“The main criticism is not that Opus 5 is weak, but that benchmarking around it is unstable, underspecified, or misaligned with user impressions”
“For expert readers, the more substantive signal is that even benchmark skeptics are mostly arguing about how much better Opus 5 is , not whether it belongs at the frontier.”
“If more effort hurts on certain distributions, then deployment policy matters almost as much as base model quality.”
“The launch lands amid a broader shift from static chat benchmarks toward agentic evaluations : browser use, tool invocation, parallel task execution, and software engineering loop completion.”


 article[AINews] Claude Opus 5.5, the new default model for AINews — and everybody cuts prices 40-50%www.latent.space
 article[AINews] Claude Fable/Mythos 5.1: new SOTA model, 75% cache price cut but 70% more output tokenswww.latent.space
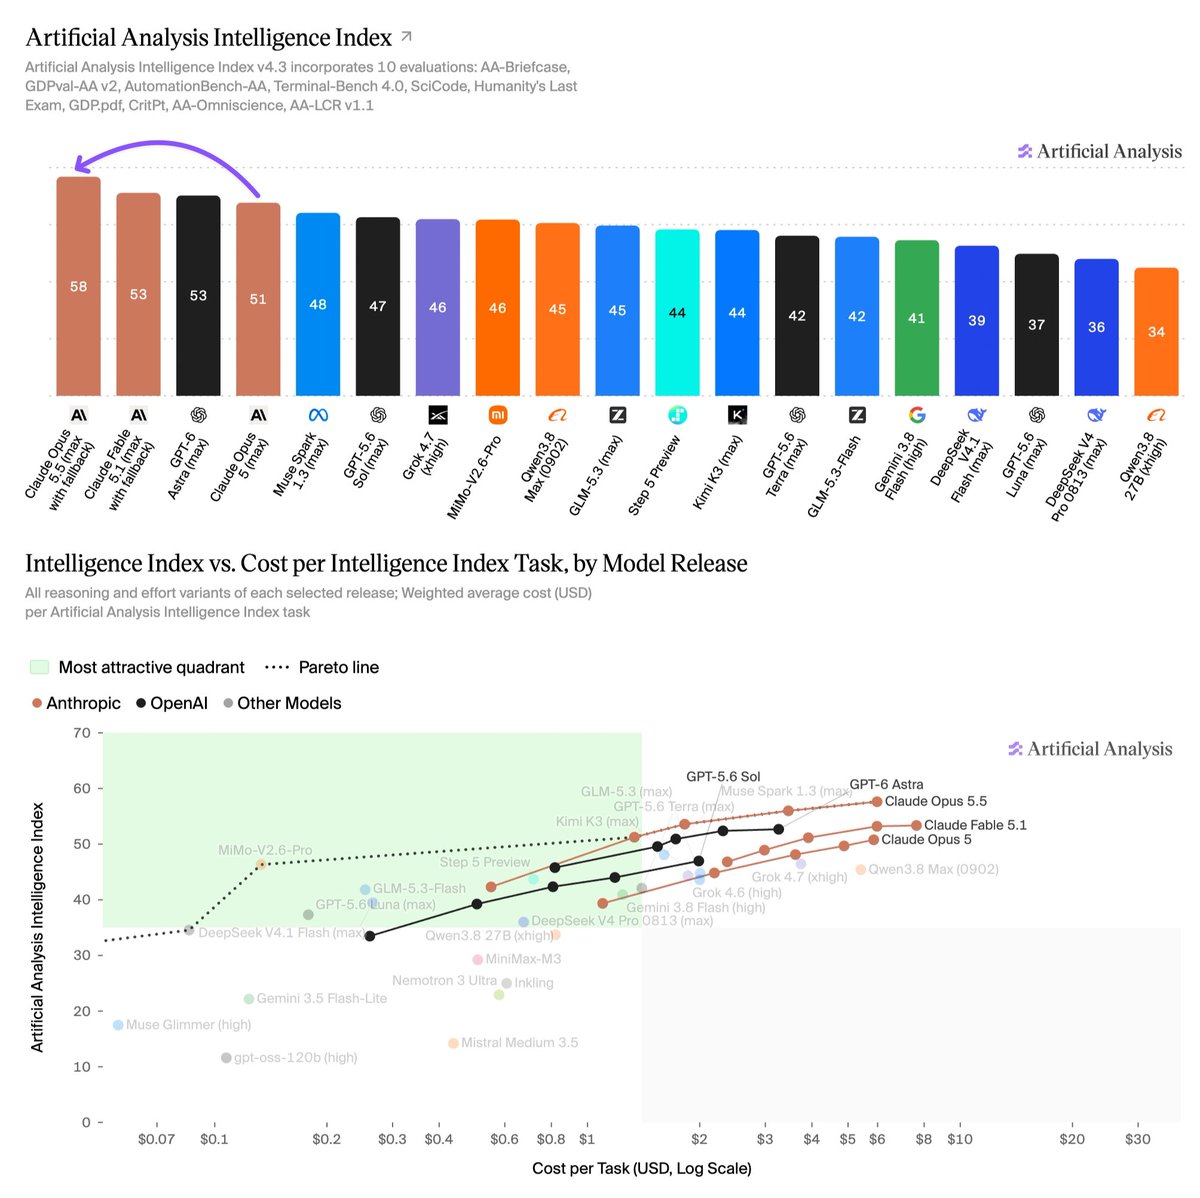 postArtificial Analysis: Opus 5.5 Tops Intelligence Index With Price CutArtificialAnlys
Checking sign-in…
Loading comments…