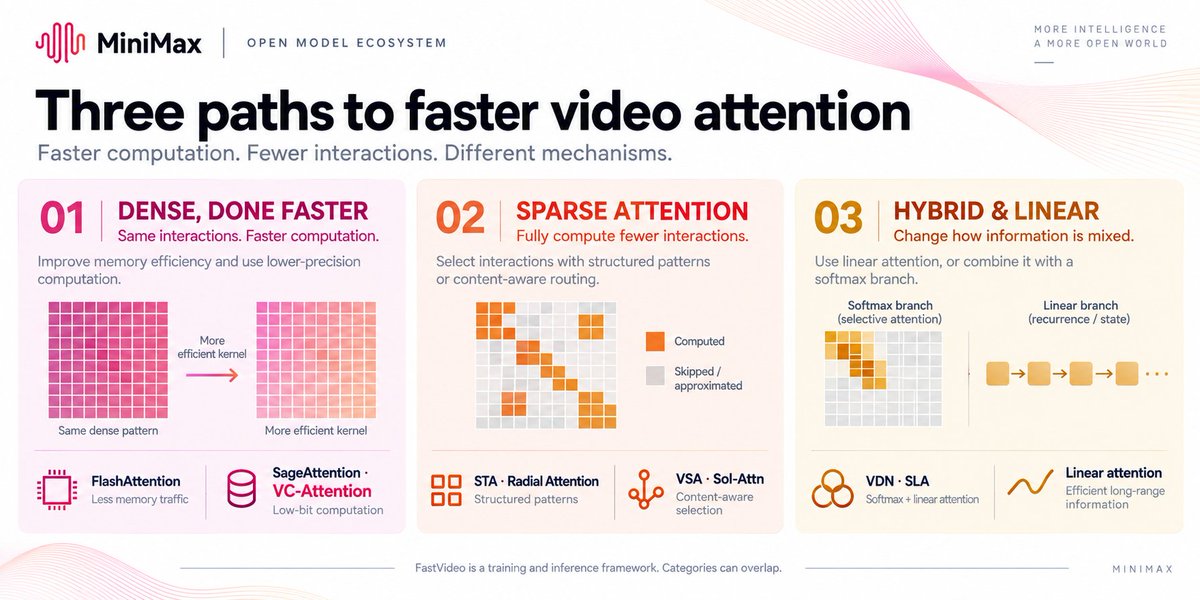
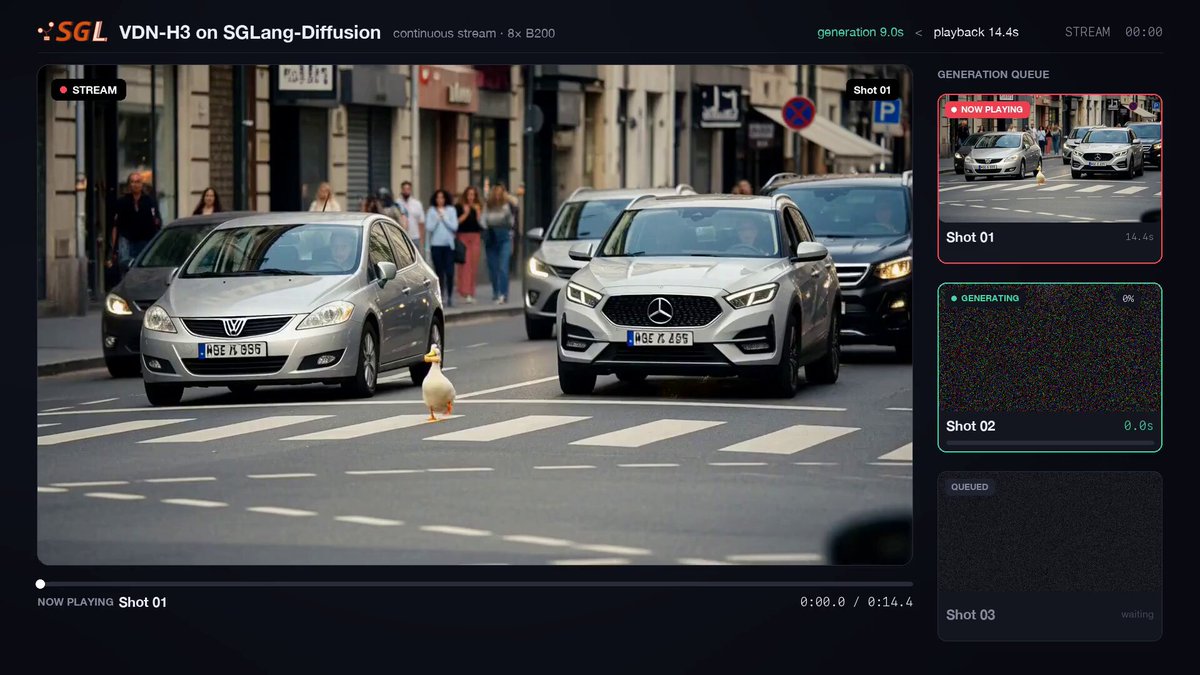
More ways to build with MiniMax-H3. 🐮
Great to see model optimization and AMD inference engineering come together to give creators a faster feedback loop.⚡️ https://t.co/OQkKnO6rKq
MiniMax's post points to AMD's inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → engineering work on its H3 video generation model, without stating a specific benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → number in the post itself. AMD's own day-0 support announcement confirms MiniMax-H3 now runs on AMD's Instinct MI300X and MI355X GPUs through an optimized software stack, giving teams building on H3 a second hardware path alongside Nvidia GPUs instead of waiting for the community to build AMD support after the fact.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.