MiniMax Adds M3.1 Flash Preview to Token Plan
- Source
- x.com
- Date

MiniMax-M3.1 Flash Preview is now live on the Token Plan! Faster, lighter, and built for teams running high-volume, latency-sensitive workloads, now available under your existing Token Plan subscription, no extra setup required. Try it today: https://t.co/ng3AyOvQE7 https://t.co/9ZrrmGU3Bz
Context
MiniMax made a preview of its M3.1 Flash model available on its Plan subscription on September 27, saying that existing subscribers can use it with no extra setup. MiniMax describes the model as faster and lighter, and built for teams running high-volume, latency-sensitive workloads, meaning work that sends many requests and needs each answer back quickly. The announcement does not say what the model is faster or lighter than, and it gives no benchmarks, prices, usage limits or . The plan page linked from the post returned no readable text, so none of those details can be established from this source.
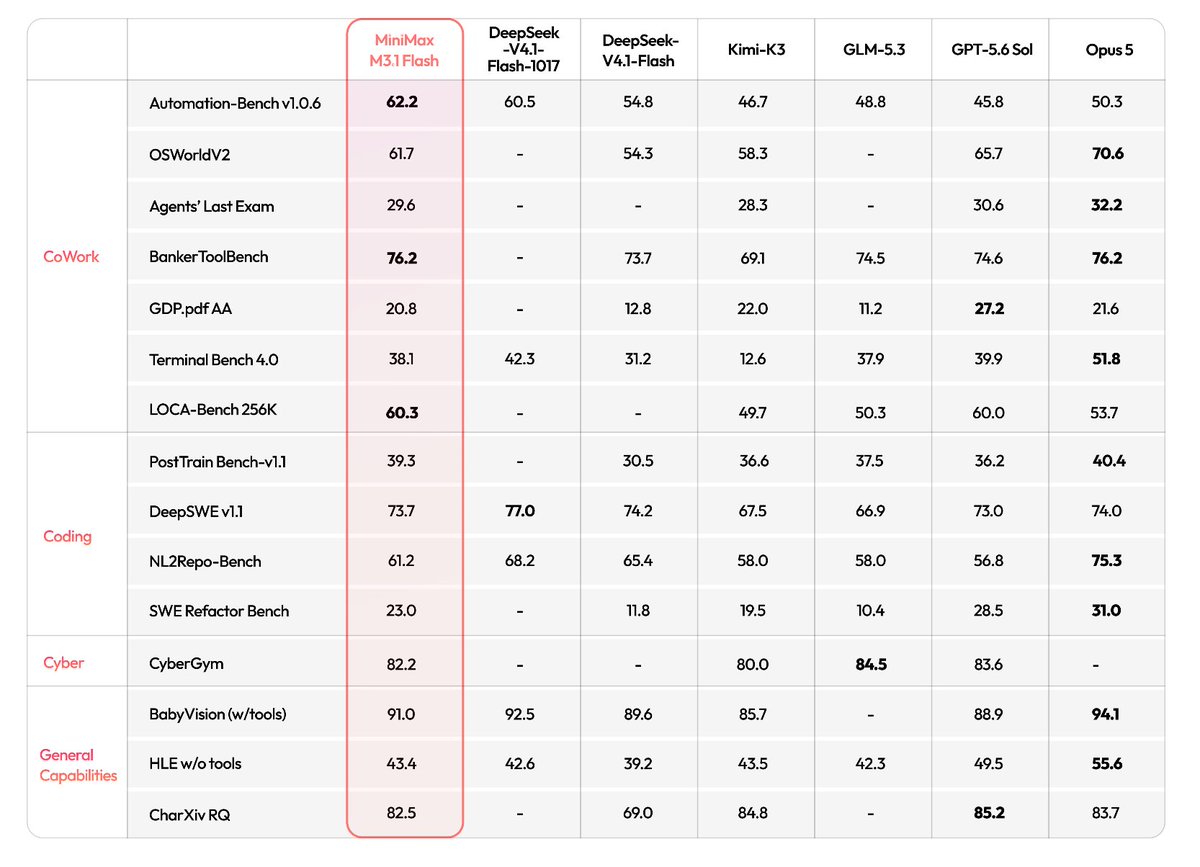
What the post does establish is access: according to MiniMax, a team already on the Token Plan can try the preview under its current subscription. The preview came ahead of the model's wider release. In October MiniMax announced M3.1 Flash itself and said its weights would follow on October 23, as later Intel coverage records, and that later announcement is where MiniMax made its claims for the model.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…