StepFun debuts StepAudio 3 voice model family, tops real-time benchmarks
- Source
- x.com
- Date

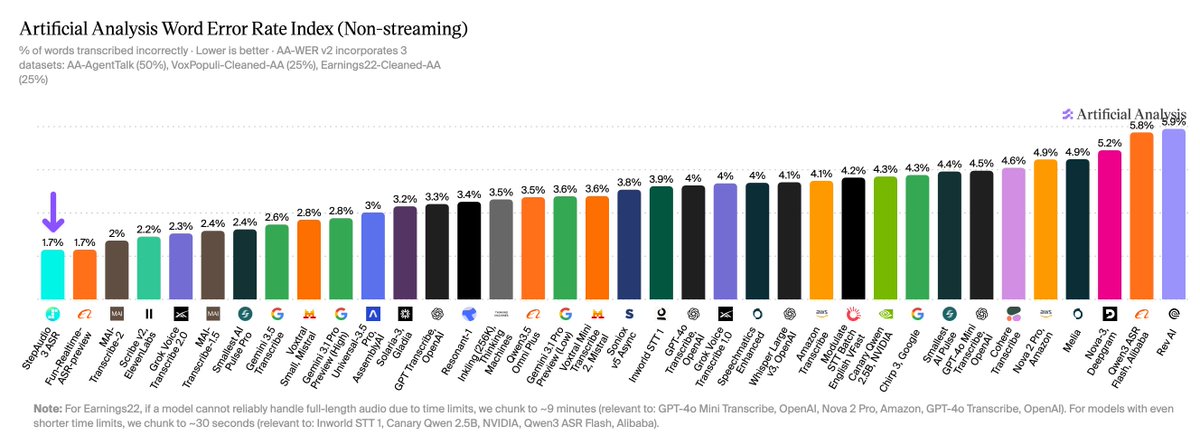
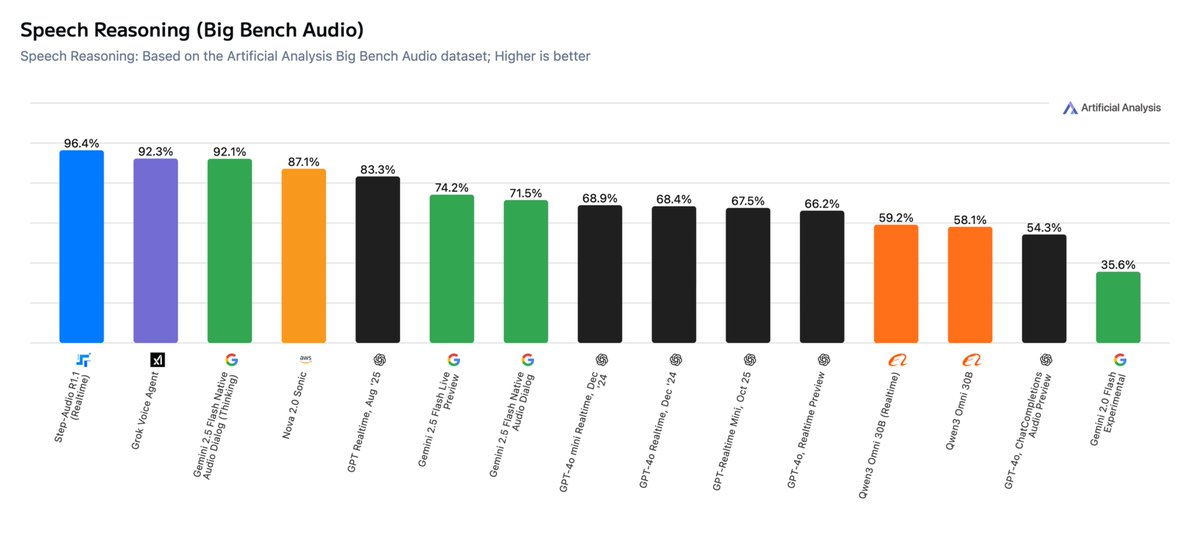
Introducing StepAudio 3, our new family of 5 audio models for real-time voice, speech recognition, speech generation, audio generation and music. Realtime ranks #1 on Artificial Analysis for both Conversational Dynamics (98.9%) and Speech Reasoning (99.7%). ASR reaches 1.7% WER, matching the best result on the leaderboard. Build voice agents that handle interruptions, reason while speaking, and call tools. Transcribe speech, generate expressive voices, and create full audio scenes and music. Available now: Voice AI Lab: https://t.co/9lQaKPc5AF Blog:

Context
StepFun released StepAudio 3, a family of five audio models covering real-time voice conversation, speech-to-text transcription, text-to-speech generation, sound-effect generation, and music. The real-time conversation model is built to handle interruptions, reason while still speaking, and call external tools mid-conversation rather than only converting speech to text and back.
StepFun's own thread claims the real-time model ranks #1 on Artificial Analysis's Conversational Dynamics and Speech Reasoning categories, at 98.9% and 99.7% respectively, and that its transcription model reaches 1.7% word error rate. Artificial Analysis's own leaderboard corroborates the transcription result, placing StepAudio 3's ASR at the top of its speech-to-text accuracy index, effectively tied with Alibaba's Fun-Realtime-ASR-preview at the same 1.7% rate; the conversational-dynamics and speech-reasoning figures come only from StepFun's own announcement and were not independently checked here.
 postStepFun Open-Sources Step Code, a CLI Coding Agent Benchmarked on Terminal-Bench
 postStepFun Open-Sources onPanda, Its Internal LLM Annotation and Debug Tool
 postvLLM gains an experimental Attention-FFN disaggregation plugin for MoE
- postOpenRouter free tier for Step 3.5 Flash jumps to 10K calls a day
Checking sign-in…
Loading comments…