StepFun's StepAudio 3 ASR Tops Speech-to-Text Accuracy Leaderboard
- Source
- x.com
- Date

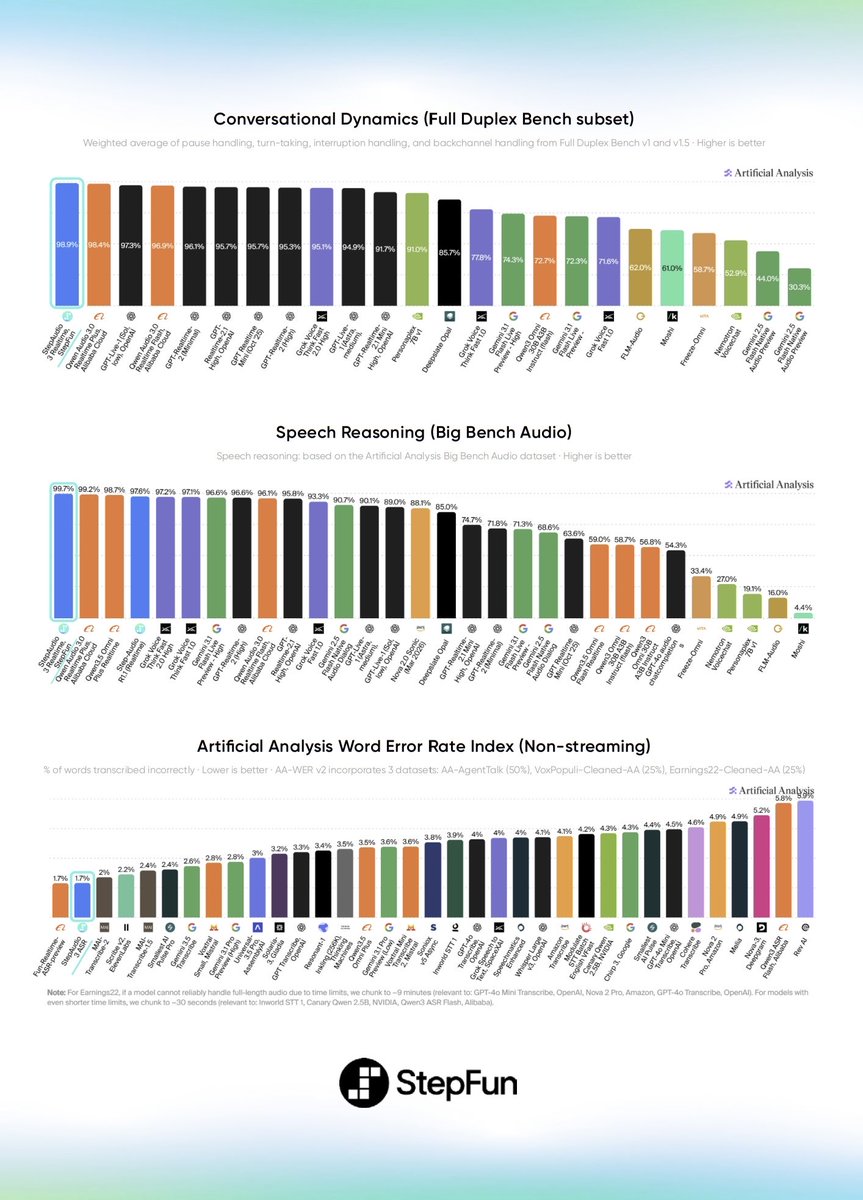
StepFun has released StepAudio 3 ASR, ranking #1 on the AA-WER Index for non-streaming Speech to Text with 1.7% WER, a notable improvement on StepAudio 2.5 ASR (4.7%) StepAudio 3 ASR is StepFun's new Speech to Text model, available through the StepFun API for non-streaming transcription, and the first StepFun model to reach the top of our non-streaming Speech to Text leaderboard. Key takeaways ➤ Accuracy: StepAudio 3 ASR scores 1.7% on the AA-WER Index, effectively tied with Alibaba's Fun-Realtime-ASR-preview at 1.7%. It leads on AA-AgentTalk, our held-out voice-agent dataset, at 1.4%, but trails on long-form Earnings22 calls at 2.8%, where Fun-Realtime-ASR-preview scores 1.8% ➤ Speed: The model transcribes at a speed factor of 88x real time, behind MAI-Transcribe-2 at 374x, Smallest AI Pulse Pro at 285x and Grok Voice Transcribe 2.0 at 154x, roughly level with ElevenLabs Scribe v2 at 84x and Gemini 3.5 Transcribe at 91x, and ahead of Fun-Realtime-ASR-preview at 20x ➤ Price: StepAudio 3 ASR costs $0.40 per hour, or $6.67 per 1,000 minutes, the most expensive of the five most accurate models. MAI-Transcribe-2 and Grok Voice Transcribe 2.0 cost $1.67 per 1,000 minutes and…

Context
Artificial Analysis, an independent benchmarking firm, ranks StepFun's new StepAudio 3 ASR first on its index for non- speech-to-text, the kind that transcribes a finished recording rather than live audio. The measure is word error rate, the share of words a model transcribes incorrectly. StepAudio 3 ASR scores 1.7%, tied with Alibaba's Fun-Realtime-ASR-preview and down from 4.7% for StepFun's previous model, StepAudio 2.5 ASR. StepFun had already claimed the 1.7% figure when it launched its StepAudio 3 family days earlier; this post is the independent measurement.
How the index is built explains the result. According to the chart in the post, half of the score comes from AA-AgentTalk, Artificial Analysis's own unpublished set of speech directed at voice agents, and a quarter each from recordings of parliamentary proceedings and long corporate earnings calls. StepAudio 3 ASR leads on the voice- set at 1.4%, but on the earnings calls it scores 2.8% against 1.8% for Alibaba's model. Its top rank therefore reflects strength on short conversational speech. For long recordings like these earnings calls, the Alibaba model did better on this data.
The price is the other half of the trade. StepAudio 3 ASR costs $0.40 per hour of audio, or $6.67 per 1,000 minutes, the most of the five most accurate models. MAI-Transcribe-2 and Grok Voice Transcribe 2.0, at 2.0% and 2.3% error in the chart, cost $1.67 per 1,000 minutes, and ElevenLabs Scribe v2, at 2.2%, costs $3.67. When StepFun launched StepAudio 2.5 ASR, it listed it at $0.022 per hour, a small fraction of the new model's price. The difference between 1.7% and 2.0% is about three fewer wrong words per thousand. That gain matters most to voice-agent builders whose systems act on each transcribed word, and less to anyone transcribing large volumes where price dominates. It is also not the fastest option: it runs at 88 times real time, against 374 times for MAI-Transcribe-2, though well ahead of Fun-Realtime-ASR-preview at 20 times.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.




Checking sign-in…
Loading comments…