Hy3 lands: 295B MoE under Apache 2.0, free API for two weeks
- Source
- x.com
- Date

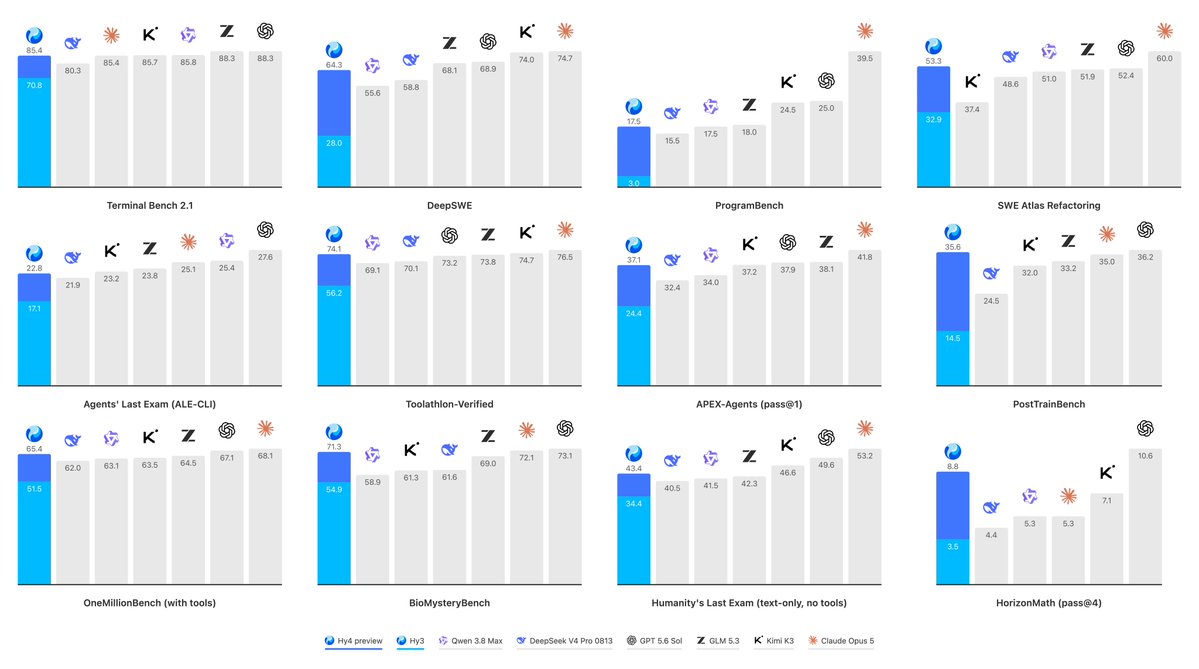
🚀Hy3 is here. 295B MoE. Best in its size class. Rivals trillion-scale flagships. Reliable and affordable for most agentic usecases. Apache 2.0. Friendly for commercial use. FREE API for 2 weeks → https://t.co/EyURKwTdgi 🤗 https://t.co/twqJpqb2SL 📖 https://t.co/4uEkIU1cW4

Hy3 is a real productivity booster. 🚀See how it handles these two workflows.


Hy3 is now live on Hermes, Kilo Code, OpenCode, OpenClaw & Cline 🚀 Free to use. Plug in and play. Give it a spin and tell us what you think 👇
Check out how this gus uses Hy3 to generate such a beautiful data analysis report. Hy3 is performing amazingly! https://t.co/MmrZdWnKqK
Context
Tencent's official Hy3 release followed the Hy3 preview with further training informed by product feedback. The model card describes a model with 295 billion parameters, of which 21 billion are active for each text . This design uses a selected portion of the model's capacity for each processing step.
Hy3's downloadable weights are released under Apache 2.0, providing a route for developers to run and adapt the model. The launch announcement also offered a two-week API trial; that was a launch promotion, rather than an ongoing promise of free access.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
 articleExplorationBench: Feedback and Self-Designed Probes Drive Agent Discovery
 postHy Image3.5 preview is live. 🚀 Professional-grade image generation, +30% win…
 postTencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
 postTencent Hunyuan open-sources AuK, a unified speech generation and editing model
Checking sign-in…
Loading comments…