World Labs' Atlas takes camera paths as input and returns real 3D
- Source
- x.com
- Date

Introducing Atlas: The worlds first multimodal world model that generates image and video frames with pixel-perfect camera control and reconstructs them in 3D. Model the world, move the camera, and simulate space & time.
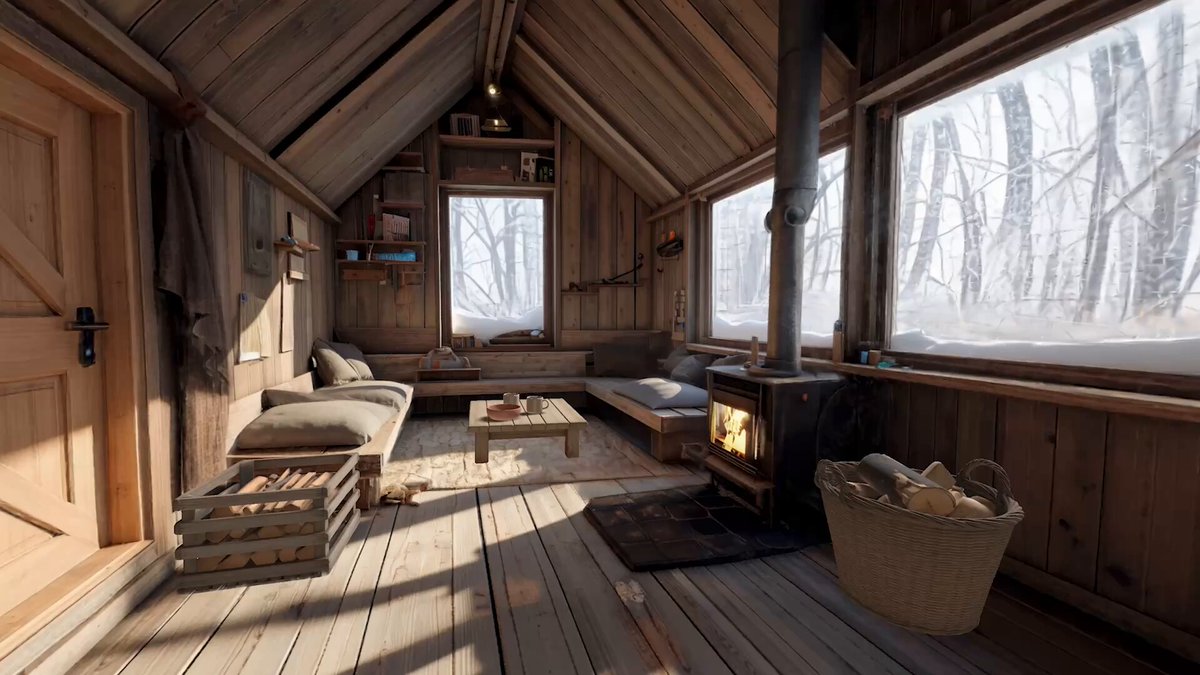
We pre-trained Atlas from scratch to take multimodal inputs, including camera movement, and turn it into 3D grounded views. Atlas puts you in control: direct the views, reconstruct real spaces with your inputs, and build explorable worlds. Read more: https://www.worldlabs.ai/blog/atlas
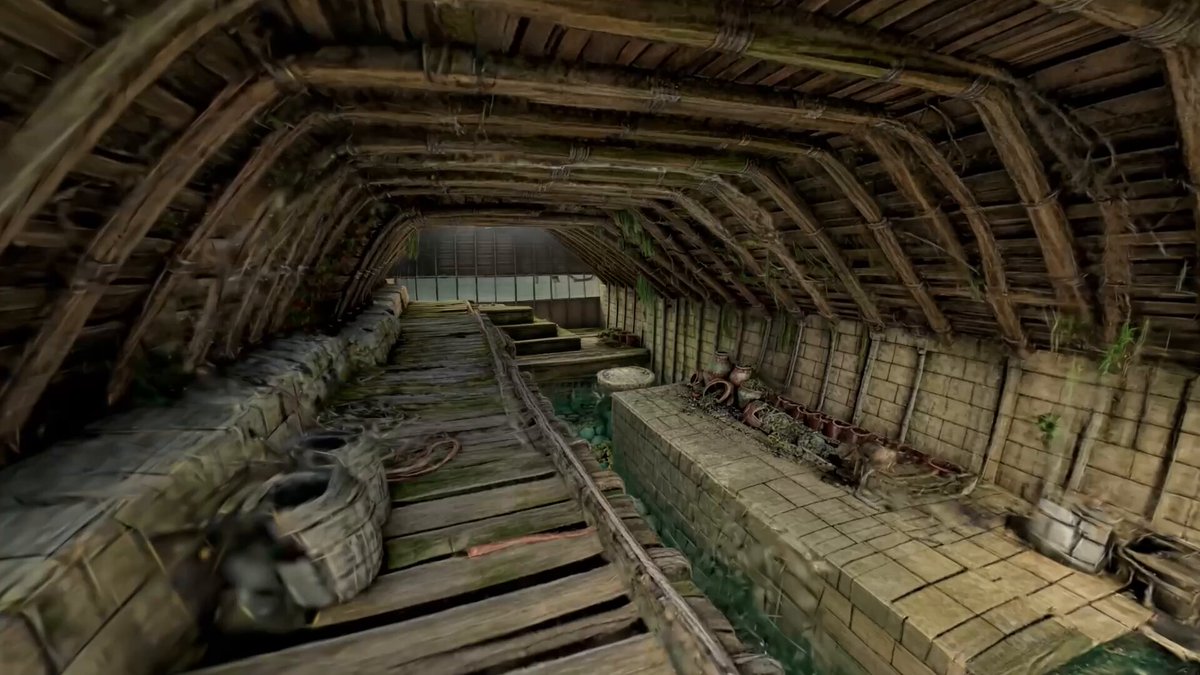
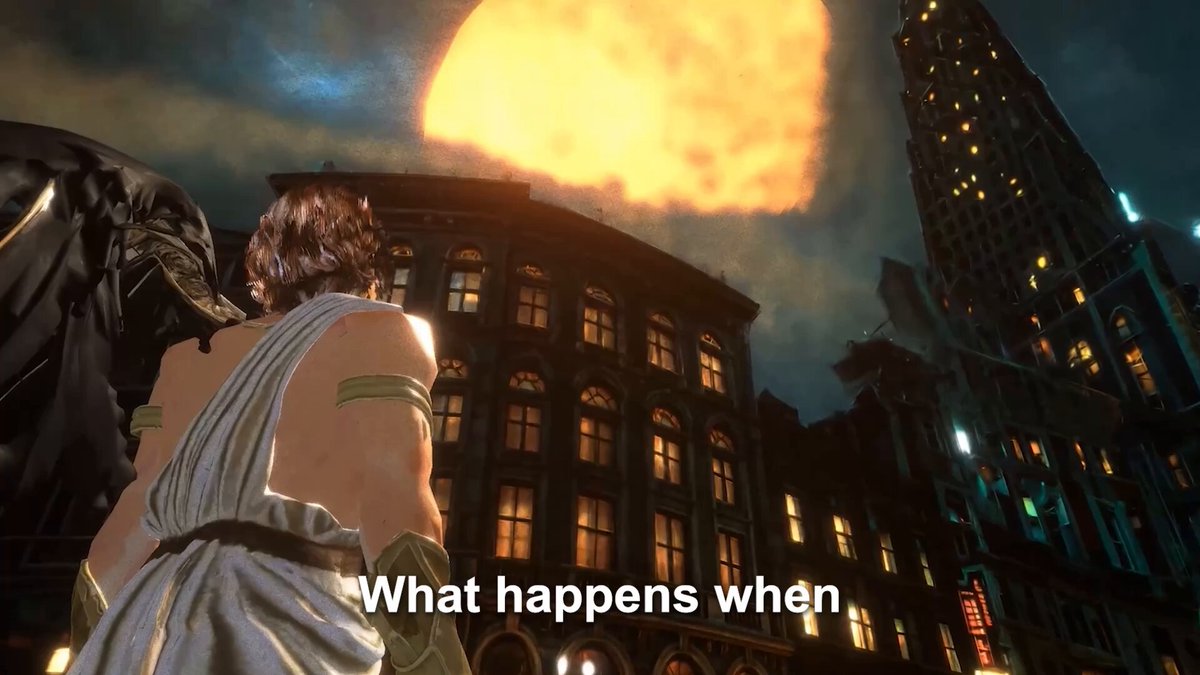
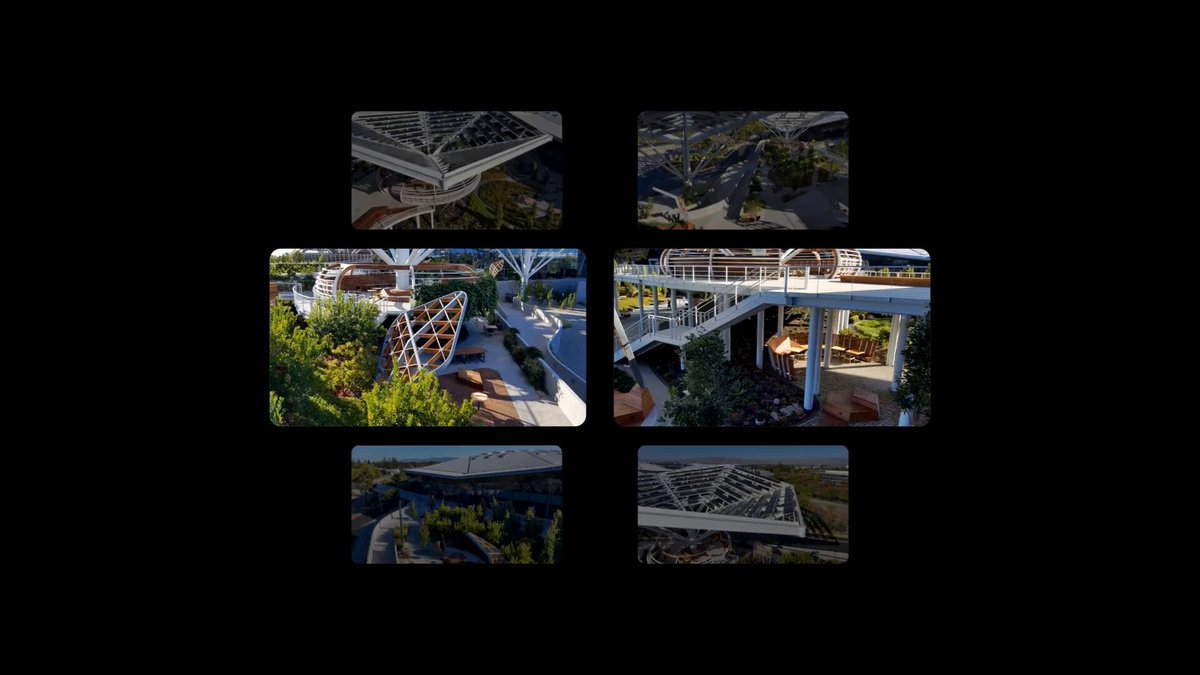
By positioning multiple input views within the models spatial context, Atlas allows you to generate image and video frames with precise control. Here, we hand-designed a camera trajectory to generate a 1 minute video at 1440p resolution from seven reference images.
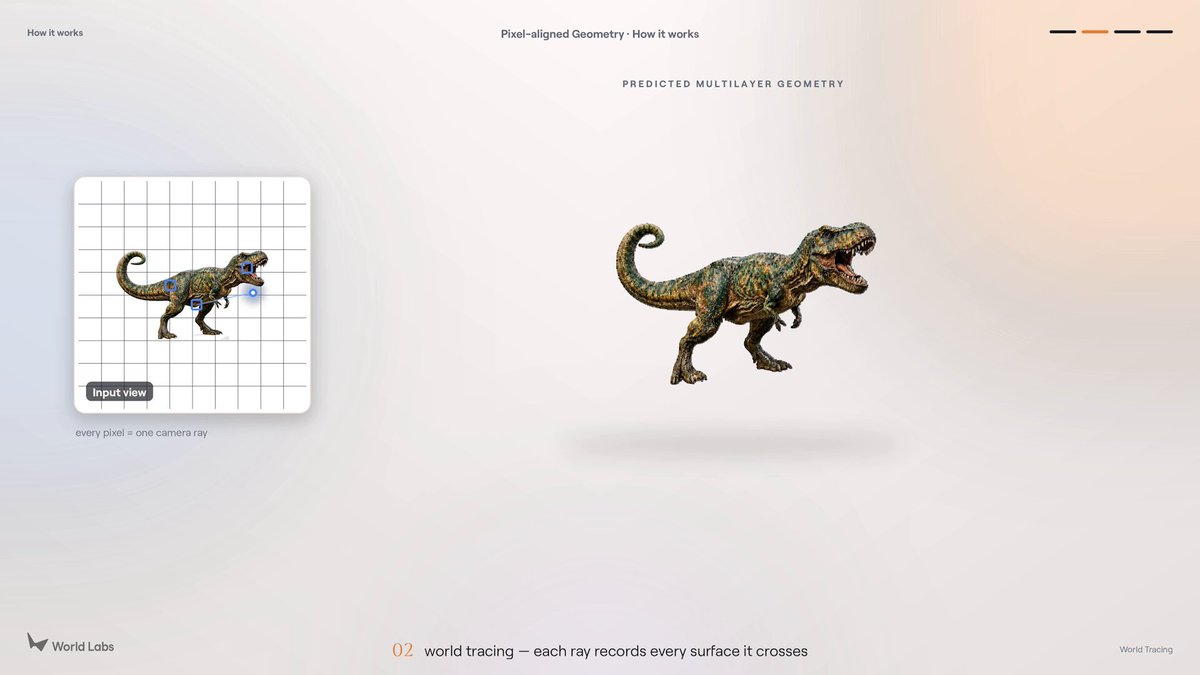
Atlas also outputs explicit 3D from one to many input images, beating top open source reconstruction models. Passing more images gives Atlas more context: the more it sees, the less it imagines.
Context
World Labs' Atlas accepts camera positions and directions as inputs alongside reference images. Its technical introduction explains that each image occupies a location in a shared spatial . The model uses that context to generate views along a specified camera path, giving creators a direct way to stage movement through a scene.
Atlas can also produce depth information and explicit 3D outputs, including point clouds and Gaussian splats. Those outputs can support exploration beyond a fixed video. Where the reference images leave gaps, however, the model invents plausible content; adding more views constrains that invention. A generated reconstruction can therefore mix observed structure with imagined surroundings.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.

Checking sign-in…
Loading comments…