DeepSeek V4.1 Flash Hits 1 Trillion Tokens in a Day on OpenRouter
- Source
- x.com
- Date
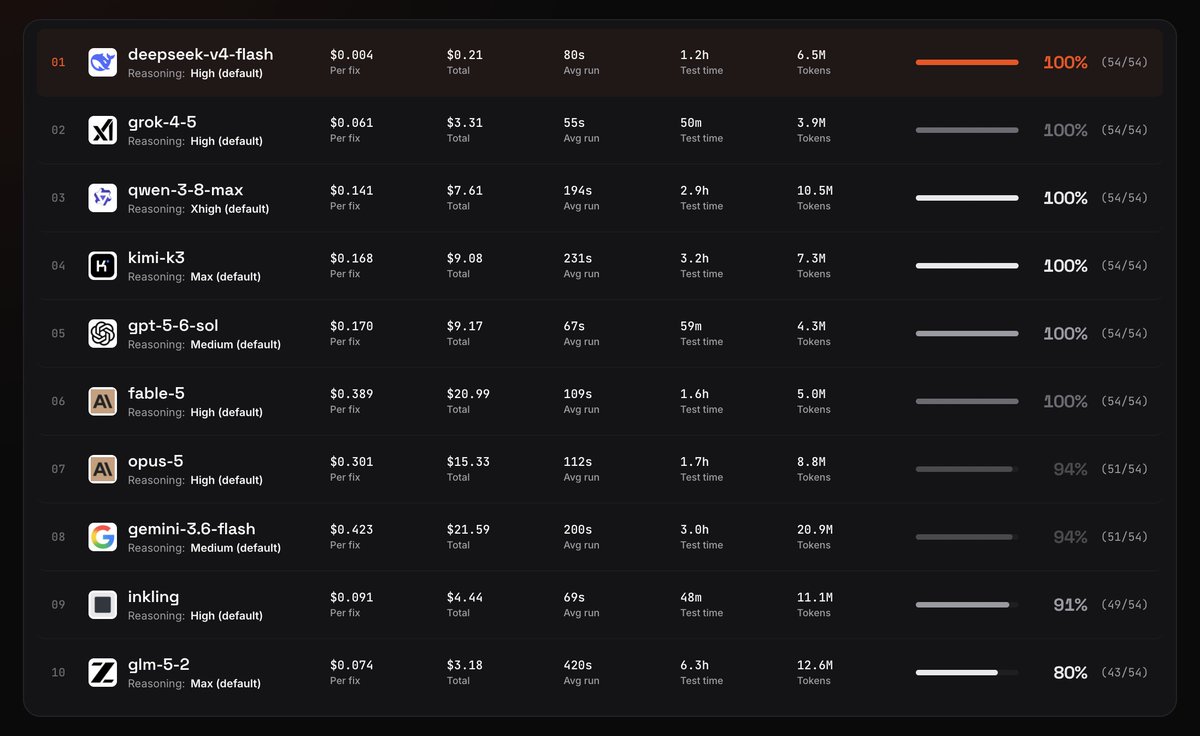
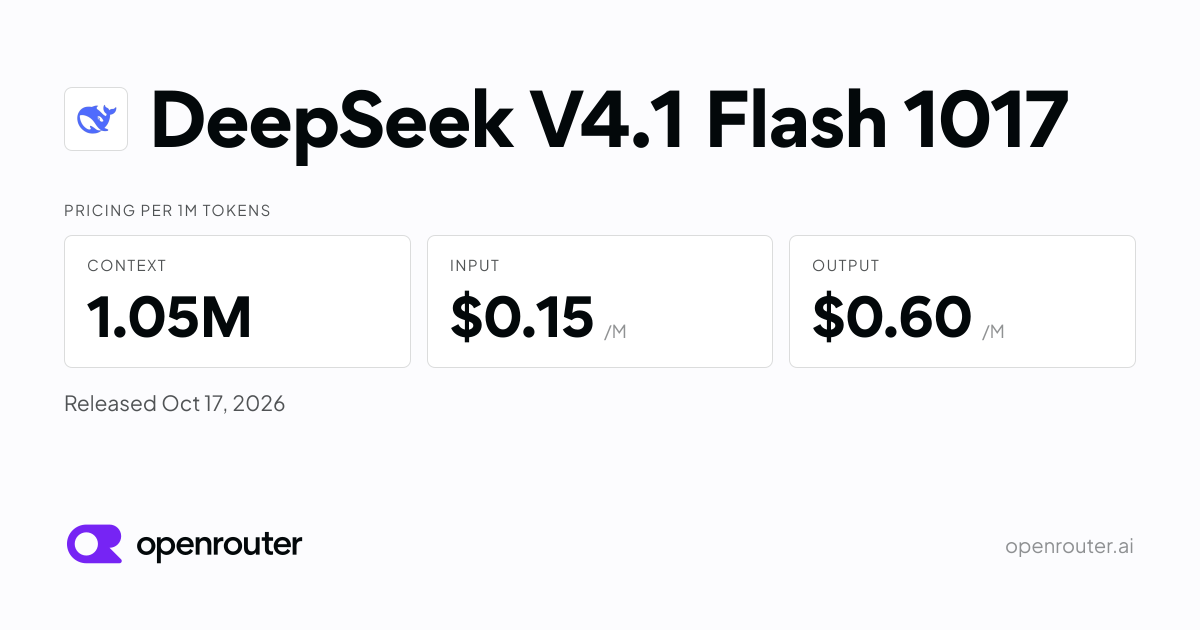
OpenRouter reported that DeepSeek's new V4.1 Flash model processed 1 trillion tokens in its first day on the platform, putting it on pace to be the largest paid model launch OpenRouter has tracked over its first 48 hours. Ninety percent of those tokens were served from cache, and the effective price came out to roughly $0.006 per million tokens, about five times cheaper than GLM-5.3 Flash. That combination, heavy cache reuse plus a low headline price, is what actually drives adoption at this scale rather than benchmark scores alone. A model can top an intelligence leaderboard and still see little real traffic if it is expensive to serve at volume. DeepSeek V4.1 Flash's first day numbers are a market signal that the model is genuinely cheap to run in production, not just cheap on paper, which matters more to teams choosing a default model than another round of benchmark comparisons.

DeepSeek V4.1 Flash: 1T tokens in 24 hours on OpenRouter, and is on pace for the biggest 48 hours of any paid model launch at ~2.8T. 90% of those tokens were cache reads, priced by the market at ~$0.006/M, 5x cheaper than comparable models like GLM-5.3 Flash

Context
OpenRouter, a marketplace that routes API requests to many different AI models, reports DeepSeek V4.1 Flash processed 1 trillion in its first 24 hours on the platform, and was on pace for roughly 2.8 trillion tokens in 48 hours, which OpenRouter calls the biggest 48-hour total it has tracked for a paid model launch.
OpenRouter says 90% of those tokens were cache reads, meaning the model reused previously processed instead of reprocessing it from scratch, and the market priced those cache reads at about $0.006 per million tokens, roughly five times cheaper than a comparable model, GLM-5.3 Flash. This followed a day-zero release in which NVIDIA's vLLM software supported the model cleanly while AMD's did not yet work.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.





Checking sign-in…
Loading comments…