Since its release, FinFIRST has drawn a lot of interest.
- Source
- Ant Ling
- Date

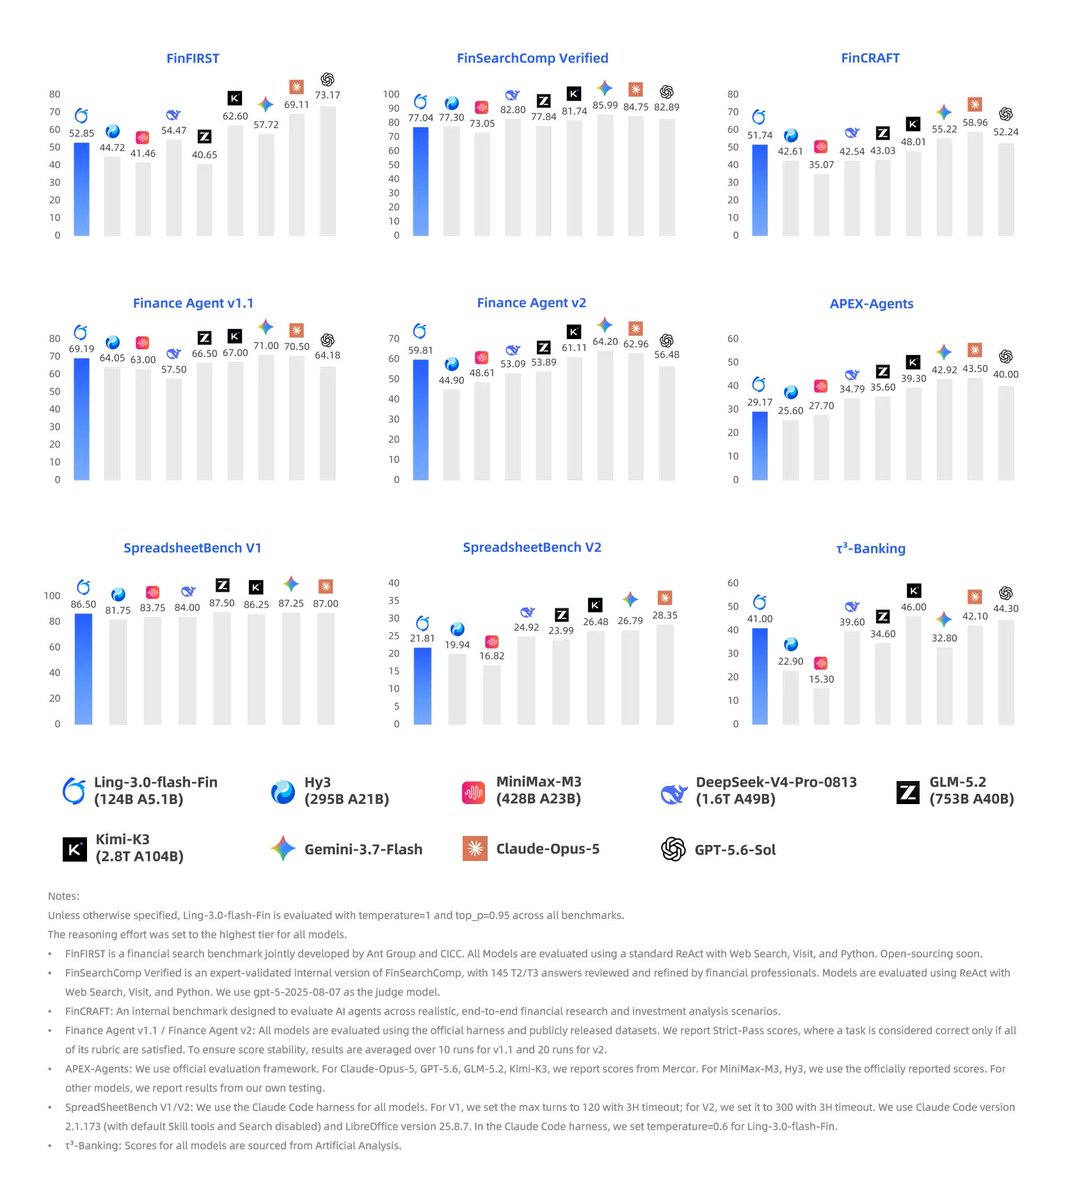
Since its release, FinFIRST has drawn a lot of interest. Built with finance experts, it uses atomic rubrics to assess both answers and evidence, including how agents search, handle timely real world tasks, combine sources, choose reliable evidence, calculate and make results easy to verify. 🧵

Context
FinFIRST, from Ant Ling, uses what it calls atomic rubrics: rather than a single pass or fail check on a final number, it breaks a finance task into scored components covering how an searches for information, handles time-sensitive real-world questions, combines multiple sources, judges which evidence is reliable, performs the calculation, and leaves its reasoning easy for a human to check.
The post introducing this is the start of a longer thread, and the specific model scores and comparisons it references were not captured here, so this account is limited to describing what FinFIRST evaluates rather than reporting any result it produced.



Checking sign-in…
Loading comments…