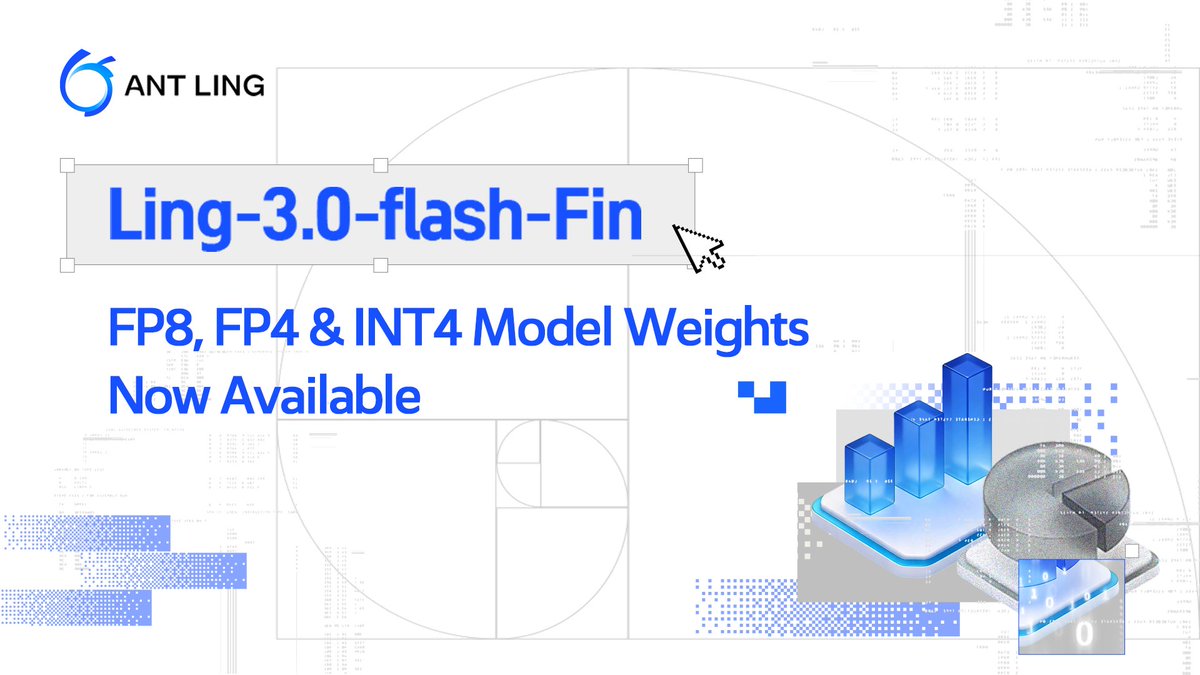
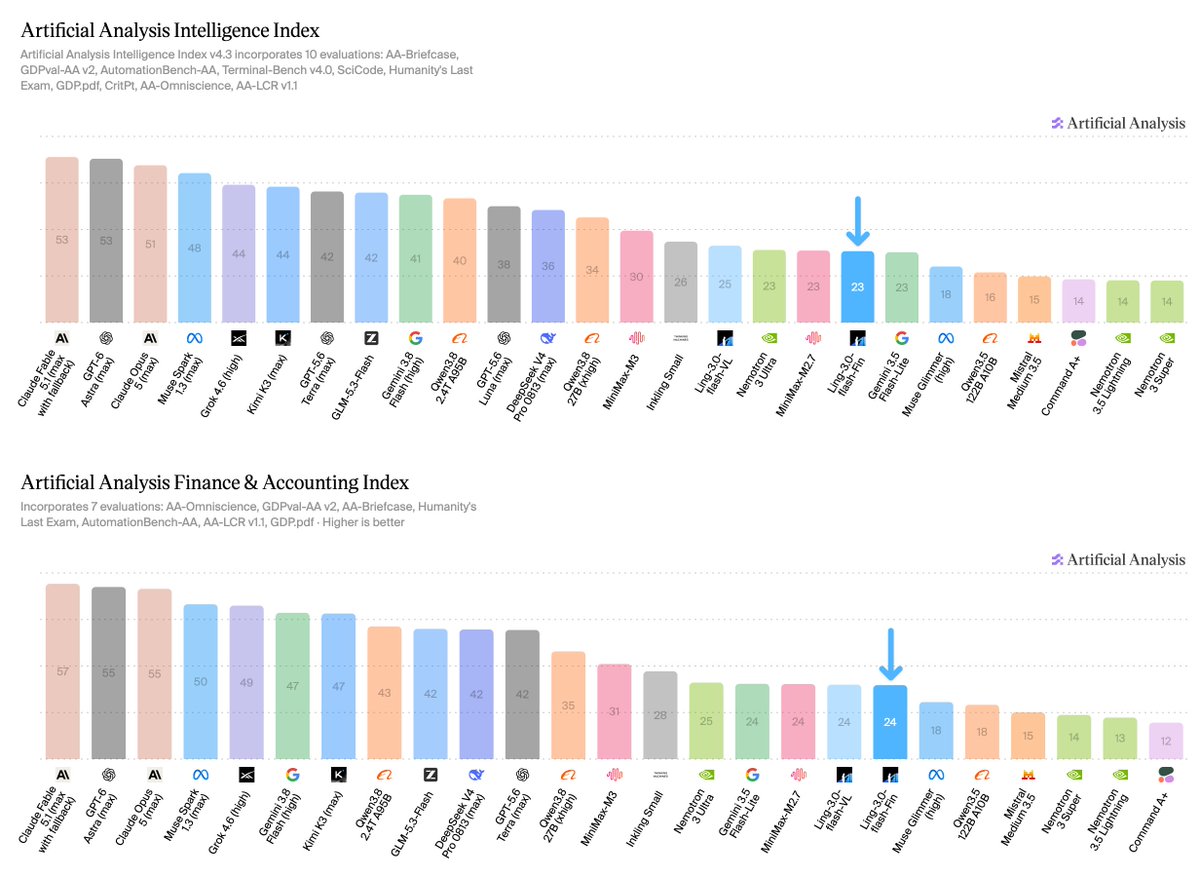
Thanks @ValsAI for the high-caliber eval! The term "flash" is a bit "misleading" now. With 124B total size and 5.1B activation, Ling-3.0-flash-fin is a "flash lite" with high intelligence density. Enjoy the free API while it last. We also have fp4 quant to be used on local AI 😛 https://t.co/SO2wIBC7jN
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
Why it matters
Clarifies that despite the "flash" name, Ling-3.0-flash-fin is a 124B-parameter mixture-of-expertsA model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.Full definition → model with 5.1B active parameters, and that an fp4 quantizationShrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.Full definition → version exists for local deployment.