Ling-3.1-flash: 1M-context MoE from Ant Group
- Source
- x.com
- Date

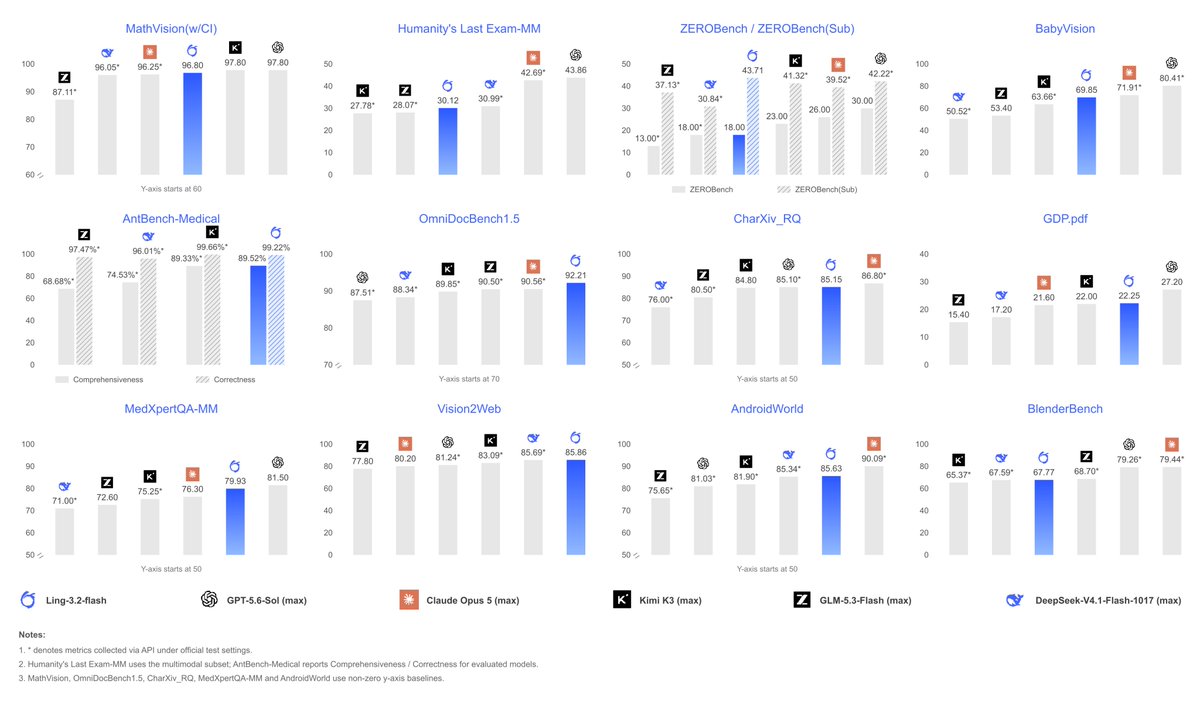
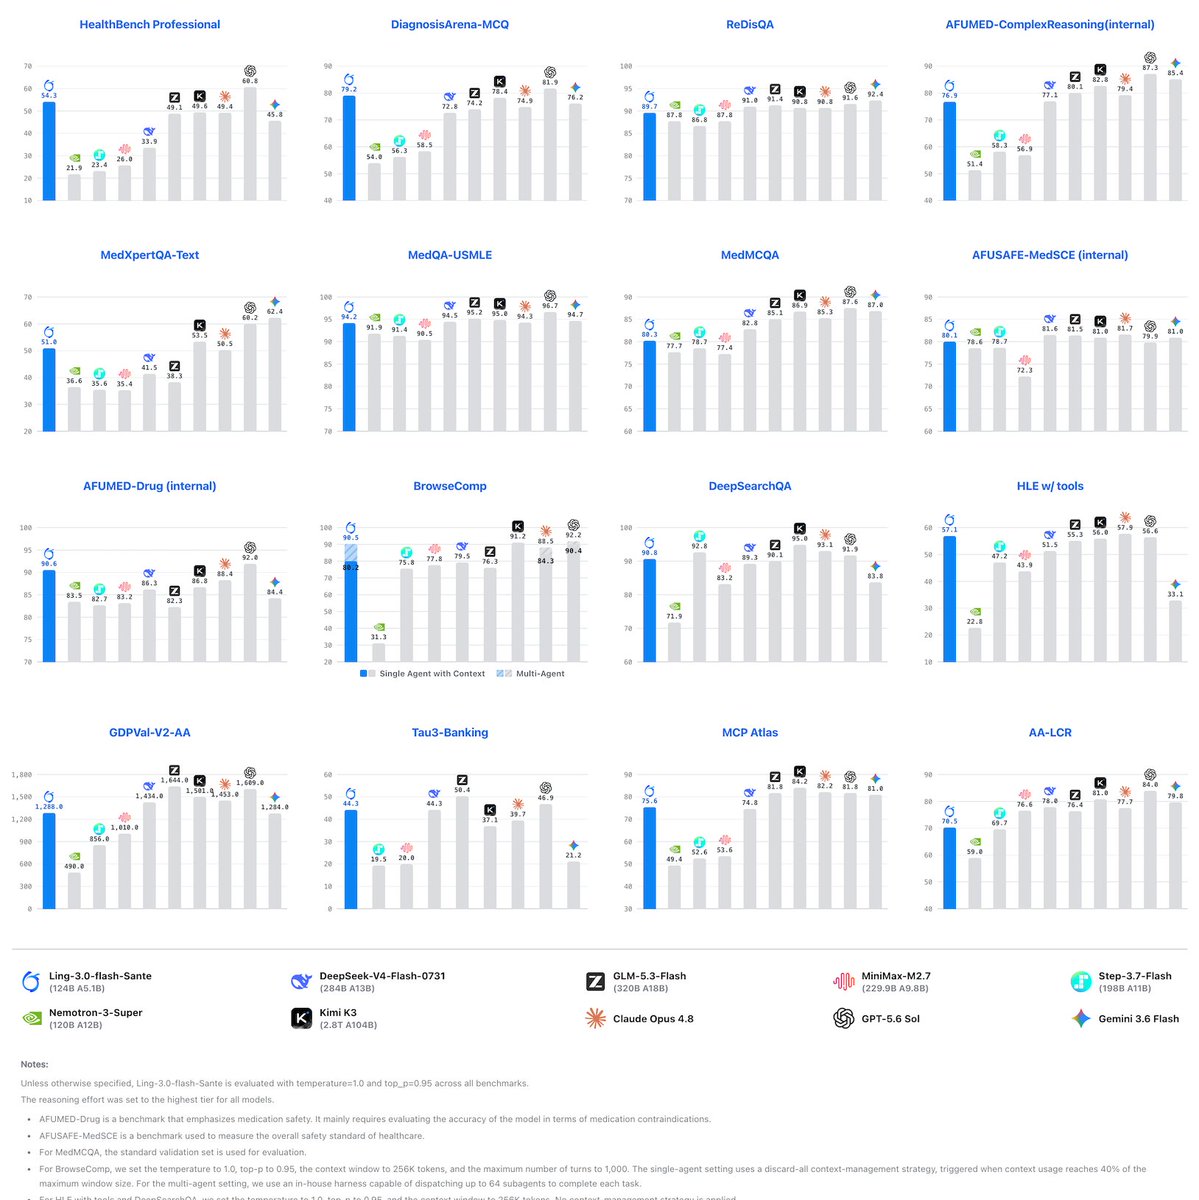
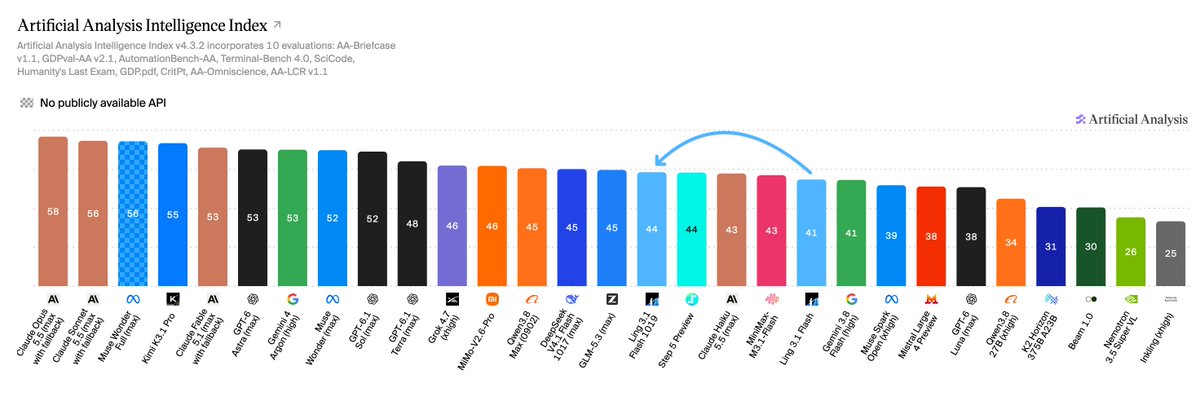
Meet Ling-3.1-flash: ~560B total params, ~25B active/token, up to 1M-token context. We plan to open-source the model soon. Across work, coding & healthcare: 1,673 Elo on GDPVal-AA v2.1, 75.16 on FrontierSWE, and 65.35 on HealthBench Professional.

Context
Ling-3.1-flash is a very large model that uses only a small part of itself for each , which is how it pairs about 560 billion parameters with far less computation per token than its full size suggests. Ant Ling announced that about 25 billion parameters are active per token. Parameters are the learned numbers inside a model, and activating only a fraction of them for each step reduces the computing work per token. The model also accepts up to a million tokens of , which is the amount of text it can take in at once, enough for long documents or large chunks of code.
The figures come from Ant Ling itself, and the post's text gives them without figures for other models to compare against: 1,673 Elo on GDPVal-AA v2.1, 75.16 on FrontierSWE and 65.35 on HealthBench Professional. The post presents these as results across work, coding and healthcare. An Elo score is a relative rating, so it means little without other models' ratings next to it. At announcement, Ant Ling said only that it planned to open-source the model soon. Two weeks later, Intel logged a Ling-3.1-flash release on Hugging Face from the inclusionAI organization.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
Checking sign-in…
Loading comments…