LFM2.5-VL-3B for Better and Faster Vision Capabilities for the Edge
Source
huggingface.co
Date
Context
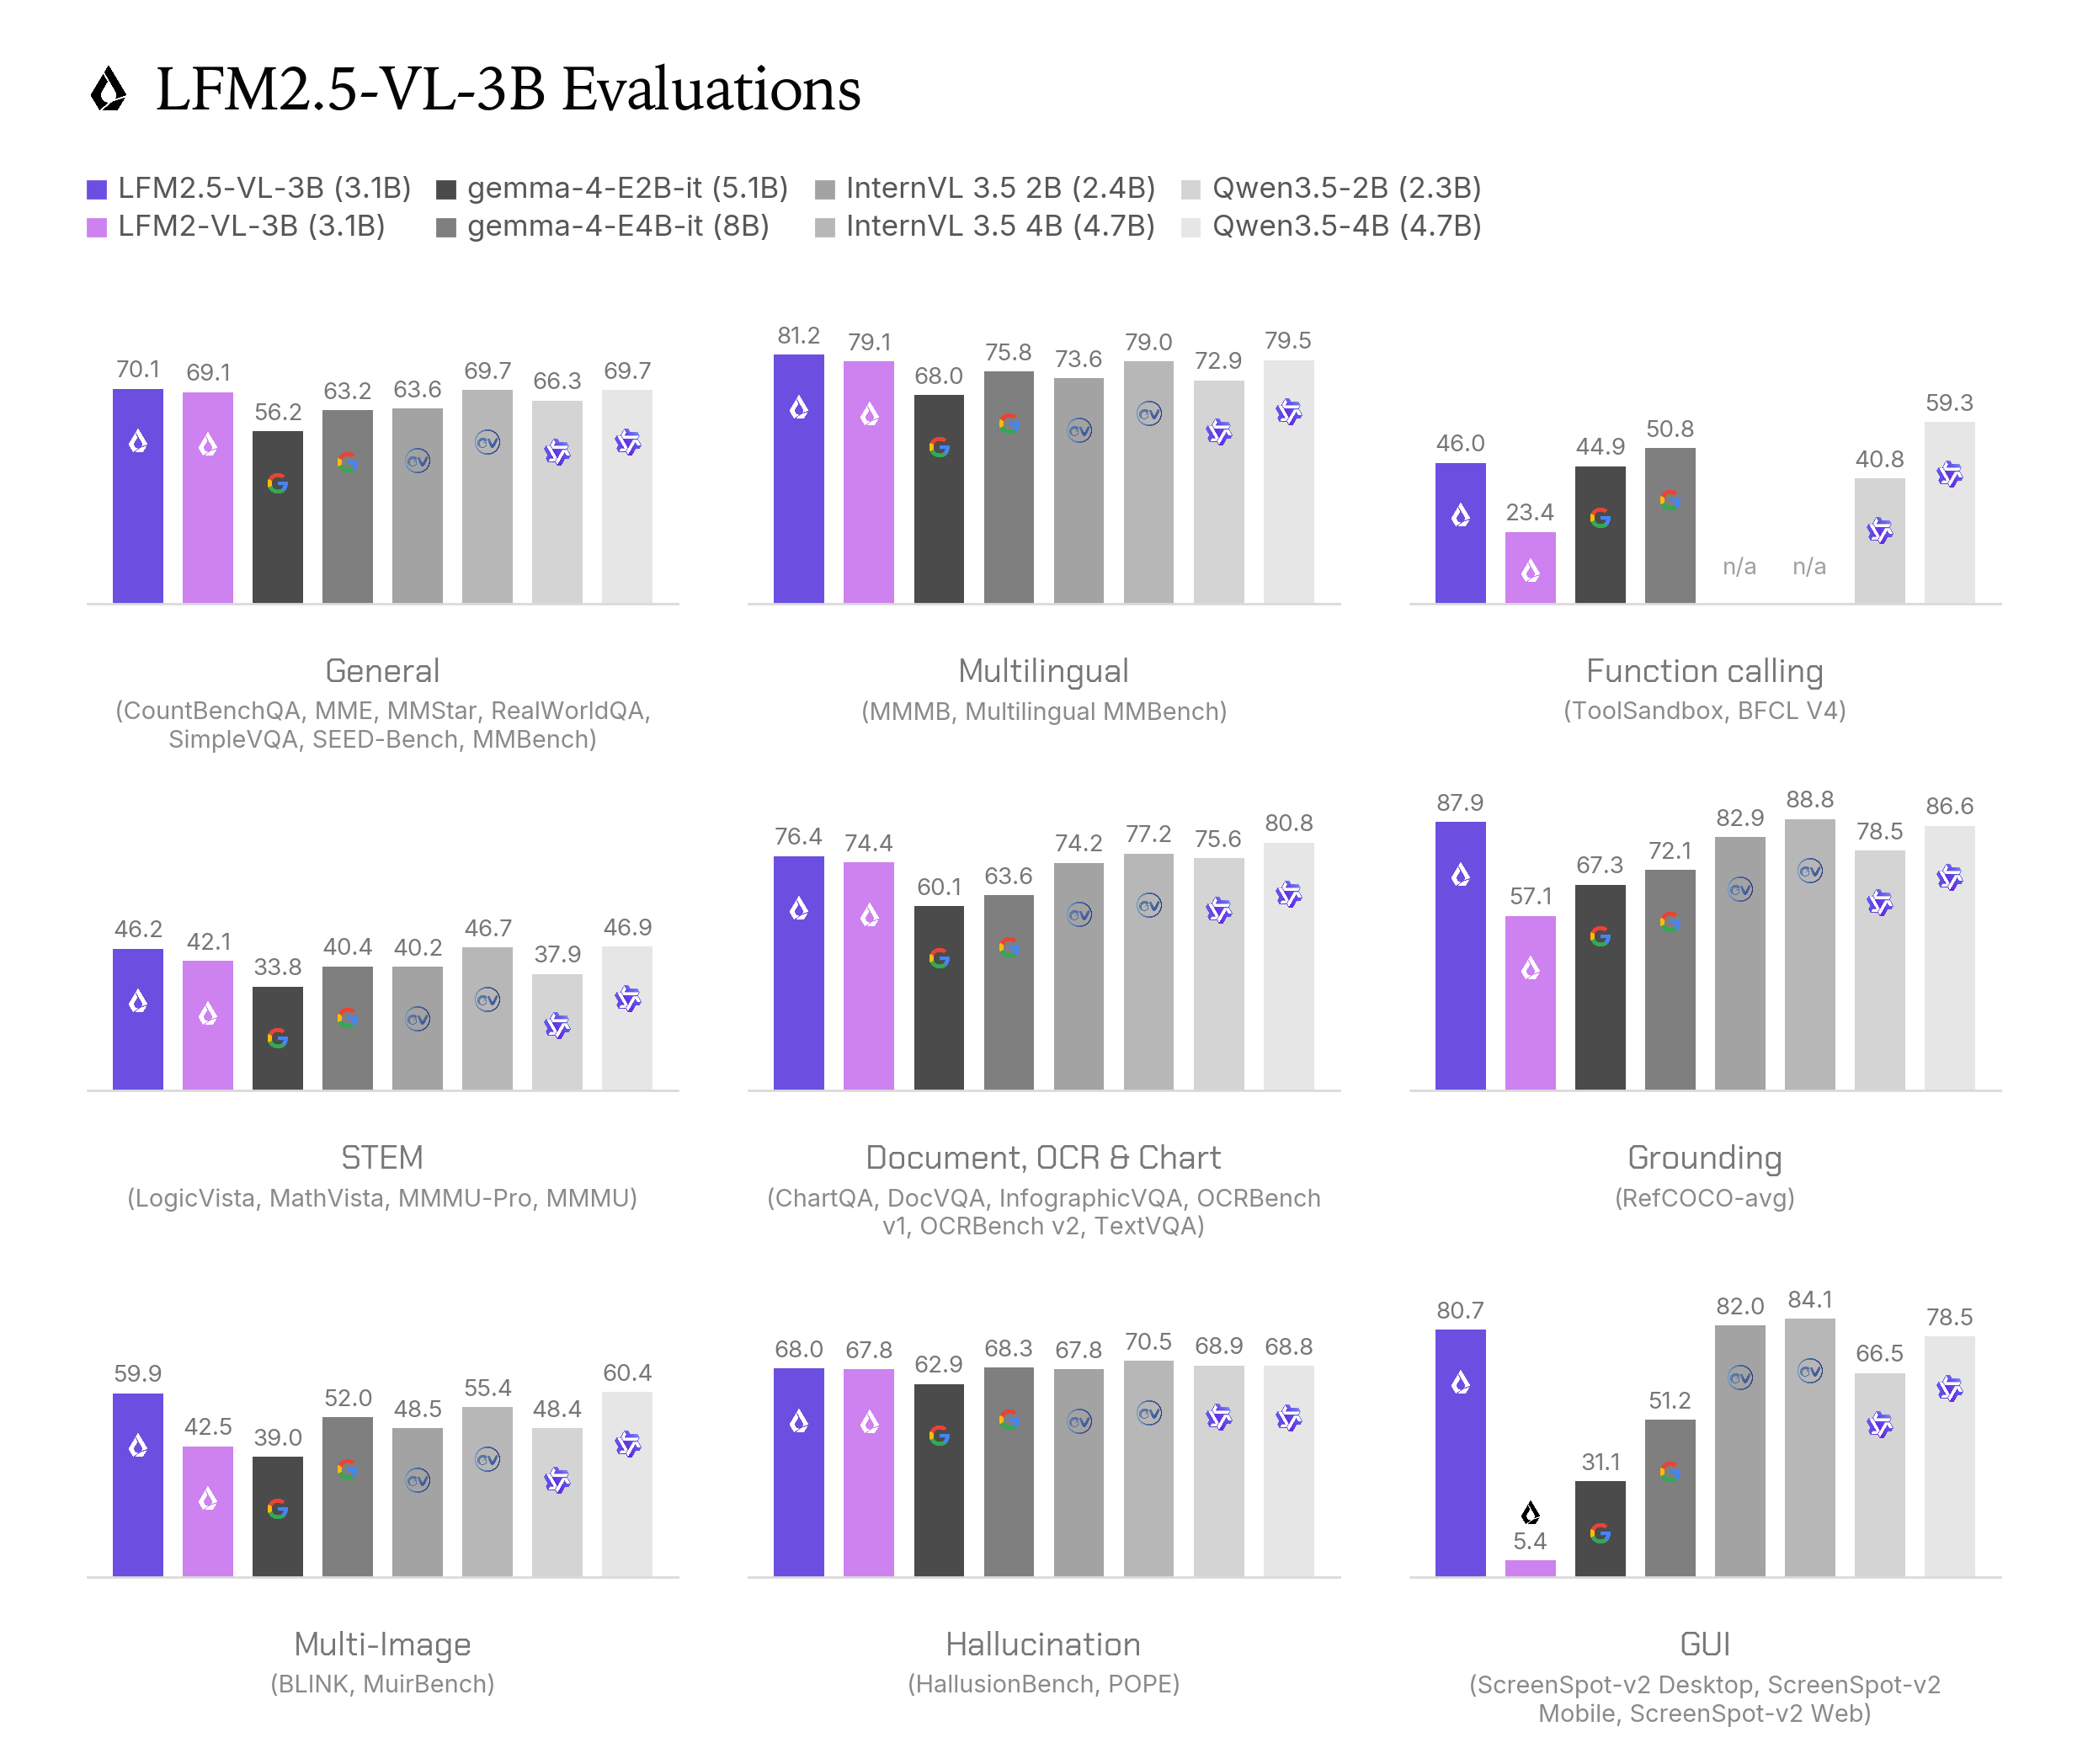
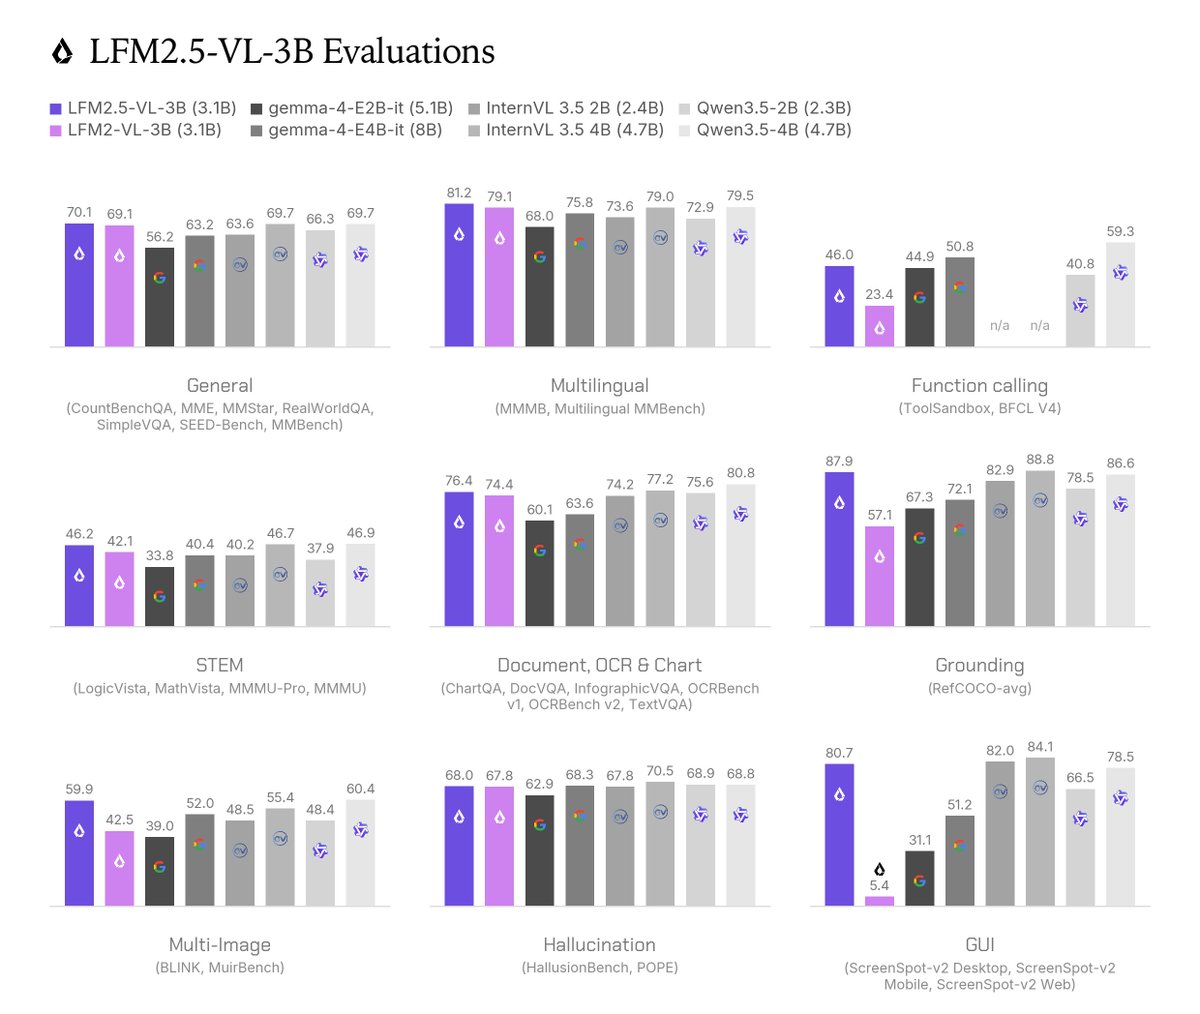
Liquid AI's LFM2.5-VL-3B shows a large reported improvement in locating targets on screens. On the web portion of ScreenSpot-v2, the company reports a score of 82.2 versus 2.5 for LFM2-VL-3B, on a scale normalized to 100. Both were evaluated in non-reasoning mode. This is useful evidence for the visual targeting component of a computer assistant: the model must identify the relevant screen element before software can act on it. The release's benchmark table measures that component, rather than completion of an entire browser task.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.