Ori Eval writes evals for the model calls already in your codebase
- Source
- x.com
- Date

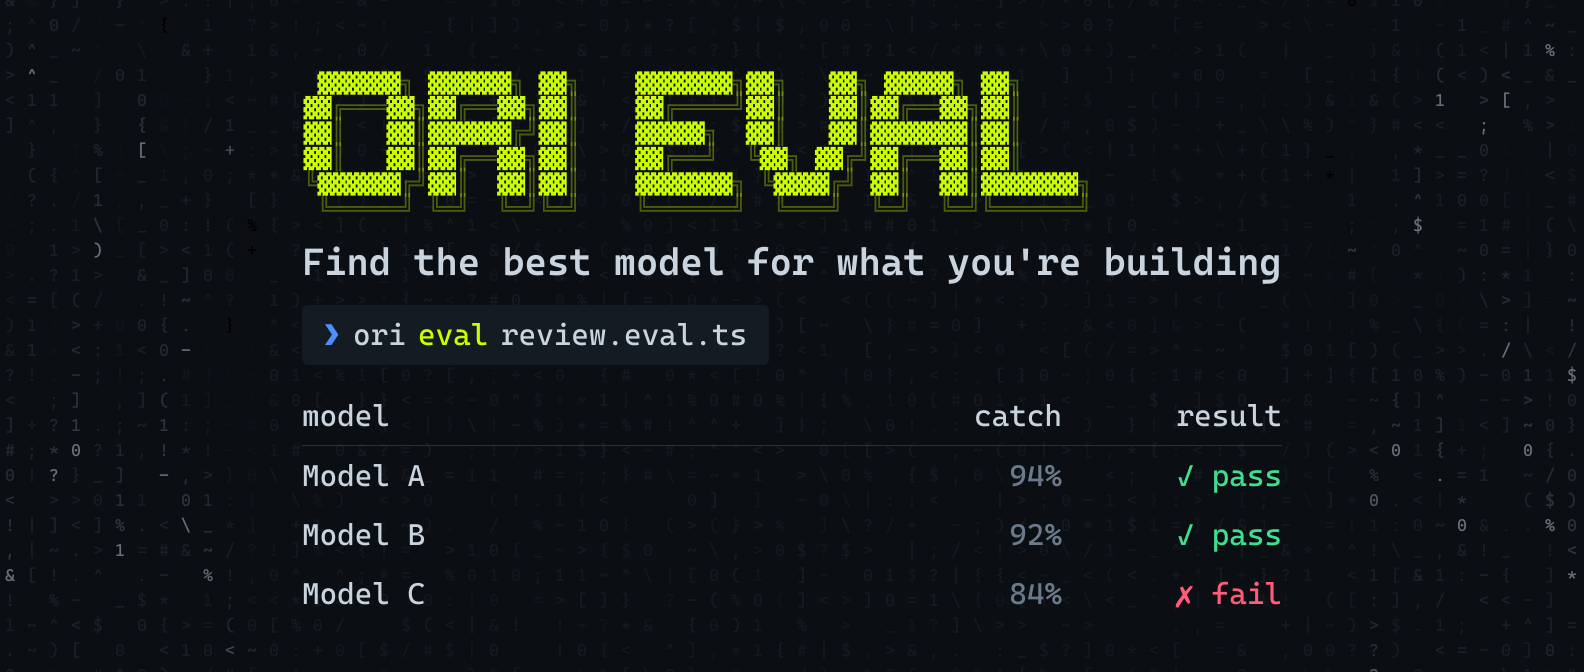
Introducing Ori Eval: the easiest way to write your first eval. There's no definitive best model, only the best model for each task. Ori Eval leverages OpenRouter's APIs for each task in your codebase, and then evaluates the results. curl -fsSL https://t.co/ABRt1wxtZ4

Directly in your favorite coding agent, Ori Eval explores your codebase, finds where you call models, asks what’s important (cost, perf, etc), writes the eval, and tests every model candidate. You get a ranked comparison, scored on your criteria.

Because Ori Eval is an agent, it pins the harness, the model, and the effort for the duration of a run. It also comes pre-tuned, so you don’t have to.
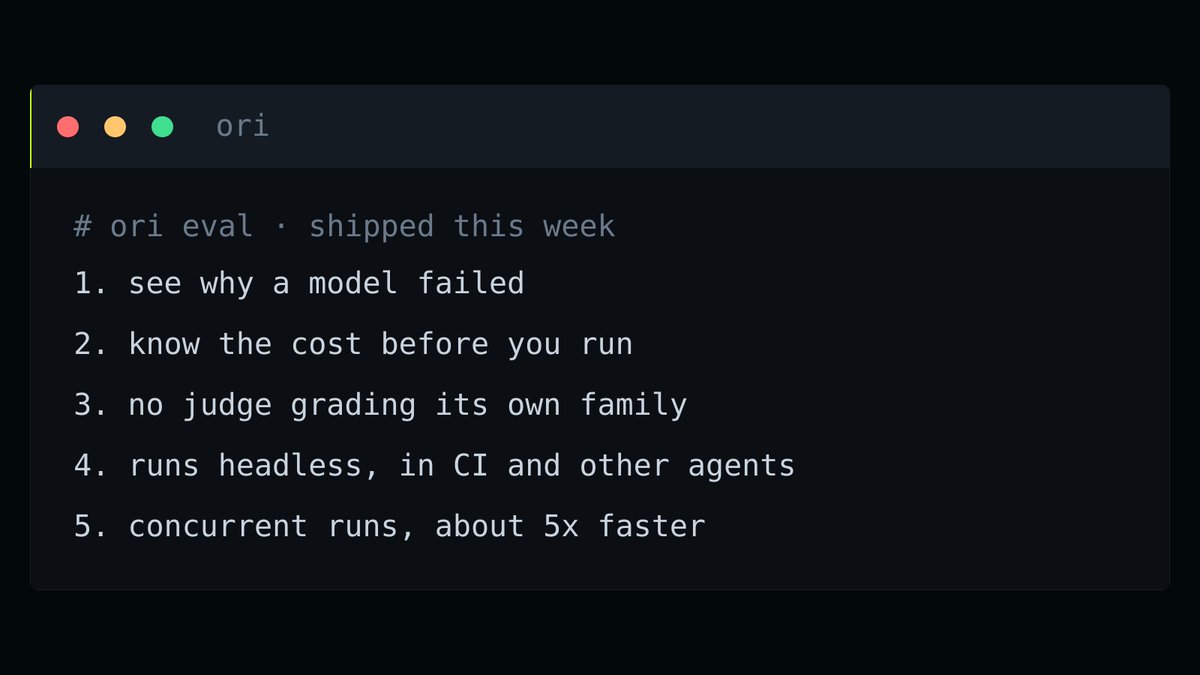
An eval checks three things: the tool it called, the tool it avoided, and the quality of the answer. run.tool(‘search’).toBeCalled() run.tool(‘delete_file’).toNotBeCalled() run.toComplete() Open-ended answers get graded by LLM-as-a-judge.
Context
Ori starts model selection from the work an application actually performs. OpenRouter says it finds model calls in a codebase, asks which outcomes matter, then writes tests and compares candidate models against those criteria. Tests can check whether an used a required tool or avoided a forbidden one; another grades open-ended answers against a rubric. The resulting comparison is specific to those tasks and rules. Because the tests remain as code, developers can rerun them after changing a model or fixing a bug, as the product explanation describes.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- LLM-as-judge — Using one model to score another's output against a rubric, so quality can be measured at a scale human grading cannot reach.




Checking sign-in…
Loading comments…