Sakana ships Fugu-Cyber, a gated orchestration endpoint for security work
- Source
- sakana.ai
- Author
- Sakana AI
- Date
Context
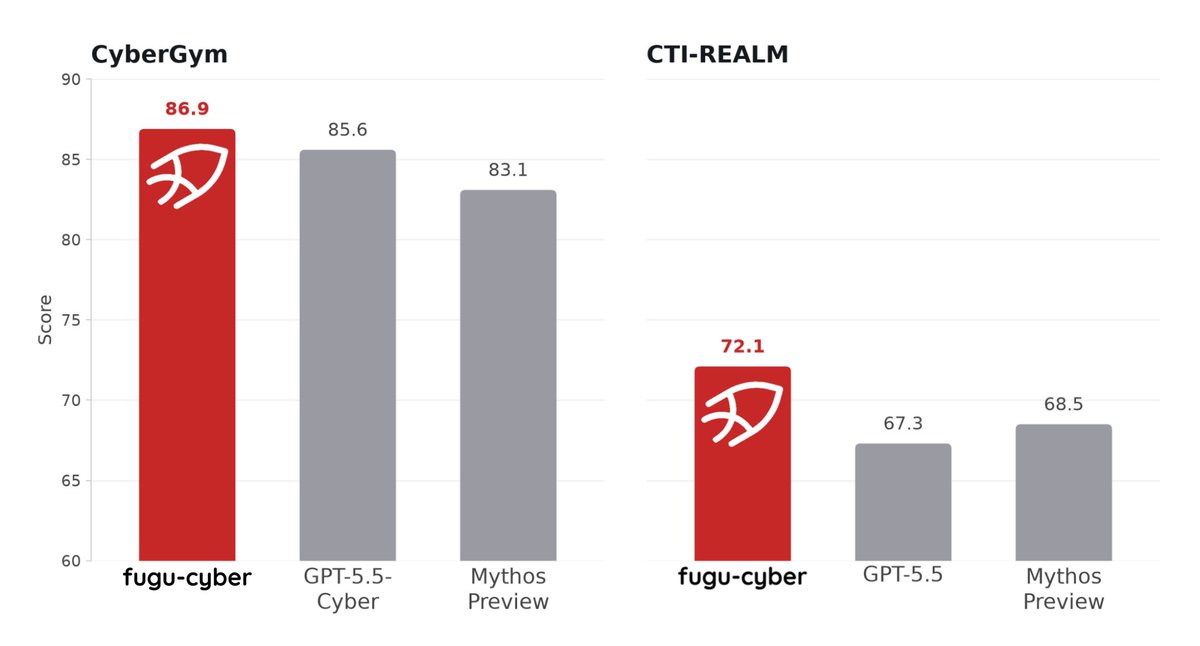
Fugu-Cyber is Sakana AI's security-focused version of Fugu, its service that sends one API request to a system coordinating several AI models. In the release post, announced on X on July 21, 2026, Sakana reports an 86.9% success rate on CyberGym, which tests whether an can analyze a large codebase and verify a real-world vulnerability, and 72.1% on CTI-REALM, which tests turning raw threat-intelligence reports into working detection rules. Sakana calls these results comparable to cyber-focused frontier models such as OpenAI's GPT-5.5-Cyber and Anthropic's Mythos Preview. The release text gives no scores for those models and describes no independent run, so the comparison rests on Sakana's own reporting.
Most of the release argues that a score does not secure a company. Citing a Nikkei report and its own work with large Japanese enterprises, Sakana says organizations, including major financial institutions, struggle to put frontier cyber models to use without in-house security specialists and deep integration with their proprietary source code. It says a model deployed on its own will produce false positives, so any vulnerability it surfaces should be checked by specialized sub-agents and human reviewers to confirm it would actually trigger in the real environment before a patch is proposed. Sakana says its Applied Enterprise team is building those harnesses and workflows with major Japanese institutions; the release names none of them and reports no deployment results.
Access is gated. Fugu-Cyber falls under an updated acceptable use policy that prohibits offensive misuse, it is offered on the pay-as-you-go Plan, and applicants must describe their intended use and provide verified contact information before Sakana's team approves each request by hand. Sakana's setup guide likewise says a Claude Code model tier should be pointed at fugu-cyber only if the user's key has been approved for it.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- multi-agent — Using several AI agents on one problem — splitting work in parallel, checking each other, or filling different roles like planner and reviewer.
Checking sign-in…
Loading comments…