Upstage launches Solar Mini 4, a 3B-active MoE for agent workloads
- Source
- x.com
- Date

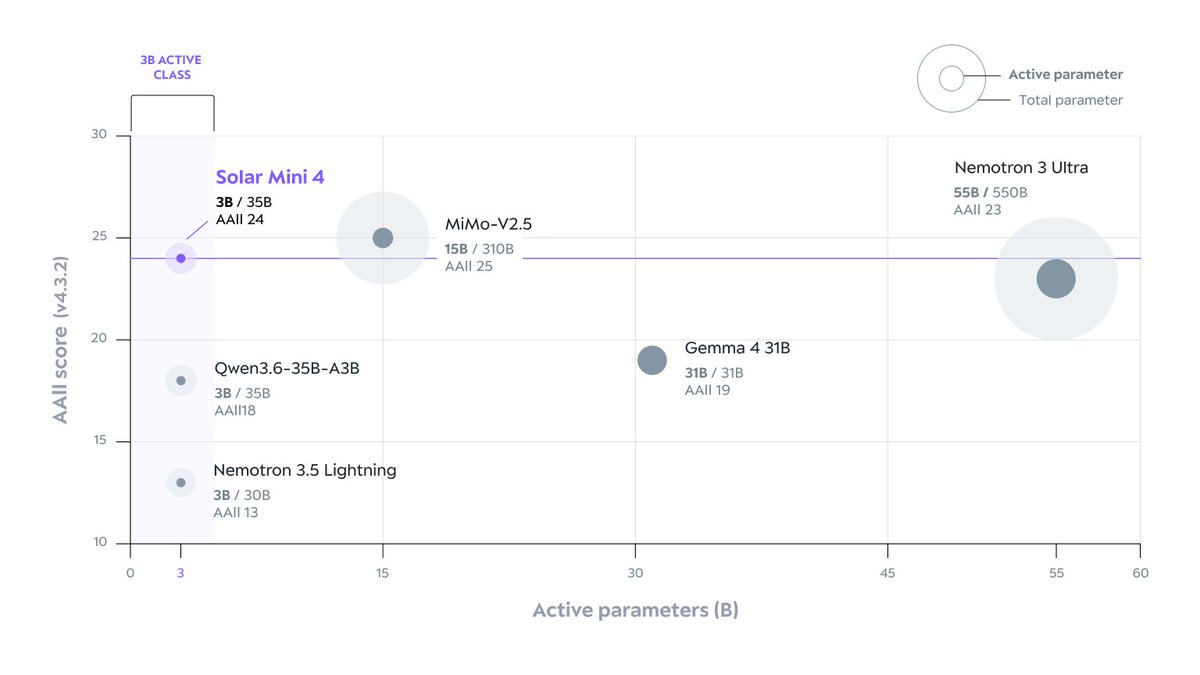
Solar Mini 4: Built for High-Volume Agent Workloads Top overall performance among active-3B models, with lower costs for repetitive agent work. Solar Mini 4 is a 35B MoE model pretrained from the ground up by Upstage. It activates just 3B parameters per token, drawing on the full model's capacity while using far less compute. That makes it fast and cost-efficient for agent workloads built on repeated retrieval, structuring, and tool calls. Solar Mini 4 is available now on Upstage Console, Solar Chat, and OpenRouter, with on-premises deployment also supported. To celebrate the launch, API pricing on Upstage Console and OpenRouter is 70% off through October 10 (UTC). Make repetitive agent work more efficient. Try Solar Mini 4 today.

Context
Solar Mini 4's small active parameter count does not by itself establish cheap or fast completed tasks. Upstage says its model uses 3 billion of its 35 billion parameters for each , and positions this selective computation as fast and cost-efficient for repetitive work in its launch post.
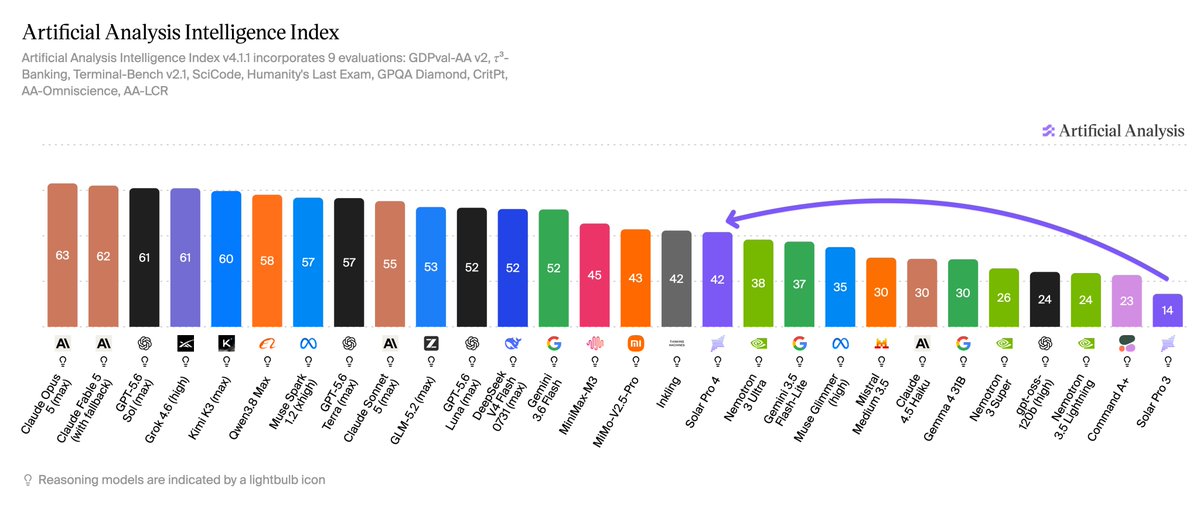
The earlier evaluation from Artificial Analysis shows why generation speed needs a second measurement. It reported output at 208 tokens per second, but 88,000 output tokens and an average of 7.1 minutes per Intelligence Index task, and said the model costs about five times as much per task as GPT-6 Luna (max) despite similar per-token prices. Rapid production of text can still produce a lengthy, costly task when the model generates a great deal of it. Completed-task time and cost are therefore the relevant checks on the efficiency claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
Checking sign-in…
Loading comments…