Solar Mini 4: cheap tokens, expensive tasks, weak agentic coding
- Source
- x.com
- Date

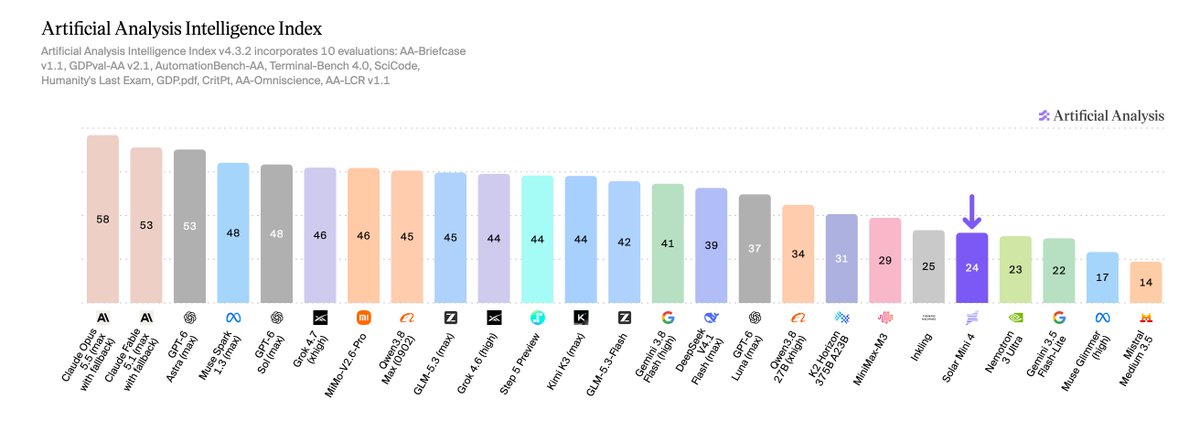
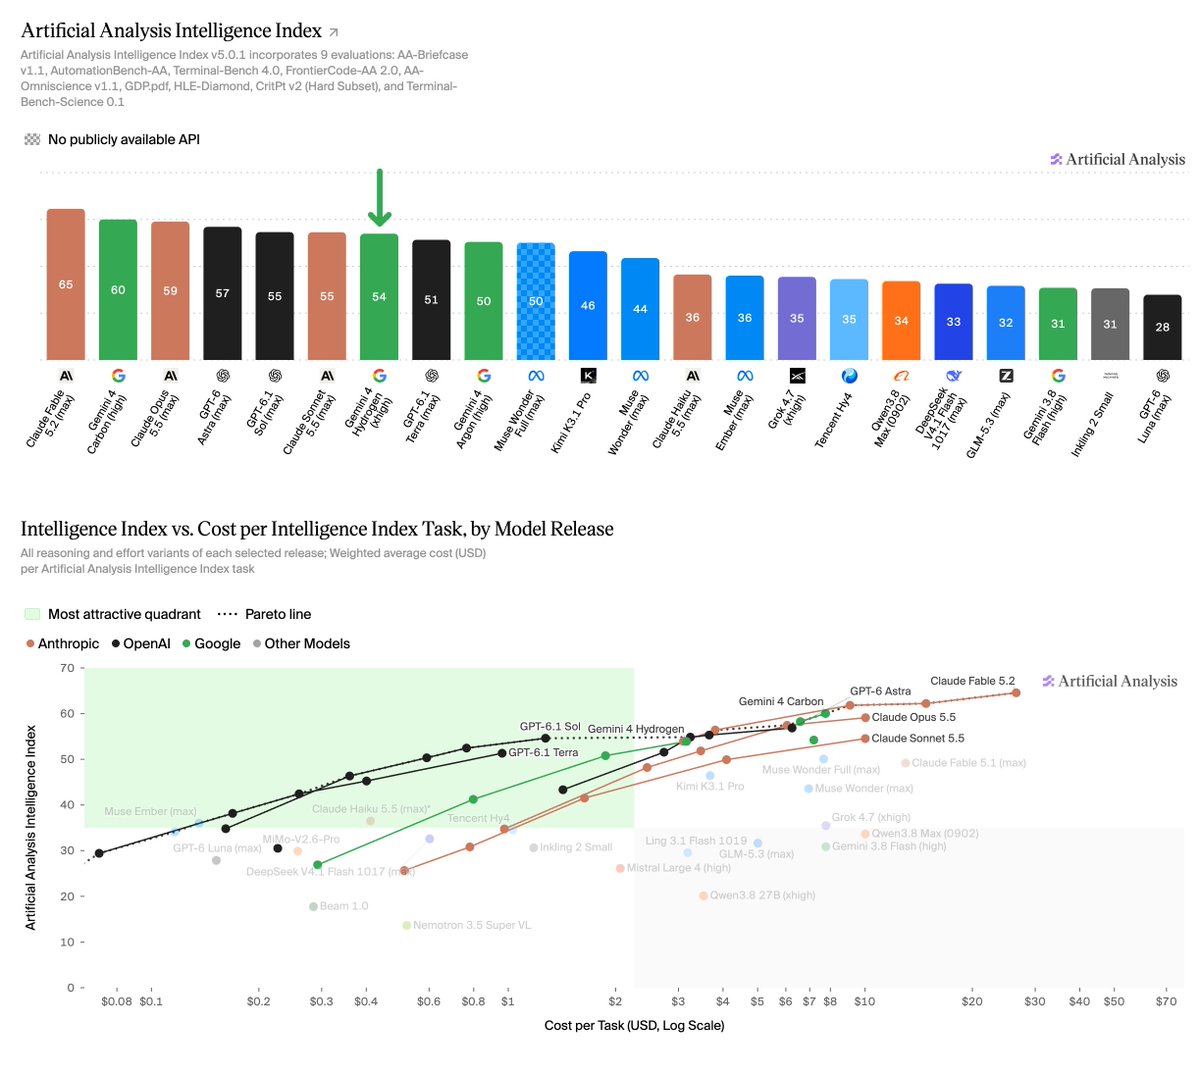
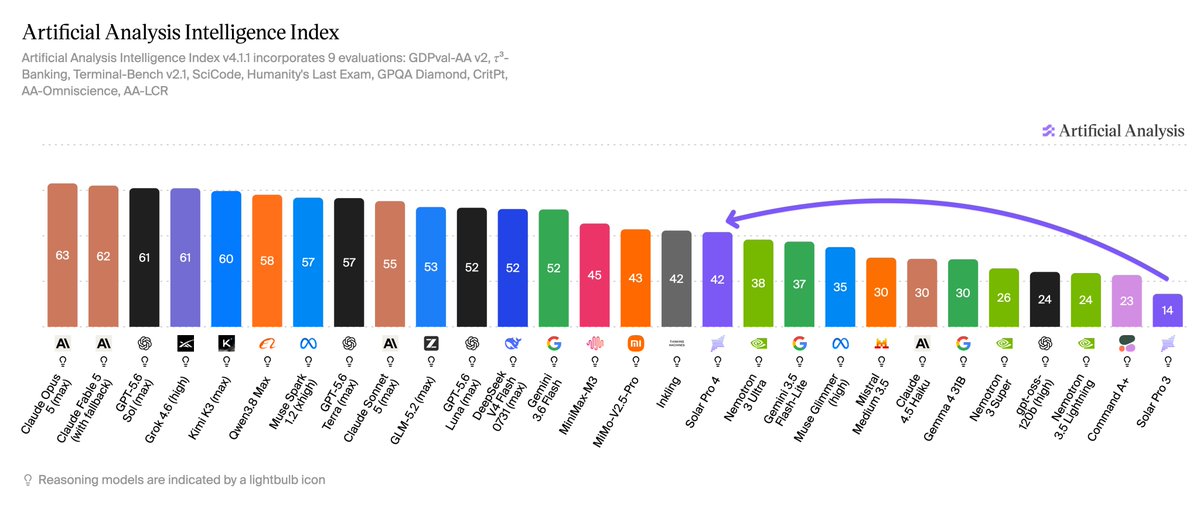
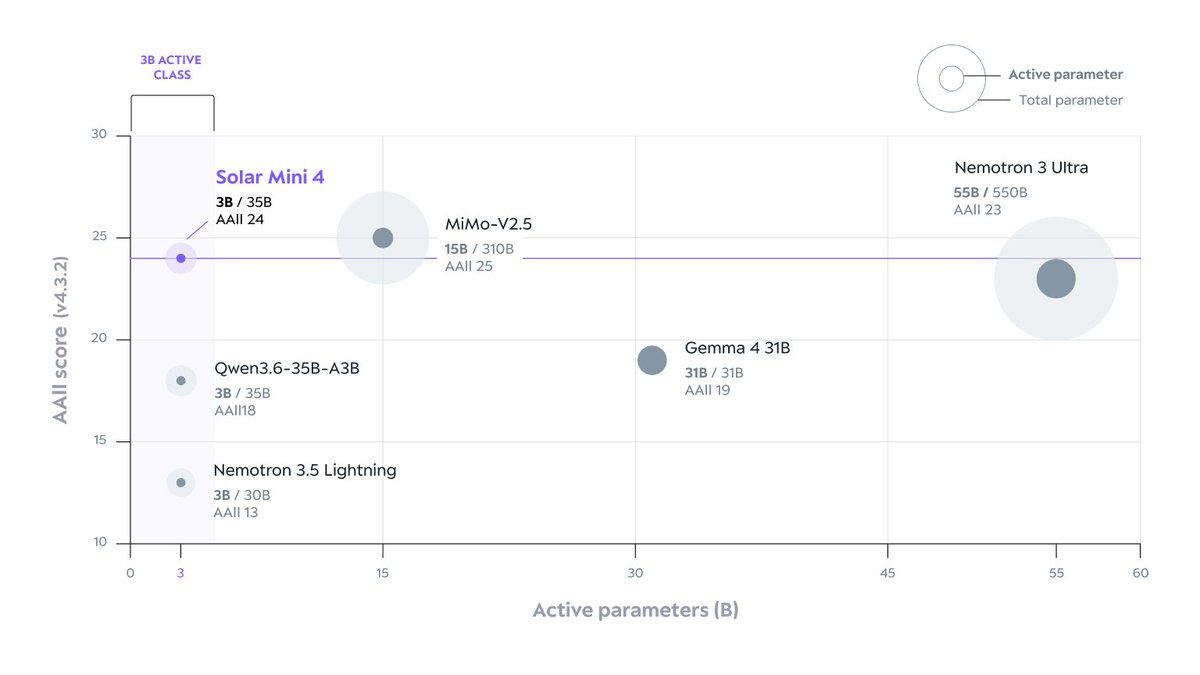
Korean AI Lab 🇰🇷 Upstage has released Solar Mini 4 which scores 24 on the Artificial Analysis Intelligence Index, but costs ~5x as much per task as GPT-6 Luna (max) despite similar per-token prices Upstage has released Solar Mini 4, a new proprietary reasoning model. Upstage reports 35B total and 3B active parameters, setting a new Pareto optimal point on Intelligence Index vs. Active Parameters for models under 3B active parameters. It also scores 16 points higher than Upstage's previous-generation flagship, Solar Pro 3 (8), and cuts per-token pricing by a third to $0.10/$0.40 per 1M input/output tokens. Key results: ➤ Strong for its reported active parameter size: Solar Mini 4 scores 6 points higher than Qwen3.6 35B A3B (Reasoning), which has the same 3B active parameters, and 1 point higher than Nemotron 3 Ultra, which has 55B active. As a proprietary model, its size cannot be independently verified. ➤ Long context reasoning is a relative strength: It scores 83% on AA-LCR v1.1, matching MiniMax-M3 and GPT-6 Luna (max), and ahead of Gemini 3.8 Flash (high) and GPT-6 Astra (max) at 81%. It also scores 48% on SciCode, ahead of MiniMax-M3 and Inkling (xhigh) at 47%. ➤ Fast…
Context
Solar Mini 4 is cheap per but not cheap per job, because it generates a lot of text to finish each task. Artificial Analysis, which benchmarks AI models independently, reports that the new from Korean lab Upstage costs about five times as much per task as GPT-6 Luna (max), even though the two have similar per-token prices. Solar Mini 4 is priced at $0.10 per million input tokens and $0.40 per million output tokens, a third less than Upstage charged before. A token is a small chunk of text, and API bills are counted in them, so a low price per token still adds up when a model uses many tokens per answer.
The same arithmetic explains its speed. The model writes 208 tokens per second, faster than GPT-6 Luna (max) at 152. But it averaged 88,000 output tokens per task on the Artificial Analysis Intelligence Index, so a task took 7.1 minutes on average. Its overall index score of 24 is 16 points above Upstage's previous flagship, Solar Pro 3, and the evaluator calls it strong for its size. Upstage says only 3 billion of its 35 billion parameters are active for each token, and Artificial Analysis notes it cannot independently verify the size of a proprietary model. The results are uneven: 83% on a long- reasoning test, but 1% on Terminal-Bench 4.0, which the evaluator counts as agentic coding.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- reasoning model — A model trained to think — generating extended internal reasoning before answering — trading time and tokens for accuracy on hard problems.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
Checking sign-in…
Loading comments…