Korean AI lab Upstage has released Solar Pro 4, scoring 42 on the Artificial Ana
- Source
- x.com
- Date

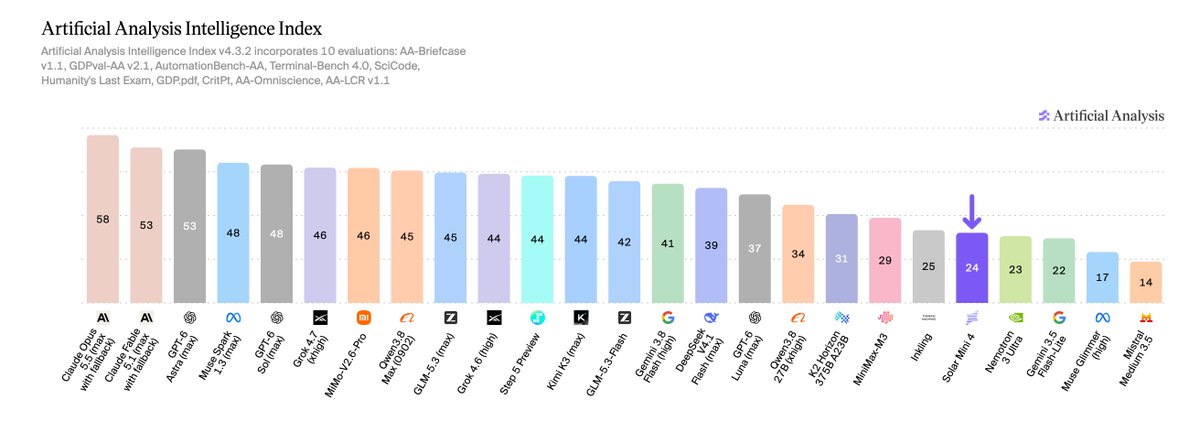
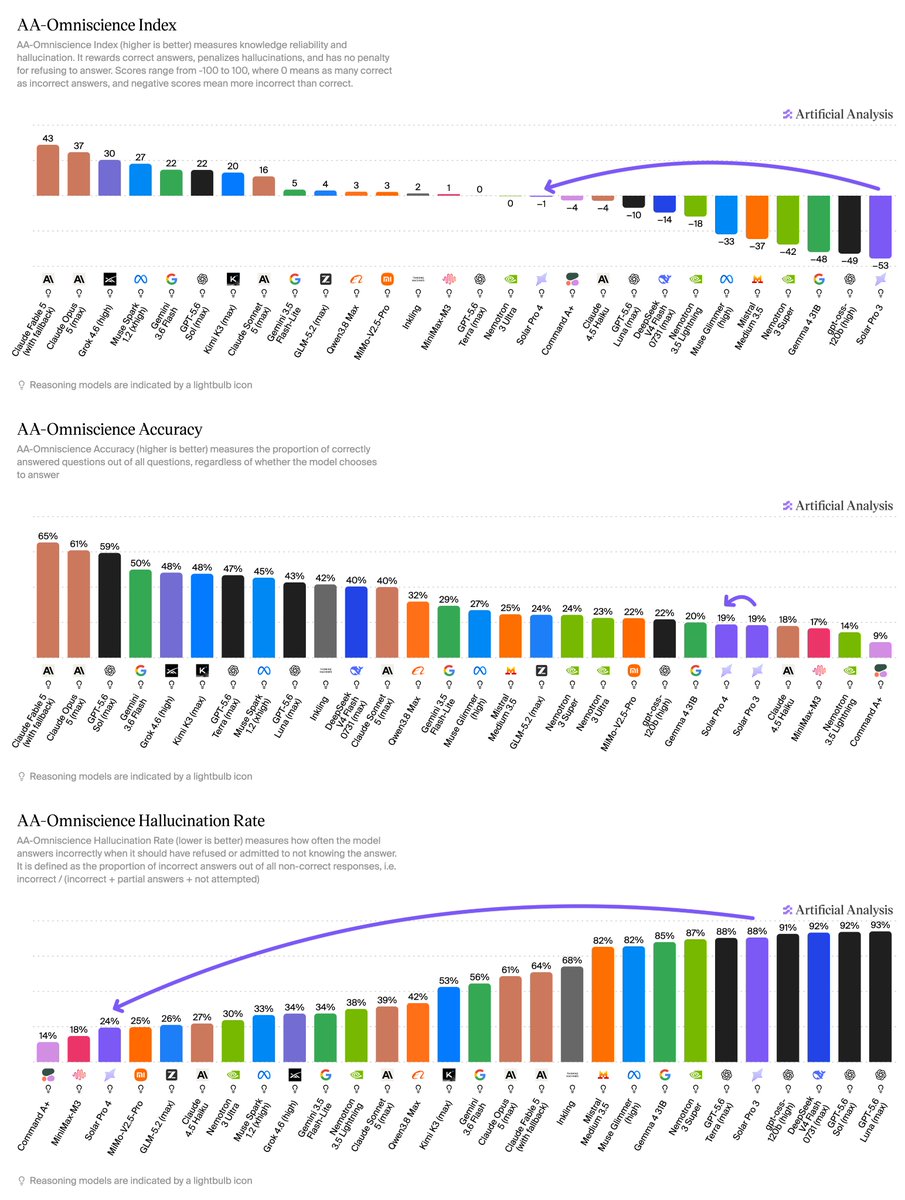
Korean AI lab Upstage has released Solar Pro 4, scoring 42 on the Artificial Analysis Intelligence Index, a significant increase from Solar Pro 3’s 14 Solar Pro 4 is @upstageai's new proprietary flagship reasoning model, replacing Solar Pro 3 from April 2026. At 42 on the Intelligence Index it sits alongside Inkling (xhigh, 42) and just behind MiMo-V2.5-Pro (43), and shows a 27-point increase over Solar Pro 3. Pricing increases to $0.30/$1.20/$0.06 per 1M input/output/cache hit tokens from Solar Pro 3's $0.15/$0.60/$0.02 via Upstage’s first-party API. Key results: ➤ Solar Pro 4’s largest improvements on Solar Pro 3 are on agentic and long context work. Terminal-Bench v2.1 improves from 12% to 57%, AA-LCR from 31% to 71%, and τ³-Banking from 9% to 23%. GDPval-AA v2 shows strong progress on real-world agentic tasks, where Solar Pro 3 scored an Elo of 498, well below the human baseline of 1000, Solar Pro 4 scores 1276. ➤ AA-Omniscience improvement from -53 to -1 was driven by abstaining on more questions. Solar Pro 4 attempts only 41% of questions against 92% for Solar Pro 3, and its hallucination rate is 24%, higher than Command A+ (14%) and MiniMax-M3 (18%), and a vast…

Context
Upstage's Solar Pro 4 improved most on and long- work, and its knowledge score rose because it now declines more questions, according to Artificial Analysis's evaluation. The Korean lab's new proprietary replaces Solar Pro 3 from April 2026 and scores 42 on the Artificial Analysis Intelligence Index, up from Solar Pro 3's 14. The evaluator says the largest gains are on agentic and long-context tests: Terminal-Bench v2.1 rose from 12% to 57%, the long-context test AA-LCR from 31% to 71%, and τ³-Banking from 9% to 23%. On GDPval-AA v2, which rates real-world work tasks against a human baseline of 1000 Elo, Solar Pro 3 scored 498 and Solar Pro 4 scores 1276.
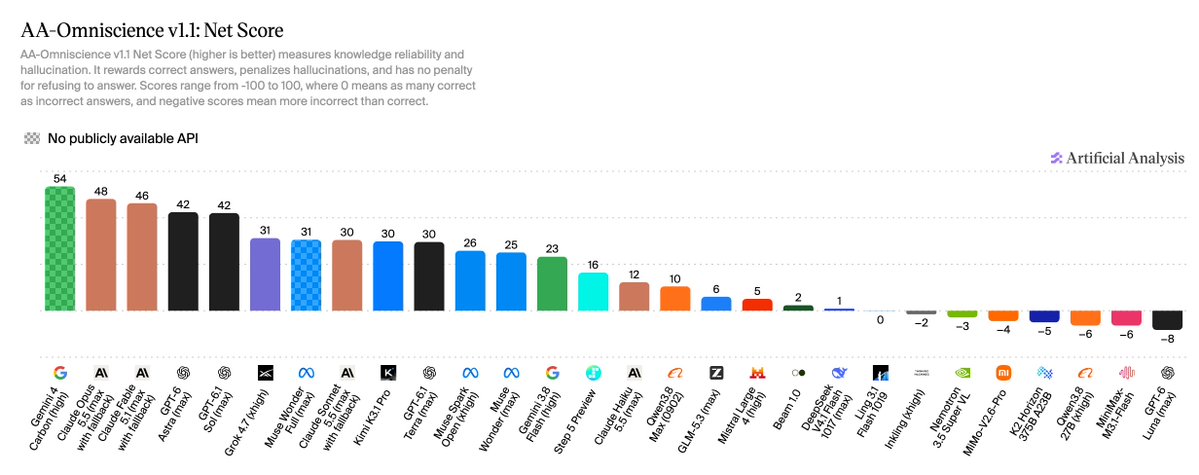
The knowledge result moved for a different reason. Solar Pro 4's score on AA-Omniscience, a knowledge test whose score can fall below zero, went from -53 to -1, and Artificial Analysis attributes that to abstaining: the model attempts 41% of questions, against 92% for Solar Pro 3. Its rate fell from 88% to 24%, still higher than Command A+ (14%) and MiniMax-M3 (18%), while accuracy stayed at 19%. The model makes far fewer wrong guesses but answers no more questions correctly. Upstage's own launch post presents that behavior as intended, saying the model is built to "stop and say so when the evidence runs out."
The gains cost more time and money. Through Upstage's own API, prices double to $0.30 per million input tokens and $1.20 per million output tokens, from $0.15 and $0.60, and cache hits rise to $0.06 from $0.02. An average Intelligence Index task takes 9.5 minutes against 6.9 for Solar Pro 3, even though Solar Pro 4 writes about 17% fewer output tokens per task (43,000 against 52,000). At that price it trails models that score higher on the same index: Artificial Analysis notes that MiniMax's MiniMax-M3 has the same per-token price and scores 45, and DeepSeek's V4 Flash 0731 scores 52 at $0.14 and $0.28.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- reasoning model — A model trained to think — generating extended internal reasoning before answering — trading time and tokens for accuracy on hard problems.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
Checking sign-in…
Loading comments…