Prompt cache TTL is the hidden line item in long coding-agent sessions
- Source
- x.com
- Date

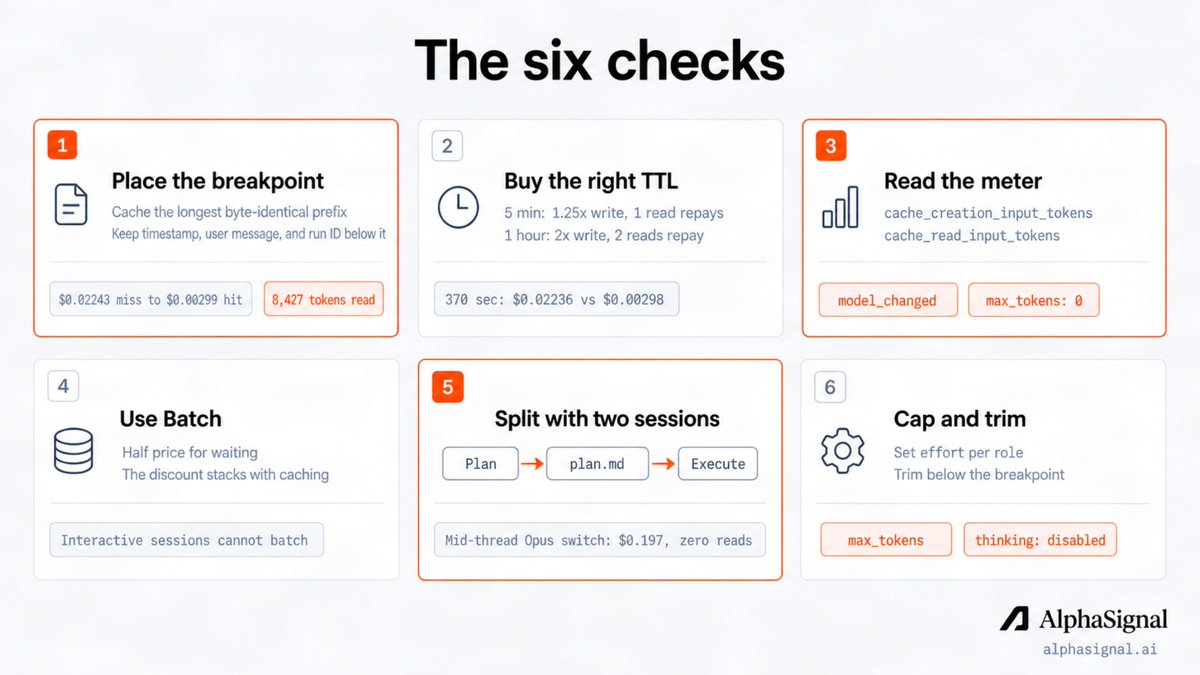
Your 5-minute cache is already dead when you sit down. API models don't keep the thread. Every turn resends the whole history. A one-token tool result still pays that whole history. On Opus 5, 1 million uncached tokens are $5. A hit is $0.50. Cache-hit discounts are provider-specific. > Anthropic 0.1x on a hit > OpenRouter blend near 1/5 > Grok 4.6 cache read 0.25x > DeepSeek Flash off-peak 0.03x Earlier, we ran 4.5 through 12 turns at 30,000 tokens. Turns 2 and 10 were full-price re-reads. Compact before you walk away so the miss stays small. Buy the 1-hour write at 2x, and a return can hit. Claude Code and Codex often compact around 200,000 to 300,000 tokens. Filling 1 million on purpose buys the expensive part. So, What do you pin so the cheap copy stays cheap? Where does the project live so compact doesn't wipe it? Why is dollars per million the wrong scoreboard? Full Breakdown ↓↓
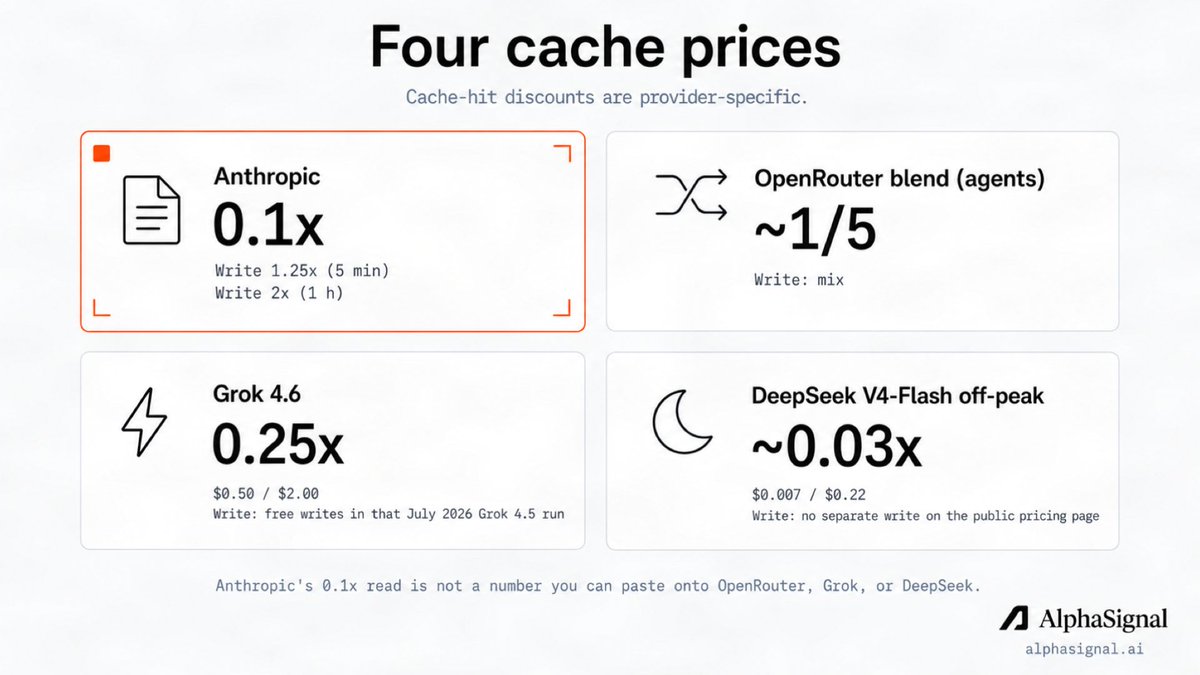

Pin the model and the provider for the session. That is what keeps the cheap copy cheap to re-read. https://t.co/IiG2EqB5au
Context
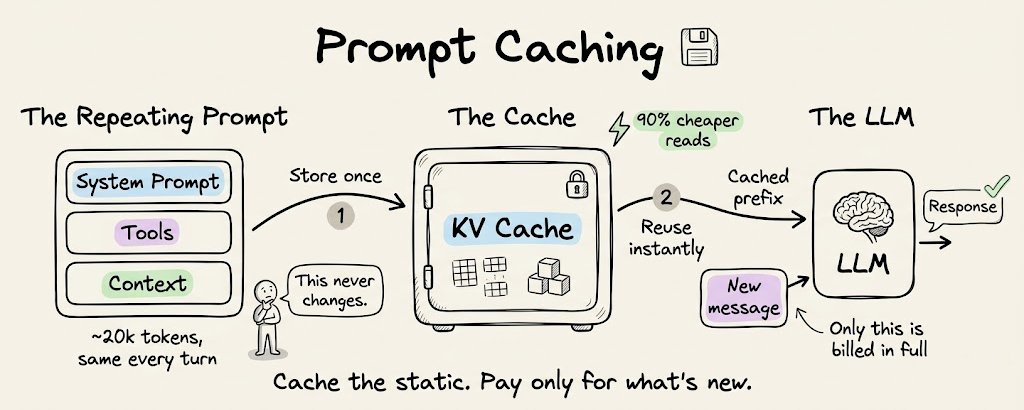
A pause between requests can change the cost of reusing an AI conversation. lets an API reuse an already processed beginning of a prompt, including stable instructions or earlier messages. Anthropic documents a default five-minute cache lifetime that is refreshed each time the cached content is used, plus a one-hour option at additional cost. Once the lifetime passes, a later request will not find the entry and must process that content again. That explains why the spacing of requests matters alongside the amount of text sent. Reuse also requires an exact match for the cached portion.
- prompt caching — Reusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- context compaction — Summarizing an agent's earlier conversation to free room in the context window so a long session can keep going.
Checking sign-in…
Loading comments…