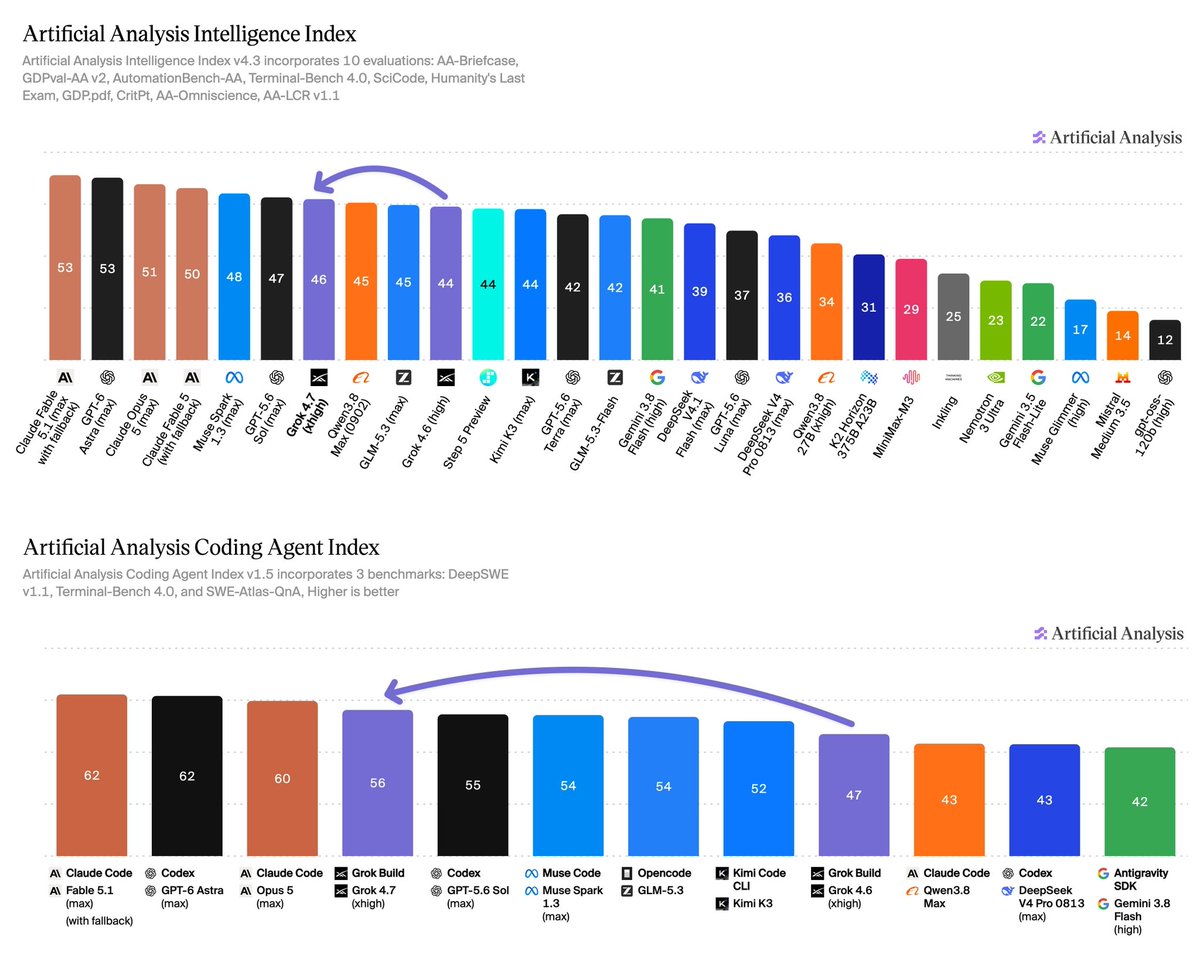
Grok 4.7 just landed on @mercor's APEX leaderboards:
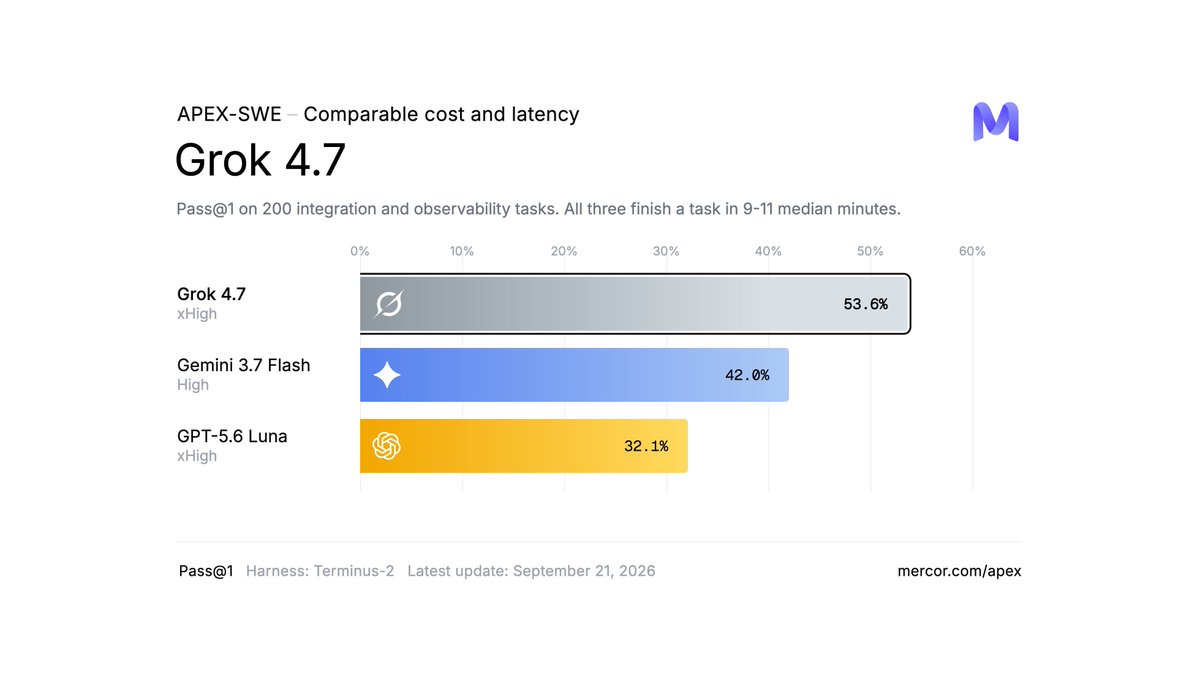
> #5 on APEX-SWE at 53.6%
> #13 on APEX-Agents at 54.6%
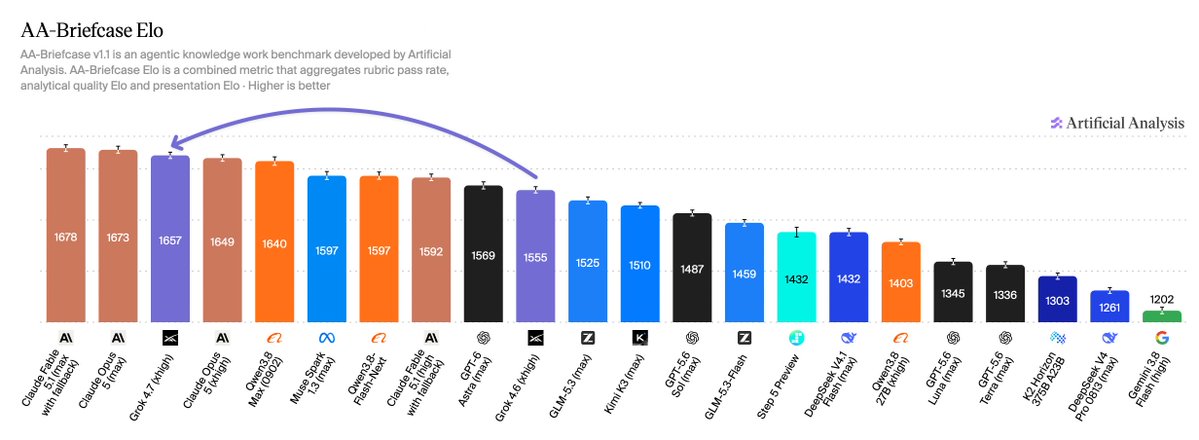
The notable part is the bracket, which sits in the same cost and latency tier as Gemini 3.7 Flash and GPT-5.6 Luna while leading on SWE.
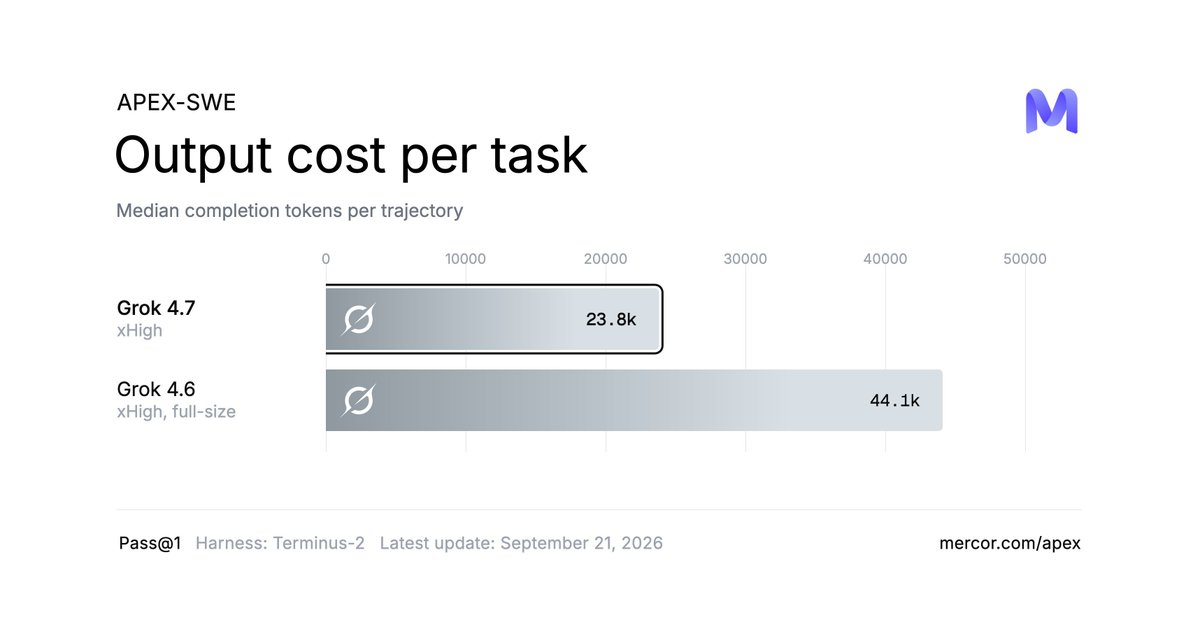
APEX updates with every major model release, so you can see how the newest models stack up, compare token costs, and explore results from third-party benchmarks like BrowseComp and Terminal-Bench.
See the full leaderboard at https://t.co/7sAoPQZDh7
*partnerpost
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Why it matters
Places Grok 4.7 concretely against same-cost-tier competitors on independent SWE and AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → benchmarks, useful for model selection at a given price point.