How does it compare to Qwen 3.6 35B A3B, one of the most popular models on DGX…
- Source
- x.com
- Date

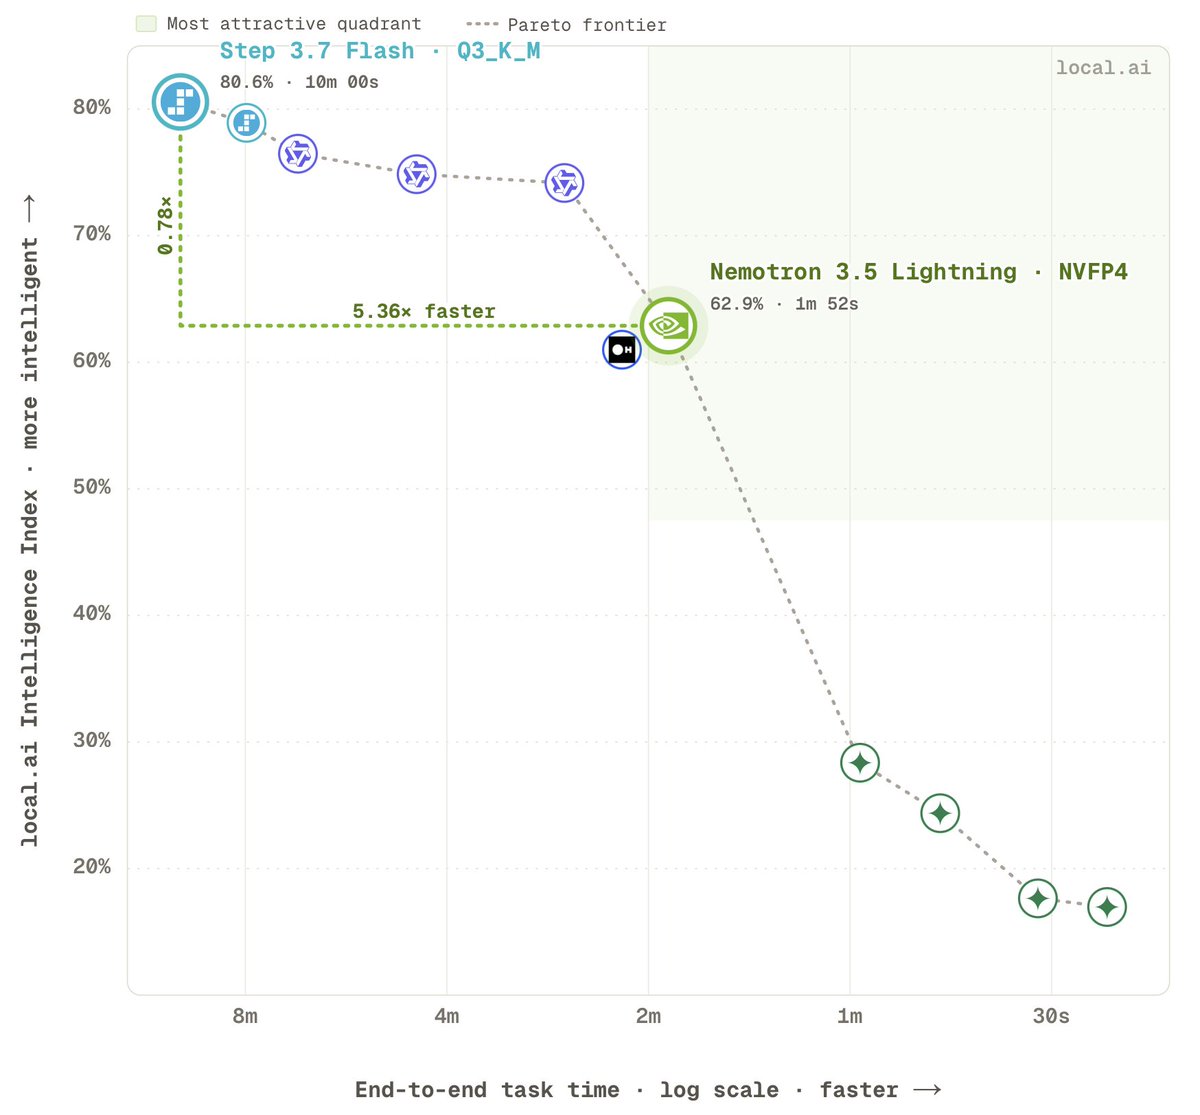
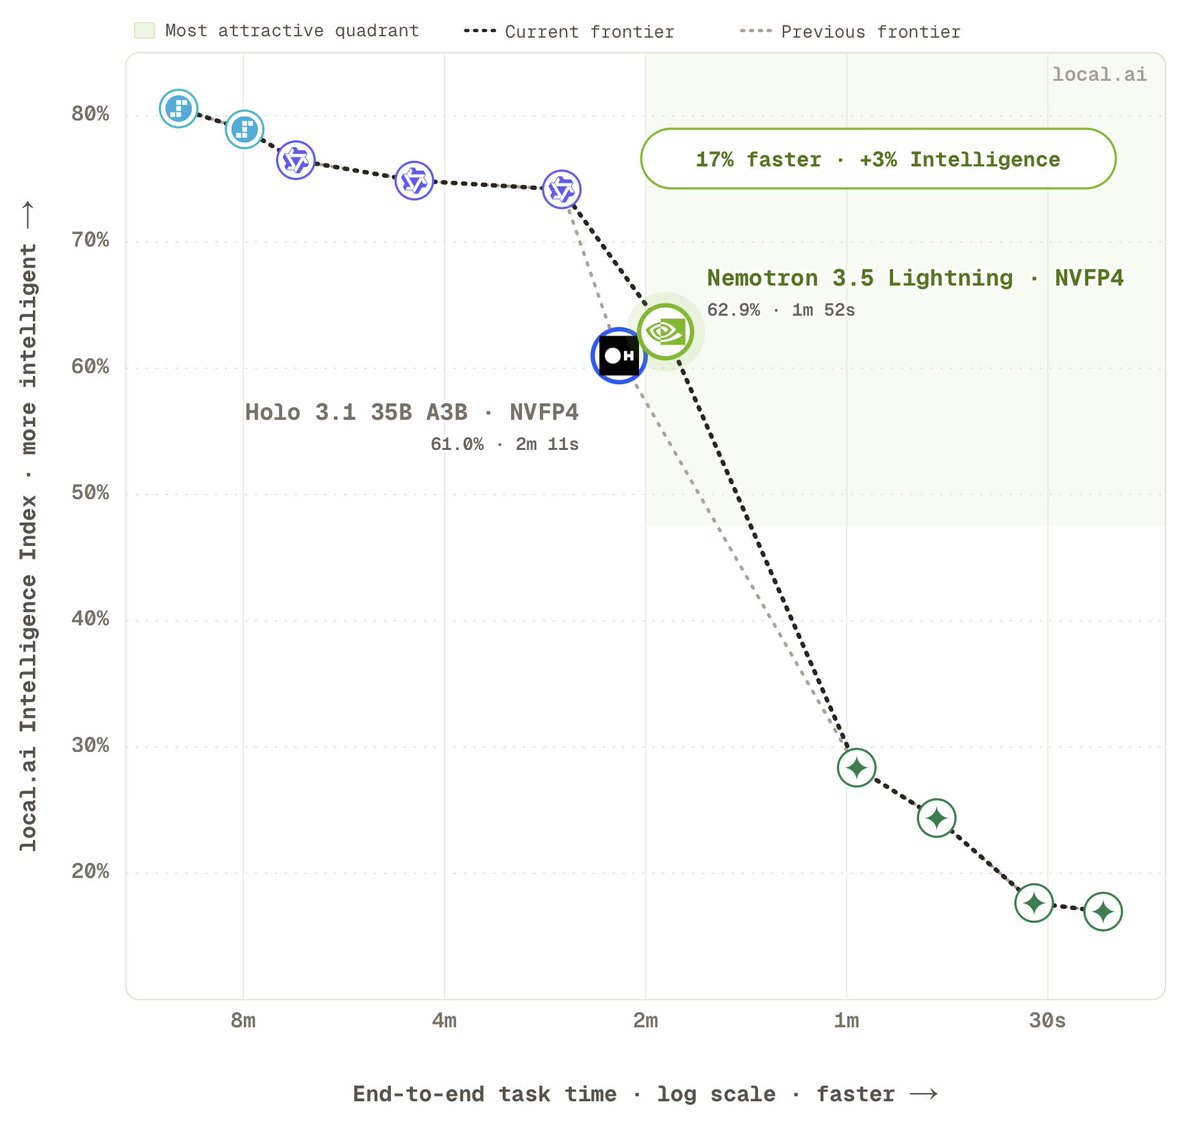
How does it compare to Qwen 3.6 35B A3B, one of the most popular models on DGX Spark today? Qwen with MTP actually runs at faster decode TPS than Lightning for most context lengths and tasks. However, Qwen is much more verbose: it uses 45% more output tokens and 11% more steps to complete tasks. This histogram shows the output token distribution over all GDPVal tasks. Overall tasks take 42% longer with Qwen than Lightning.

Context
Generating text faster did not make Qwen 3.6 35B A3B finish tasks sooner in Alex Cheema's DGX Spark comparison. Although Qwen generated more per second in most tested settings, it produced 45% more output tokens and took 11% more steps than Nemotron 3.5 Lightning. Overall task time was 42% longer. Comparison and output histogram.
The result shows why generation speed alone can misrepresent an 's responsiveness: the amount of text and number of steps needed to finish also affect the wait.
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference
Checking sign-in…
Loading comments…