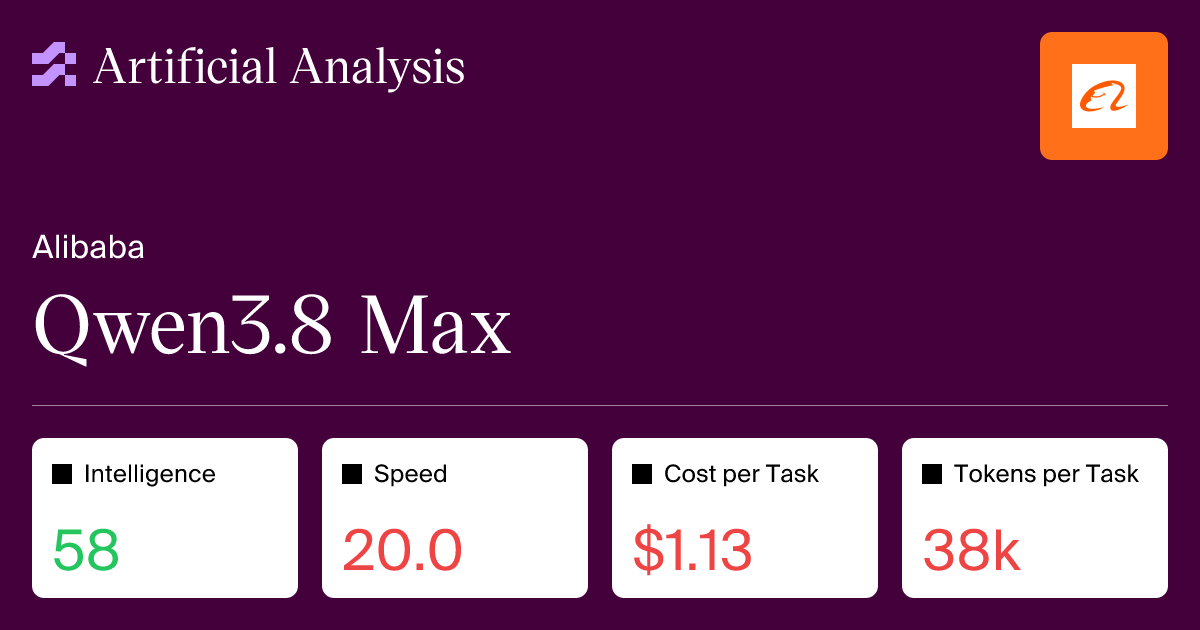
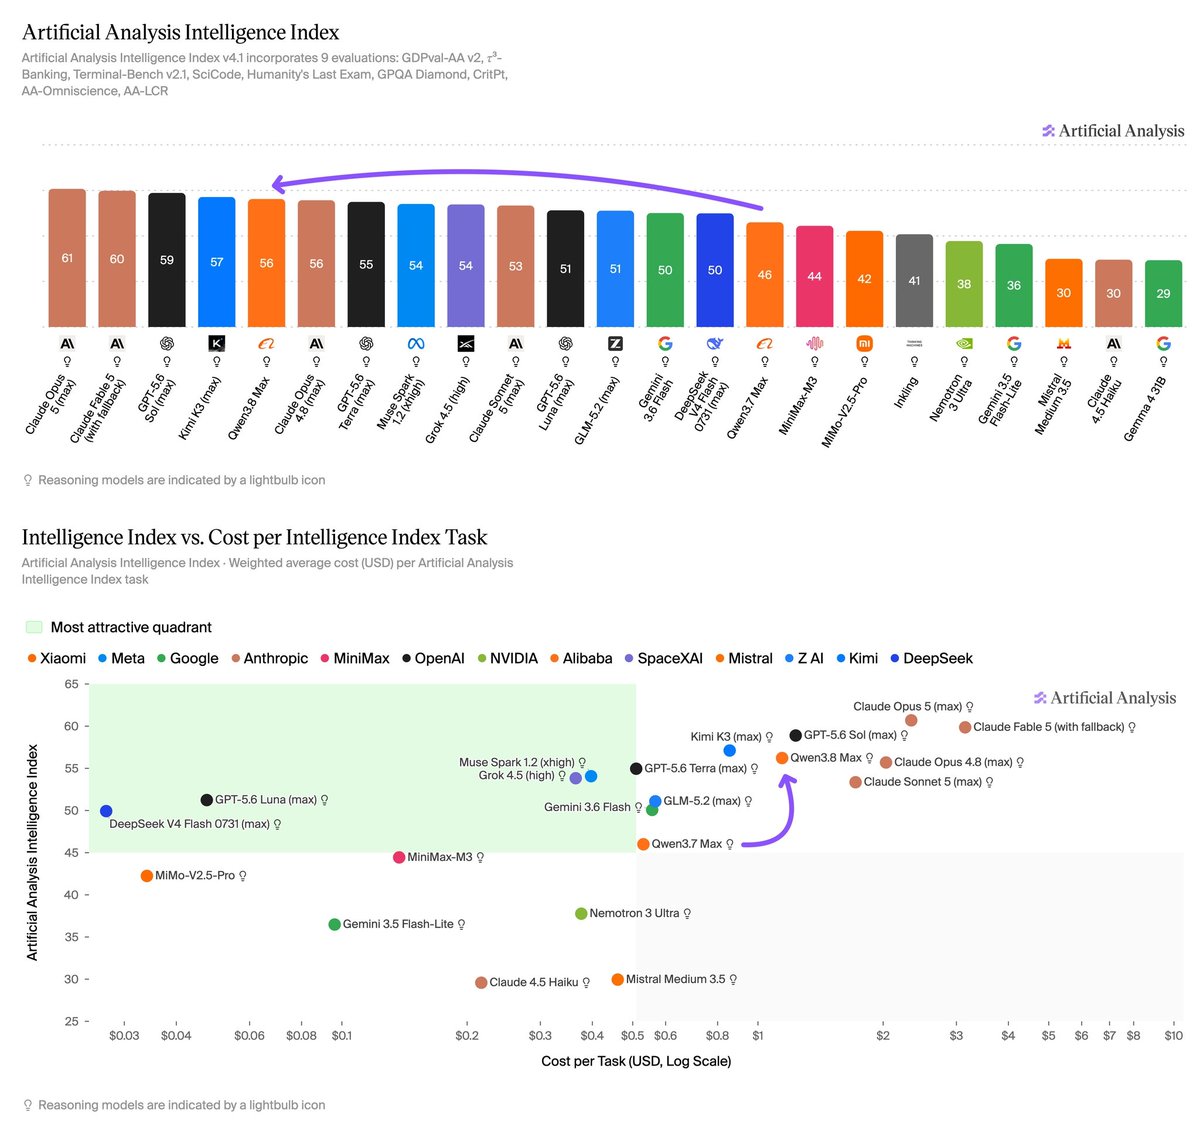
Qwen3.8 Max buys near-frontier intelligence at mid-tier tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → prices, but it is slow at 20 tokens/sec and unusually verbose, which pushes real cost per task above what the per-token sticker suggests.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.