The Claude Caching Trick That Cut One Team's Bill 7x
- Source
- x.com
- Date

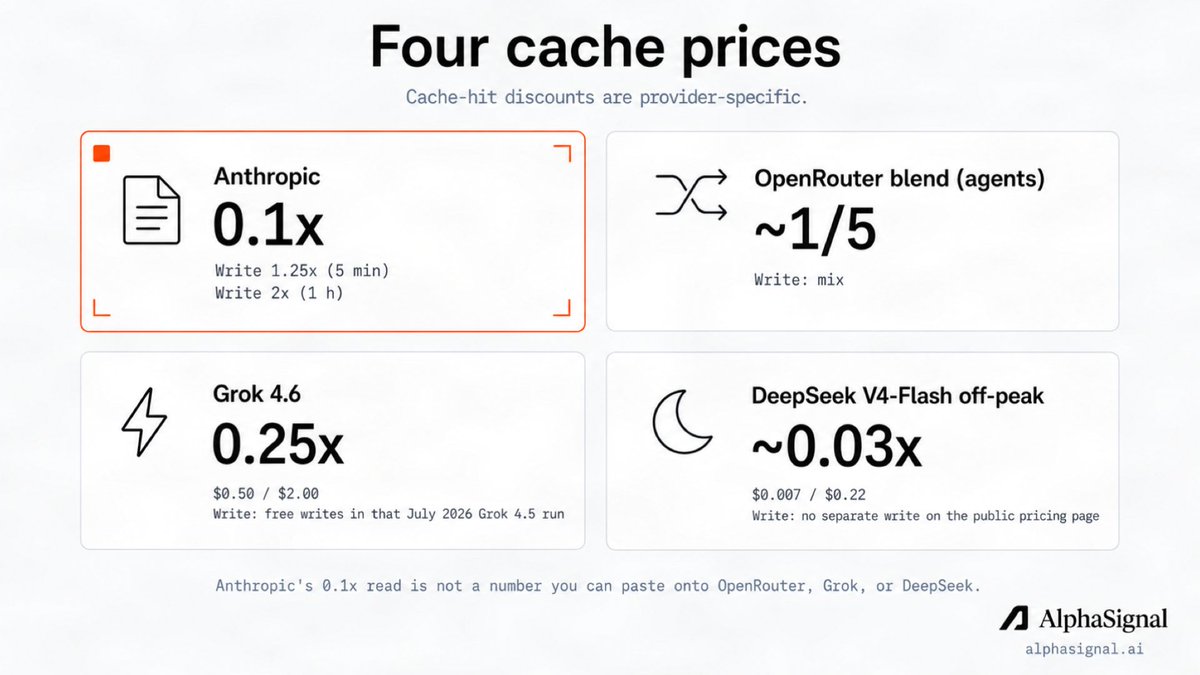
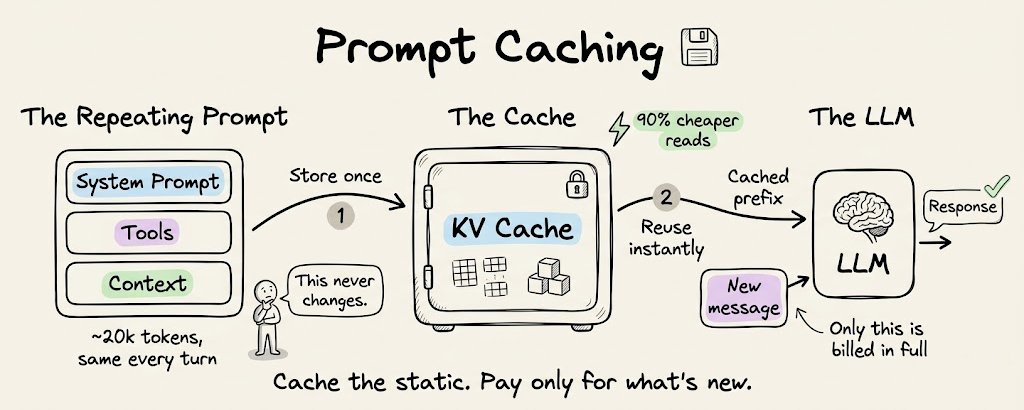
Anthropic's automatic caching billed us $0.022 per turn for the same 8,400 tokens that cost $0.003 once we placed the cache marker by hand Automatic caching means one switch, and the system decides what to save. Manual caching means you mark the exact block yourself, so nothing varying ever poisons the entry. That single difference explains the whole gap, and our meter confirmed it across every repeat. So we wrote down every trick that moved the bill, and each one ships with code you can paste. Every figure below comes from our own runs > Mark the stable prefix > Buy minutes, not hours > Read the usage meter > Batch the night shift Then come the two that need explaining. Split planner from executor across two sessions. Cap thinking before it eats its own output. Our mid-thread model switch billed $0.197 with zero hits. The two-session version read its cache for $0.011, which means the second prefix never charged twice. Anthropic's docs describe all six features. Our meter readings show what each one actually saves. The full tutorial walks through every trick with Python and cURL. Full breakdown ↓↓

Context
AlphaSignal reports that Anthropic's automatic billed them $0.022 per turn for the same 8,400 that cost $0.003 once they placed the cache marker by hand. Prompt caching lets a repeated block of be reused across API calls. Automatic caching means the system decides what to save, while manual caching means marking the exact block yourself, and AlphaSignal says this is what keeps anything that varies from poisoning the cached entry, an explanation it says its meter confirmed across repeats.
AlphaSignal also reports that a mid-thread model switch billed $0.197 with zero cache hits, while a two-session version, splitting planner from executor, read its cache for $0.011. These are AlphaSignal's own figures from its own runs, so other workloads may see different ratios.
- prompt caching — Reusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
“Anthropic's automatic caching billed us $0.022 per turn for the same 8,400 tokens that cost $0.003 once we placed the cache marker by hand”
“Automatic caching means one switch, and the system decides what to save.”
“Our mid-thread model switch billed $0.197 with zero hits.”
“The two-session version read its cache for $0.011, which means the second prefix never charged twice.”
Checking sign-in…
Loading comments…