HY-MT1.5 pairs a 1GB on-device translator with a 7B cloud model
- Source
- x.com
- Date

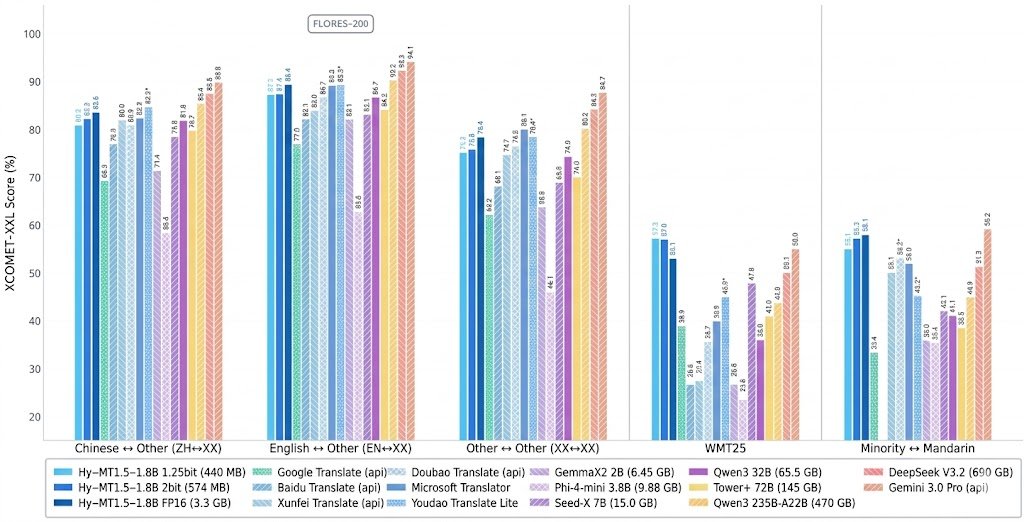
🚀🚀🚀We are excited to open-source Tencent-HY-MT1.5, featuring two translation models—1.8B and 7B—designed for seamless on-device and cloud deployment with industry-leading speed and accuracy. Highlights: 🔹 1.8B On-Device Power: Optimized for consumer hardware with a 1GB memory footprint. Using on-policy distillation to align with larger models, it delivers 0.18s latency (50 tokens), outperforming mainstream commercial APIs. 🔹 7B SOTA Performance: An upgraded version of our WMT25 champion, surpassing mid-sized open-source models and rivaling the 90th percentile of closed-source giants like Gemini-3.0-Pro. 🔹 33+ Languages & Dialects: High-fidelity translation across 33 languages and 5 Chinese dialects. 🔹 Production-Ready: Native support for custom terminology, long-dialogue context, and maintaining document formatting. Already powering multiple Tencent services, our dual-model synergy ensures consistent and stable performance across both on-device and cloud environments. 🌍 👉🏻 Try it now: https://t.co/MOGj8Uwzwu 🔗 GitHub: https://t.co/a65YZGBj7B 🤗 Hugging Face:
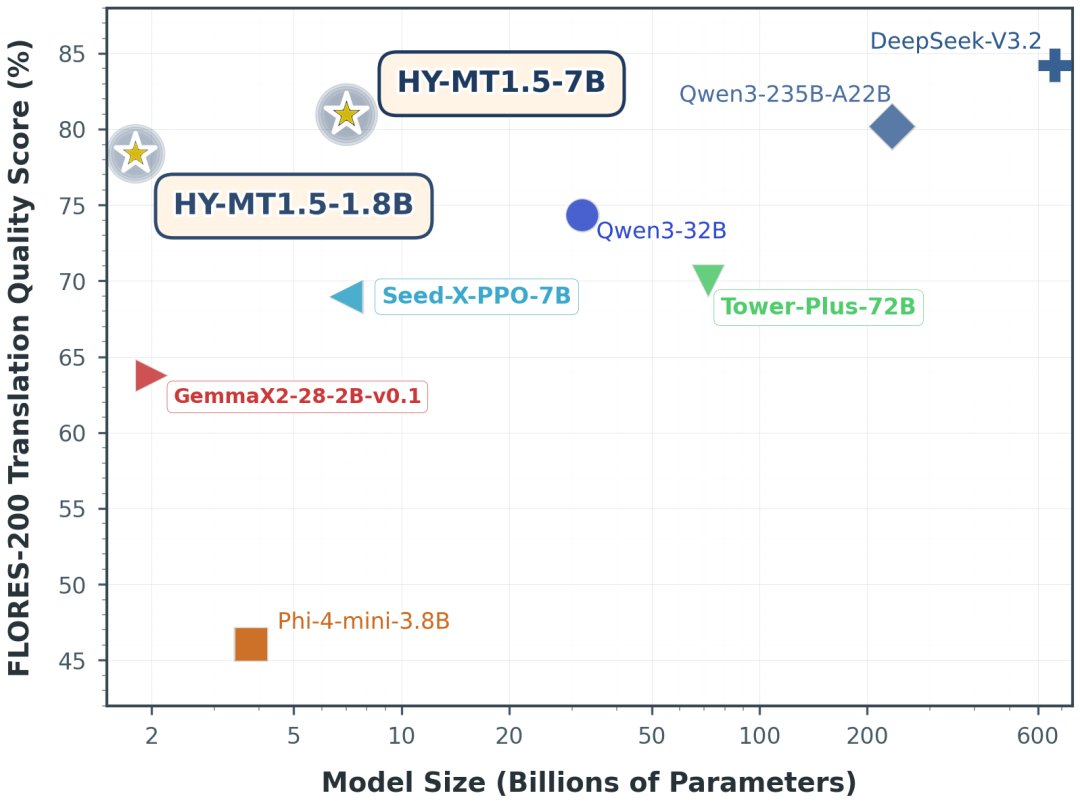
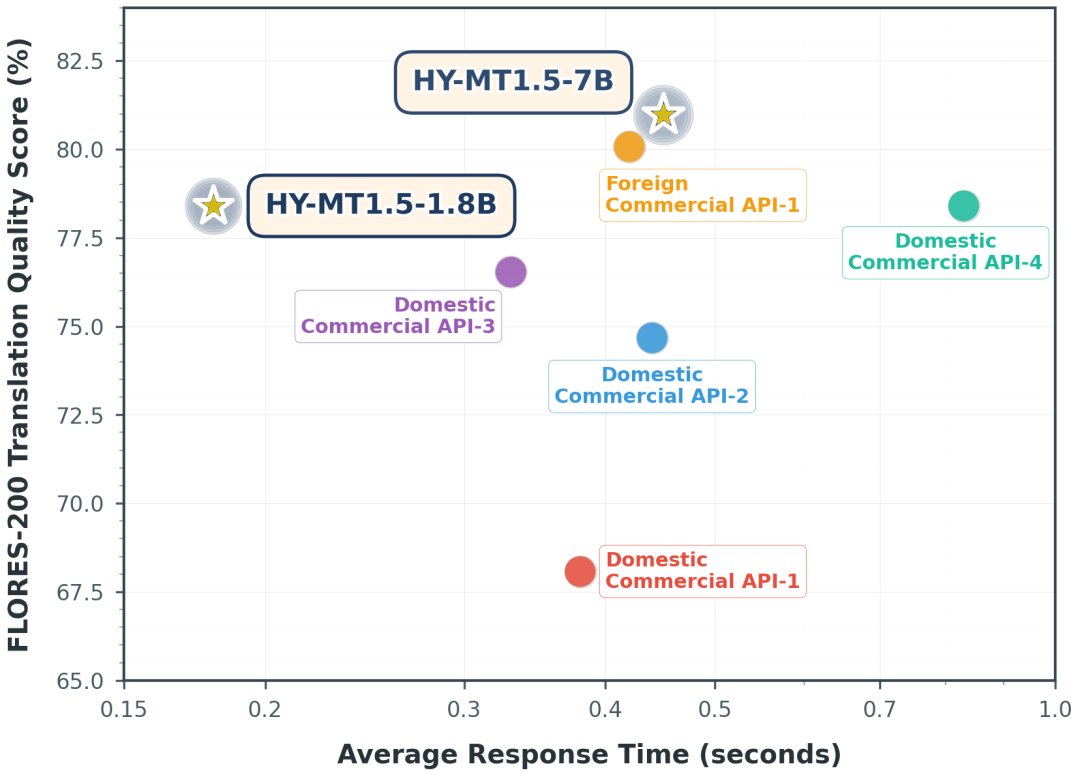
Now Tencent-HY-MT1.5-1.8B is the #1 trending model on Hugging Face! 🥇📈 Huge thanks to the community for the support! https://t.co/FWKn70KSIW

Context
Tencent's HY-MT1.5 gives developers two sizes of translation model: a 1.8-billion-parameter version intended for deployment on devices after compression, and a larger 7-billion-parameter version. Both support translation among 33 languages. The project documentation also supplies prompts for preferred terminology, surrounding and formatted text.
Those controls let an application tell the translator which meaning or wording to preserve. Context can be supplied as background without asking the model to translate it, while terminology instructions specify how particular terms should appear. The choice therefore concerns both where translation runs and how an application guides its output.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
 articleExplorationBench: Feedback and Self-Designed Probes Drive Agent Discovery
 postHy Image3.5 preview is live. 🚀 Professional-grade image generation, +30% win…
 postTencent Hunyuan's EvolveScaler trips up frontier models on evolving facts
 postTencent Hunyuan open-sources AuK, a unified speech generation and editing model
Checking sign-in…
Loading comments…