Mimo V2 Pro Everything You Need To Know
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
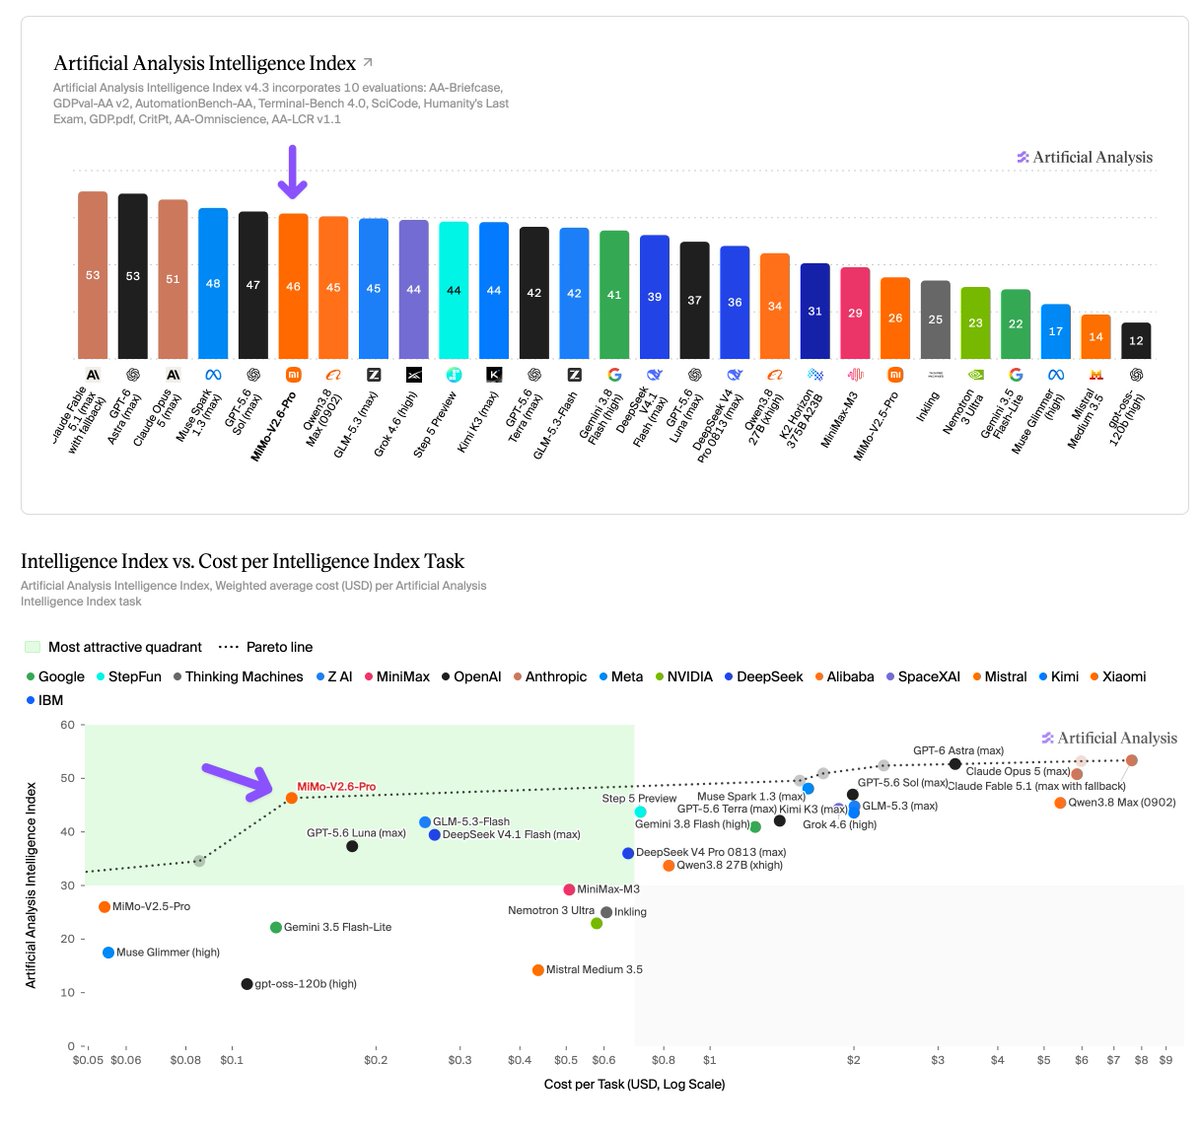
Xiaomi's MiMo-V2-Pro scores 49 on the Artificial Analysis Intelligence Index, one point behind GLM-5 (Reasoning) at 50 and ahead of Kimi K2.5 (Reasoning) at 47 and Qwen3.5 397B A17B (Reasoning) at 45 (artificialanalysis.ai). That places it tenth overall. It is a large step up from Xiaomi's previous release, MiMo-V2-Flash, which scores 41, but there is a difference in access: Flash came with under the MIT license, while MiMo-V2-Pro is so far available only through Xiaomi's own API.
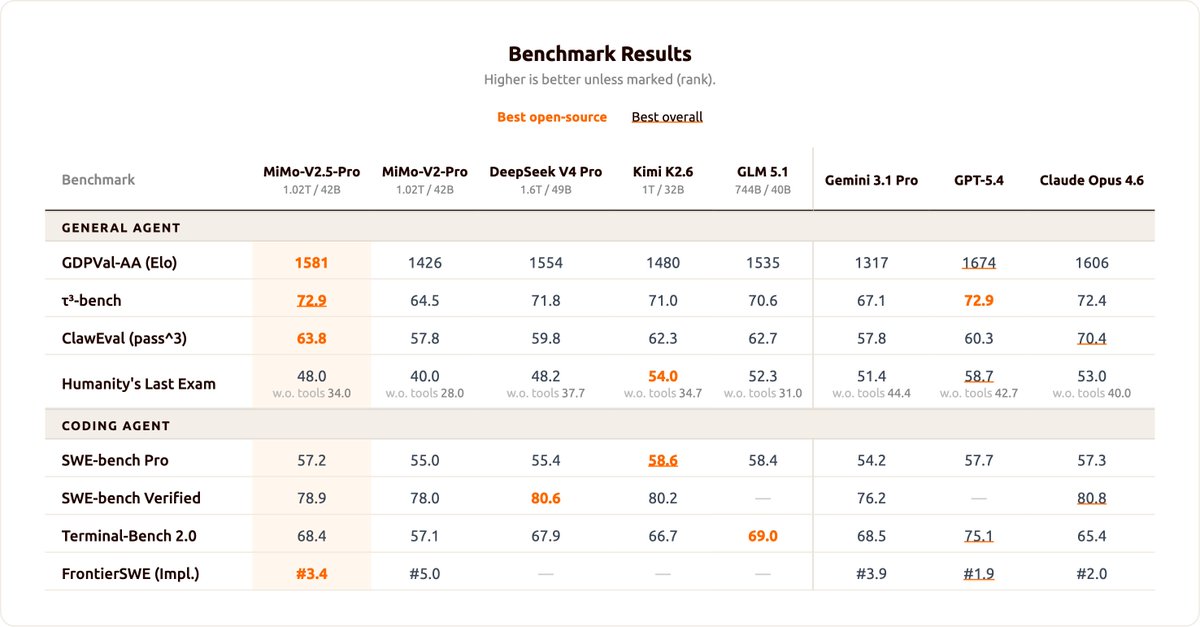
Its strongest result is on GDPval-AA, Artificial Analysis's test of agentic real-world work tasks. MiMo-V2-Pro scores 1426, ahead of GLM-5 at 1406, Kimi K2.5 at 1283 and Qwen3.5 397B A17B at 1209, which makes it the leader among models from China, though GPT-5.4 (xhigh) at 1667 and Claude Sonnet 4.6 at 1633 remain well ahead. It also scores +5 on AA-Omniscience, which adds a point for a correct answer, subtracts one for a wrong answer and gives nothing for declining. That result rests on a low rate of 30%, down from 48% for MiMo-V2-Flash, and puts it ahead of GLM-5 at +2 but behind Claude Opus 4.6 at +14 and Gemini 3.1 Pro Preview at +33.
It is also economical to run. MiMo-V2-Pro used 77M output across the index, against 109M for GLM-5 and 89M for Kimi K2.5, and cost $348 at $1 input and $3 output per million tokens, less than GLM-5 for a score one point lower and a fraction of GPT-5.2 (xhigh) at $2,304. Five days later, MiniMax-M2.7 scored 50, scored higher on GDPval-AA at 1494 and cost about half as much to run the index.
- MiMo-V2-Pro's GDPval-AA Elo of 1426 leads GLM-5 (1406), Kimi K2.5 (1283) and Qwen3.5 397B (1209), but trails GPT-5.4 (xhigh) at 1667 and Claude Sonnet 4.6 at 1633.
- Its AA-Omniscience Index of +5 comes mainly from a 30% hallucination rate, down from 48% for Xiaomi's earlier open-weights MiMo-V2-Flash; Claude Opus 4.6 (+14) and Gemini 3.1 Pro Preview (+33) remain ahead.
- MiMo-V2-Pro used 77M output tokens to run the Intelligence Index, against 109M for GLM-5 and 89M for Kimi K2.5, and cost $348 to run, compared with $2,304 for GPT-5.2 (xhigh).
- Pricing doubles to $2/$6 per million tokens for inputs beyond 256K, up to the 1M window, and the model is text-only with no image input.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.




Checking sign-in…
Loading comments…