Fugu-Ultra v1.1 gains up to 7.9 benchmark points at same price
- Source
- x.com
- Date

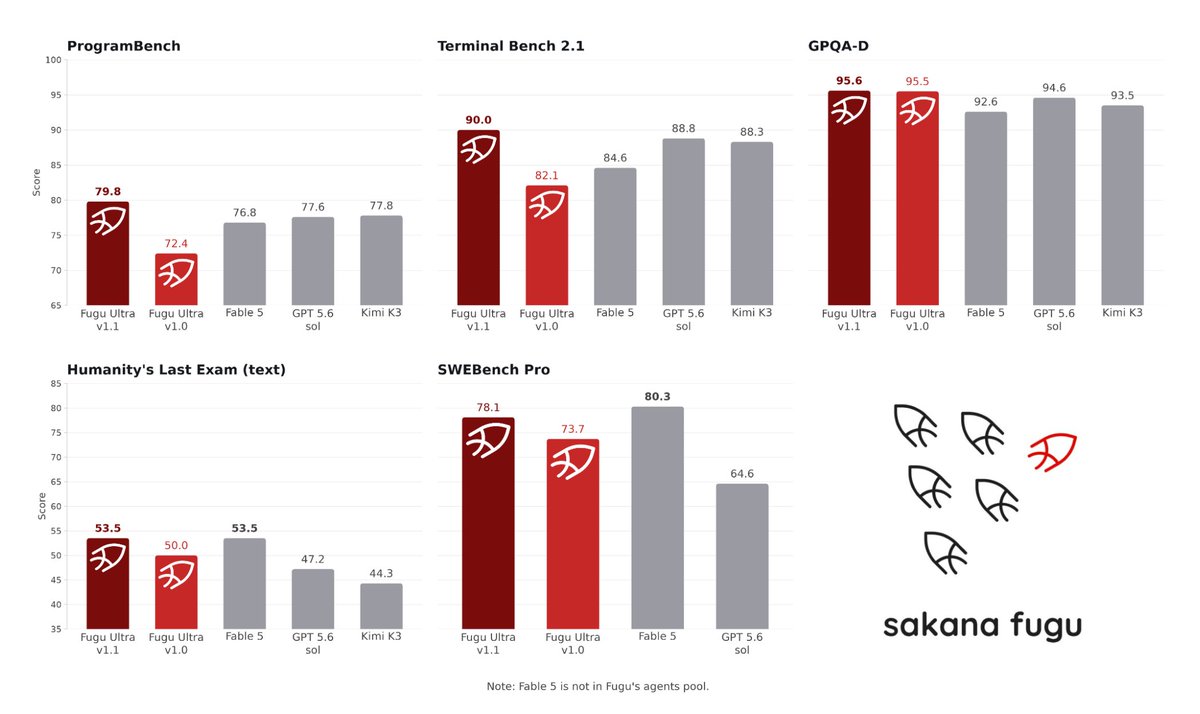
Announcing Fugu-Ultra v1.1 🐡 We’ve been thrilled by the reception to the Fugu model family. Thanks to everyone who tried it, shared feedback, and trusted Fugu with real work. Today, we’re releasing Fugu-Ultra v1.1 → https://t.co/hhO6qTawgb Upgraded to incorporate the latest frontier models, resulting in stronger performance across every benchmark shown, including gains of up to 7.9 points over v1.0, with particularly strong results on ProgramBench and Terminal Bench 2.1. Fugu-Ultra v1.1 is more capable across coding, agentic tasks, and advanced reasoning, and available at the same price as Fugu-Ultra v1.0 The frontier keeps moving, and Fugu keeps getting better.
Context
Sakana AI attributes Fugu-Ultra v1.1's improvement mainly to the newer models it now directs. Sakana sells Fugu as a single API that coordinates a pool of other AI models, choosing which ones to call for each task and combining their work into one answer, and its product page describes Fugu-Ultra as the tier that uses a deeper pool to maximize answer quality on hard problems. Sakana's announcement says v1.1 was upgraded to incorporate the latest frontier models and costs the same as v1.0.
The 7.9 points is the largest single gain, not an average across tests. Sakana says v1.1 scored higher than v1.0 on every it showed, by up to 7.9 points, with particularly strong results on ProgramBench and Terminal Bench 2.1. The post gives the individual scores only in an attached chart, and all of them are Sakana's own measurements. Sakana's product page also says Fugu does not reveal which underlying models handled a given request, so customers cannot check which newly added models account for the improvement.
v1.1 is no longer the current version. The product page now lists pricing for fugu-ultra-v2.0, which Sakana released alongside Fugu Max. The page also says that when a new frontier model is released publicly, Sakana expects to spend roughly two weeks training and evaluating updated Fugu models before rolling them out. The v1.1 announcement describes an upgrade of that kind: newer frontier models added to the pool Fugu directs.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…