NVIDIA Exemplar Cloud: Lessons for Unlocking Full Performance on AI Infrastructure
- Source
- developer.nvidia.com
- Author
- Elizabeth Goodman
- Date
Context
A healthy host-level can miss the configuration actually slowing a training job. In a B200 deployment described by NVIDIA, communication tests looked normal on the host, while operations that exchanged data between GPUs were two to four times slower inside the workload container. The container lacked both a network-topology configuration file and the setting pointing to it, so the communication library fell back to automatic detection. The case study identifies the missing runtime configuration as the problem. It shows why performance checks need to run through the same container and launch environment as the actual training workload.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
“Two AI computing clusters built from identical NVIDIA H100, GB200 NVL72, or GB300 NVL72 systems can deliver materially different training throughput. We routinely see 8% to 12% gaps between partner deployments and the corresponding NVIDIA reference architecture (RA) on the same workload, same model, same global batch size.”
NVIDIA
“The CPU on the partner cluster was configured with C-states limited to C1 in BIOS. This is a common “low-latency” default that is actively wrong for AI training workloads.”
NVIDIA
“Allowing the idle cores to drop to C6 freed power headroom, enabling the busy cores to climb to 3.8 GHz and recover roughly 4% on this workload.”
NVIDIA
“Don’t increase QPS everywhere. QPS is fabric- and workload-dependent.”
NVIDIA
“If the path doesn’t resolve, NCCL fails silently with no error making this one of the harder gaps to diagnose without knowing where to look.”
NVIDIA
 articleHow NVIDIA OpenShell Reference Architecture Secures and Governs AI Agent Workloads at Scale
 articleCode, Test, and Deploy on One Machine with NVIDIA RTX Spark
 articleHow to Rewrite Apache Spark UDFs for GPU Acceleration with AI Agents
 articleLower the Cost of Building and Running Visual AI Agents with NVIDIA VSS Blueprint 3.3
 articleH100 vs GB200 NVL72 Training Benchmarks – Power, TCO, and Reliability Analysis, Software Improvement Over TimeDylan Patel
 blogNVIDIA Vera Rubin NVL72 Delivers Leading Performance in MLPerf Inference v6.1 DebutZhihan Jiang
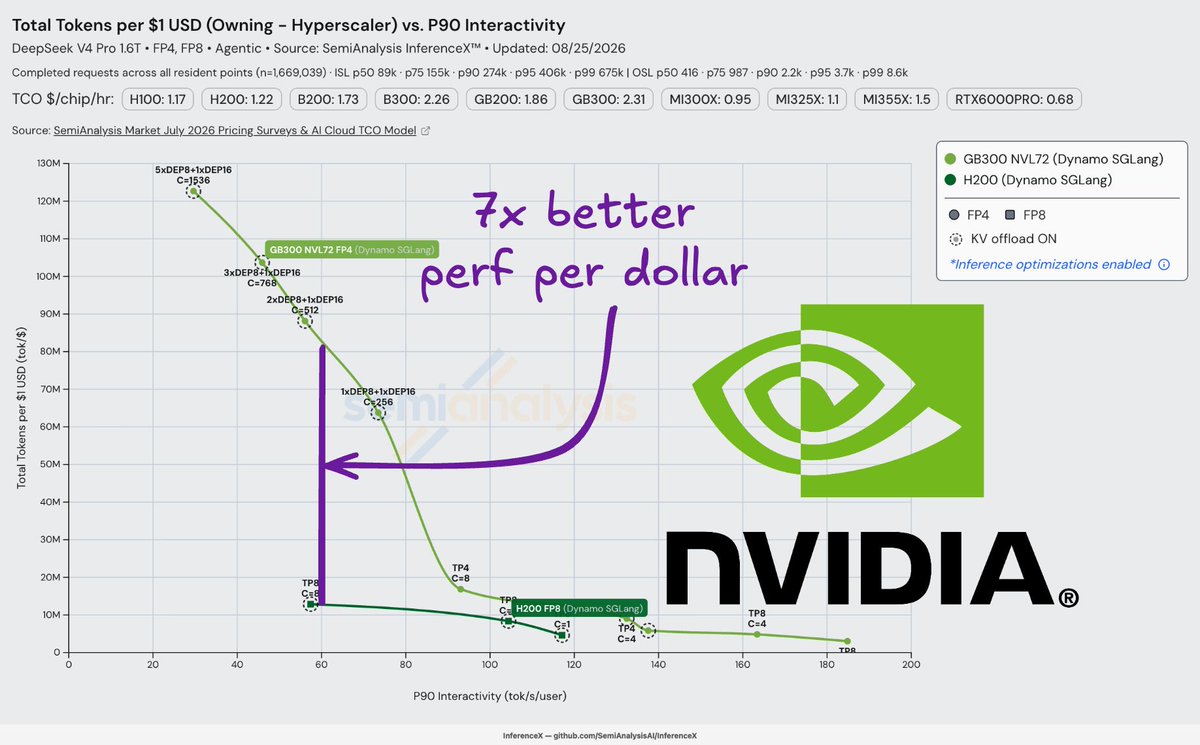 postGB300 NVL72 claimed at 7x perf-per-dollar over H200 for agentic inferenceSemiAnalysis
Checking sign-in…
Loading comments…