MiMo-V2.5 series targets 1,000-tool-call tasks at claimed half the token cost
- Source
- x.com
- Date

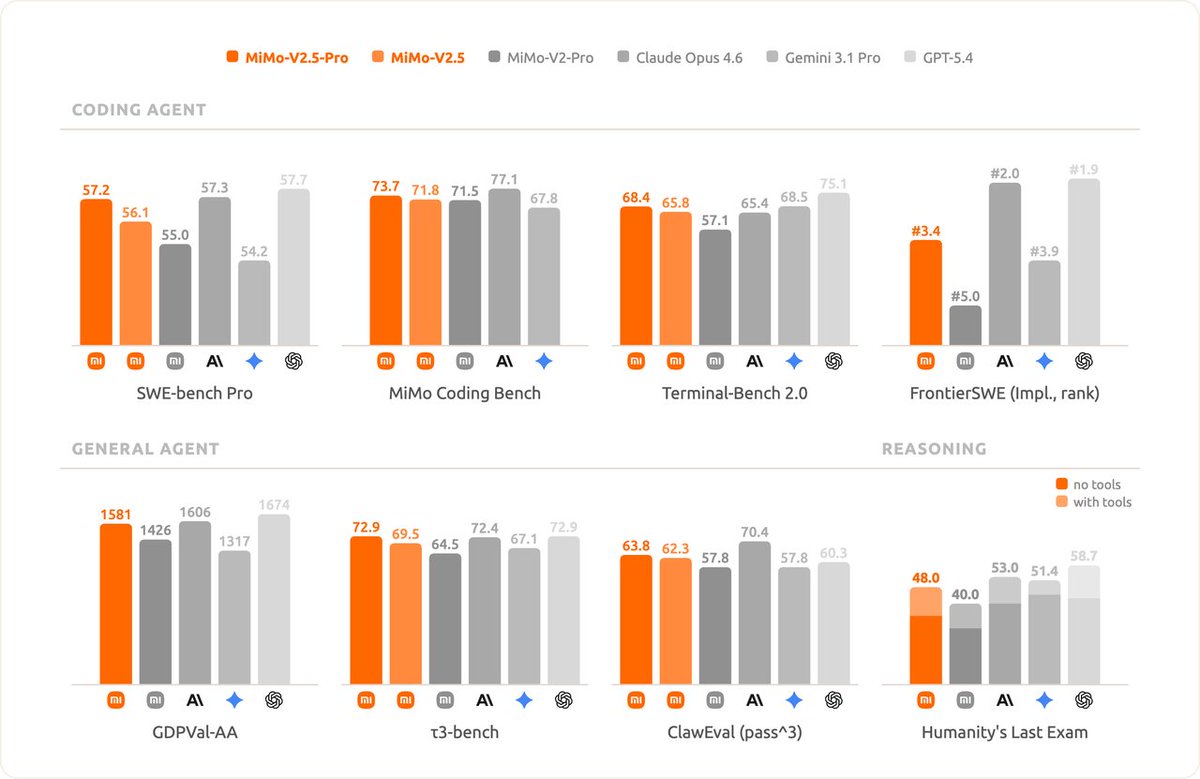
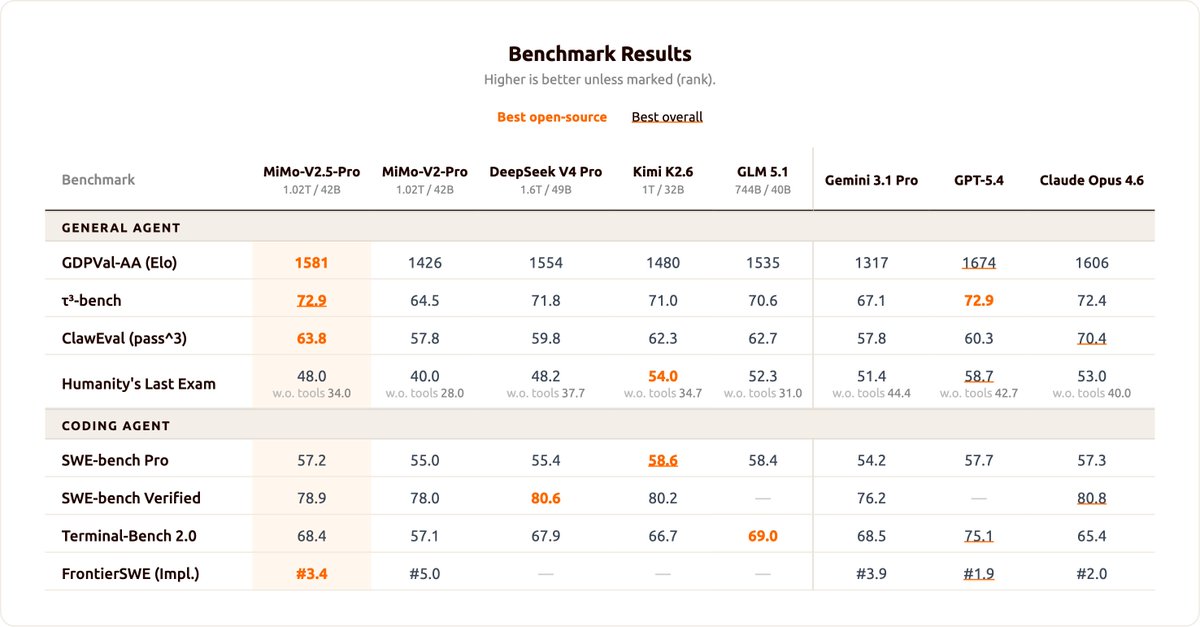
Xiaomi MiMo-V2.5 Series: Pushing Open-Source Agents Forward 🔸 MiMo-V2.5-Pro, our strongest model yet. A major leap from MiMo-V2-Pro in general agentic capabilities, complex software engineering, and long-horizon tasks, now matching frontier models like Claude Opus 4.6 and GPT-5.4 across most benchmarks (SWE-bench Pro 57.2, Claw-Eval 63.8, τ3-Bench 72.9). It can autonomously complete professional tasks involving 1,000+ tool calls, work that would take human experts days. Tech Blog: https://t.co/I275kxl9kL 🔸 MiMo-V2.5, native omnimodal with strong agentic capabilities. Pro-level agent performance at roughly half the cost. Improved multimodal perception across image and video understanding, native 1M-token context window, and significantly more efficient inference. Tech Blog: https://t.co/7DLo0n2MNu 🔗 API & Token Plan:
The MiMo-V2.5 series is tuned for token efficiency. At the same ClawEval agent benchmark score: 🔸 MiMo-V2.5-Pro uses 42% fewer tokens than Kimi K2.6 🔸 MiMo-V2.5 uses nearly half the tokens of Muse Spark Same frontier performance, at a fraction of the cost.

The MiMo-V2.5 series — how they fit together: 🔸 MiMo-V2.5-Pro: built for long, complex agent tasks that demand deep reasoning. 🔸 MiMo-V2.5: covers most general-purpose agent scenarios at 100–150 tokens/s, with native omni-modal capabilities across image, audio, and video. V2.5-Pro for the hardest tasks. V2.5 for speed and modality.
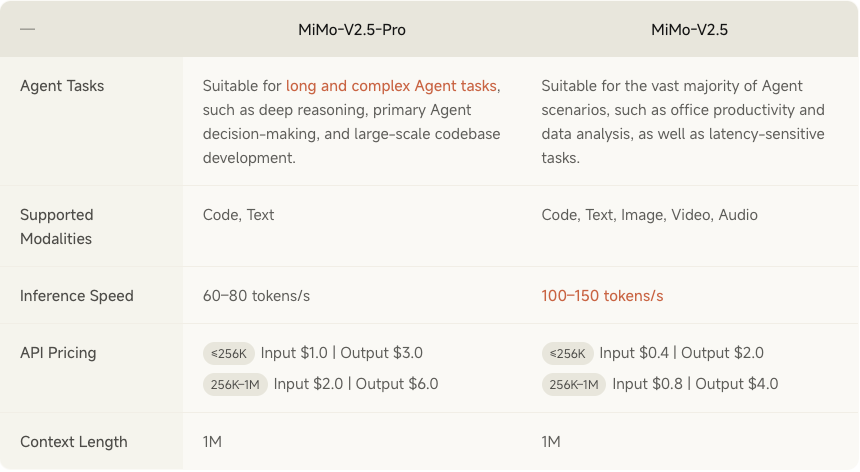
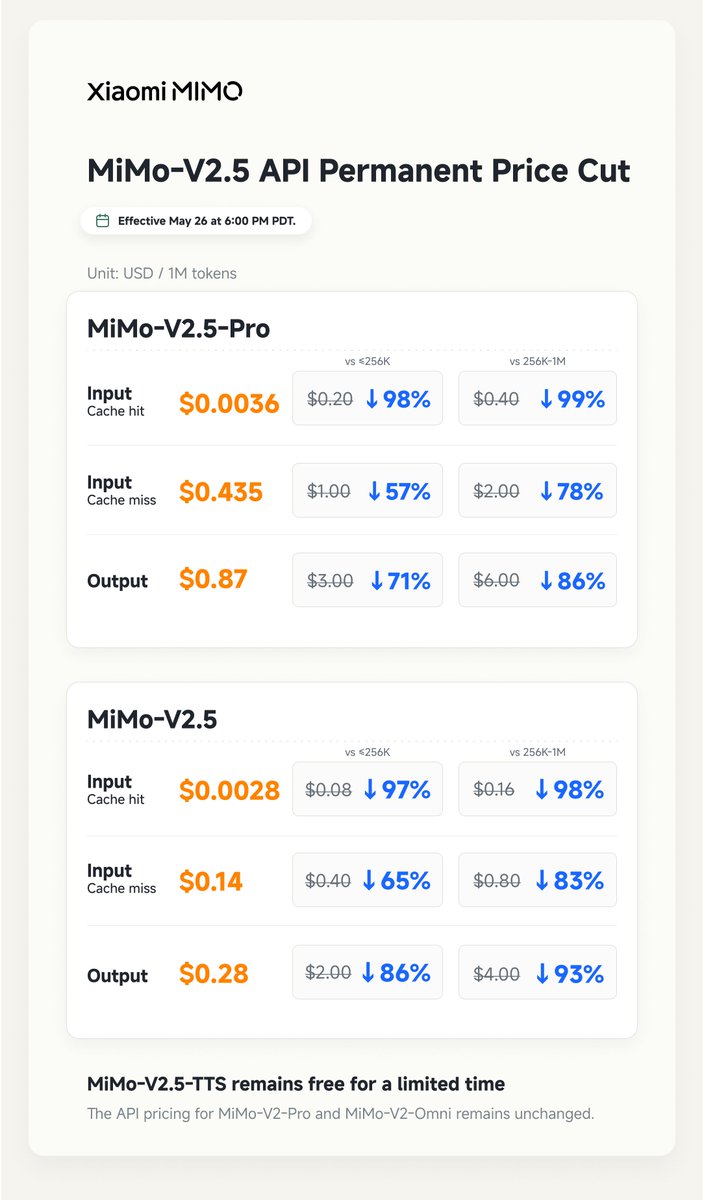
Token Plan Update Alongside stronger models, we've upgraded our inference infrastructure — and your Token Plan gets better too. Simpler, lower credit rates: • MiMo-V2.5: 1x (1 token = 1 credit) • MiMo-V2.5-Pro: 2x (1 token = 2 credits) From now on, Token Plans (https://t.co/P74SR2MaJe) no longer charge a multiplier for the 1M context window.

Context
Xiaomi introduced its MiMo-V2.5 series as two models built around getting -level performance without spending unnecessary tokens. According to Xiaomi's own announcement, MiMo-V2.5-Pro targets long, complex agent and coding tasks and can reportedly complete professional work spanning more than 1,000 tool calls autonomously; Xiaomi says it now matches frontier closed models including Claude Opus 4.6 and GPT-5.4 on named benchmarks it lists ( Pro, Claw-Eval and tau3-Bench, with specific scores given for each). MiMo-V2.5 is the second, general-purpose model: Xiaomi describes it as native omnimodal, with improved image and video understanding, a 1-million-token , and roughly Pro-level agent performance at about half the cost.
Xiaomi also reports a token-efficiency comparison at matched scores: it says MiMo-V2.5-Pro used 42 percent fewer tokens than Moonshot AI's Kimi K2.6, and MiMo-V2.5 used nearly half the tokens of Meta's Muse Spark, to reach the same ClawEval agent-benchmark score. These are Xiaomi's own comparative measurements, not results reproduced by an outside evaluator. Alongside the release, Xiaomi simplified its Token Plan pricing and removed a surcharge it had previously applied for using the full 1-million-token context window.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…