Github Copilot Fusion Orchestrates Anthropic And Openai Models To Balance Performance And Cost
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
Copilot Fusion is an option in GitHub Copilot's model picker that chooses the models for you. For each request it picks among Anthropic and OpenAI models, including Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra and GPT-6 Sol, and decides how to use them. GitHub's documentation describes three patterns: one model does the task; a cheaper model drafts and a judge either accepts the draft or escalates to a stronger model; or one model drafts, several others critique it in parallel, and the first revises. Fusion carries no separate fee. You pay each underlying model's standard rate.
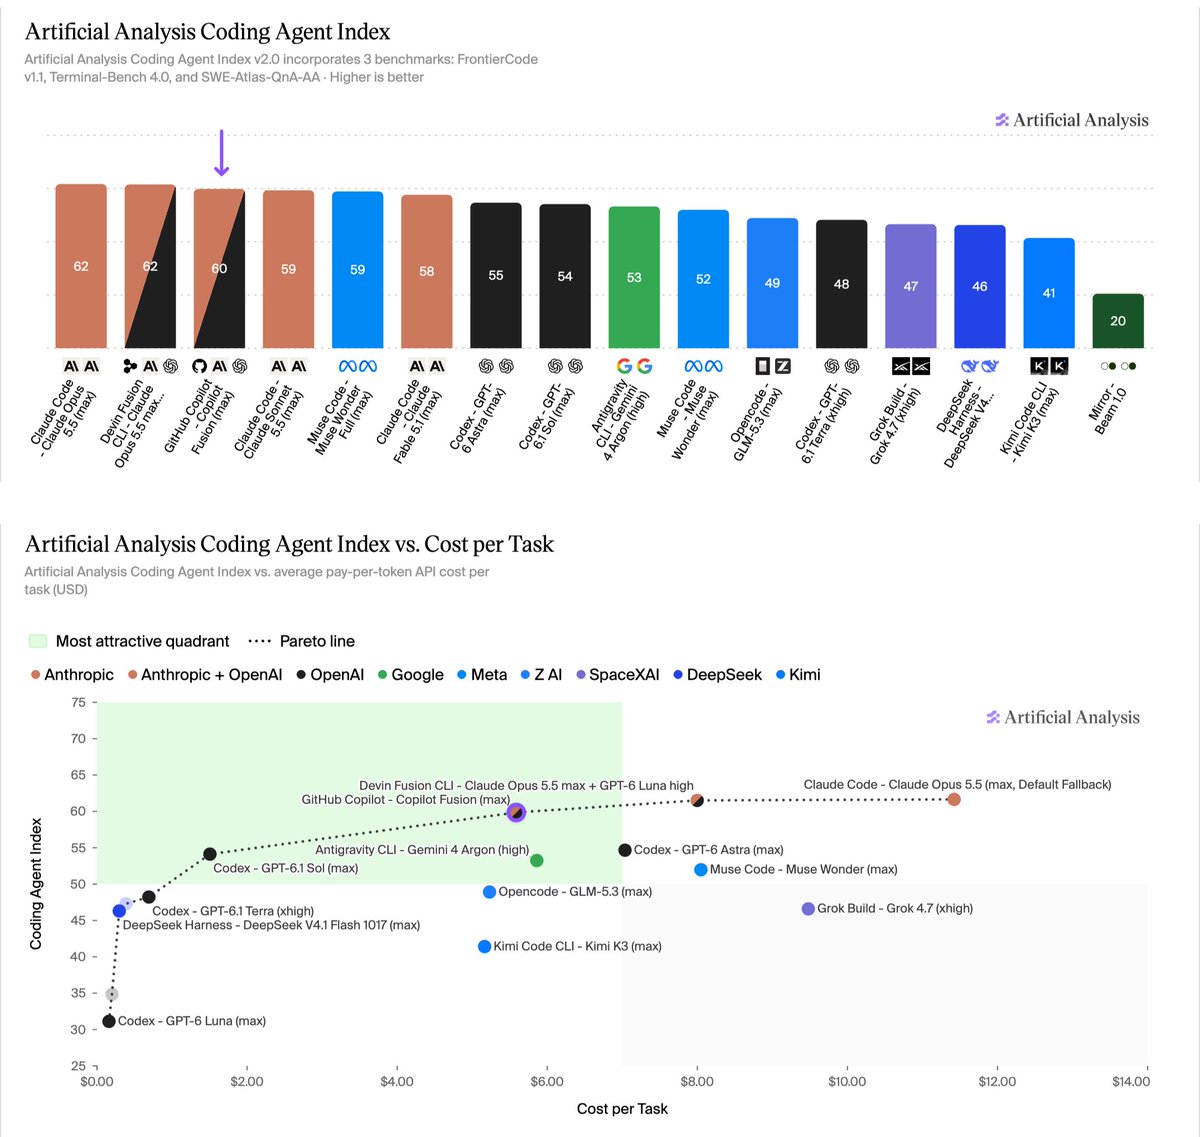
Artificial Analysis tested Fusion's max setting in Copilot CLI on its Coding Index v2.0, which scores a model together with the coding tool it runs in, across three equally weighted benchmarks. Fusion finished two points below Claude Code running Opus 5.5 at its max setting, at $5.59 per task against $11.42, and used 7.2 million per task, about half as many. It led Terminal-Bench 4.0 with 71. It placed third on FrontierCode at 51, behind Claude Code with Opus 5.5 at 56 and Devin Fusion at 54, and its SWE-Atlas-QnA-AA score lagged at 57.
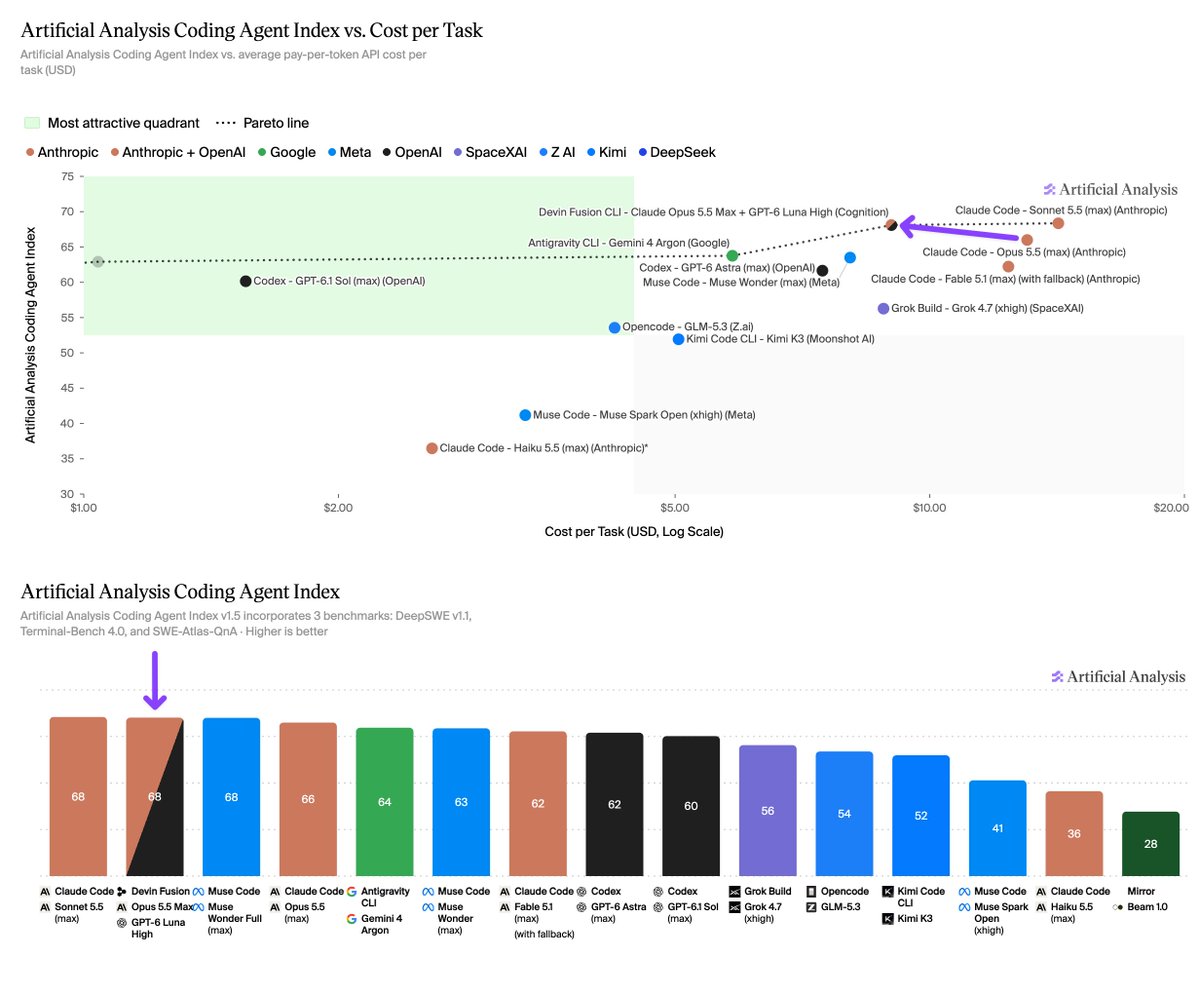
The closest comparison is another router. Cognition's Devin Fusion, which Artificial Analysis first benchmarked in September as the first multi-model coding agent on the index, runs a frontier lead model with a cheaper sidekick; the configuration in this comparison pairs Opus 5.5 with GPT-6 Luna. It scored 62 at $8.00 per task, and Copilot Fusion used 30% fewer tokens than it. The tested max setting is not included on Copilot Free, Student or Pro plans, only on Pro+, Max, Business and Enterprise.
- Copilot Fusion is a runtime orchestrator that picks among Anthropic and OpenAI models, including Claude Opus 5.5, Sonnet 5.5, GPT-6 Astra and GPT-6 Sol, per task. Artificial Analysis measured its max setting 2 points below Claude Code with Opus 5.5 on its Coding Agent Index.
- Fusion cost $5.59 per task versus $11.42 for Claude Code with Opus 5.5 (max), and used 7.2M tokens per task, about half of Opus 5.5 in Claude Code and 30% less than Devin Fusion. Token charges follow whichever underlying models handle the request.
- Its scores are uneven across the index's three equally weighted benchmarks: it leads Terminal-Bench 4.0 at 71, ranks third on FrontierCode at 51 behind Claude Code with Opus 5.5 (56), and lags on SWE-Atlas-QnA-AA at 57.
Checking sign-in…
Loading comments…