Copilot Fusion nears Opus 5.5 coding scores at half the cost per task
- Source
- x.com
- Date

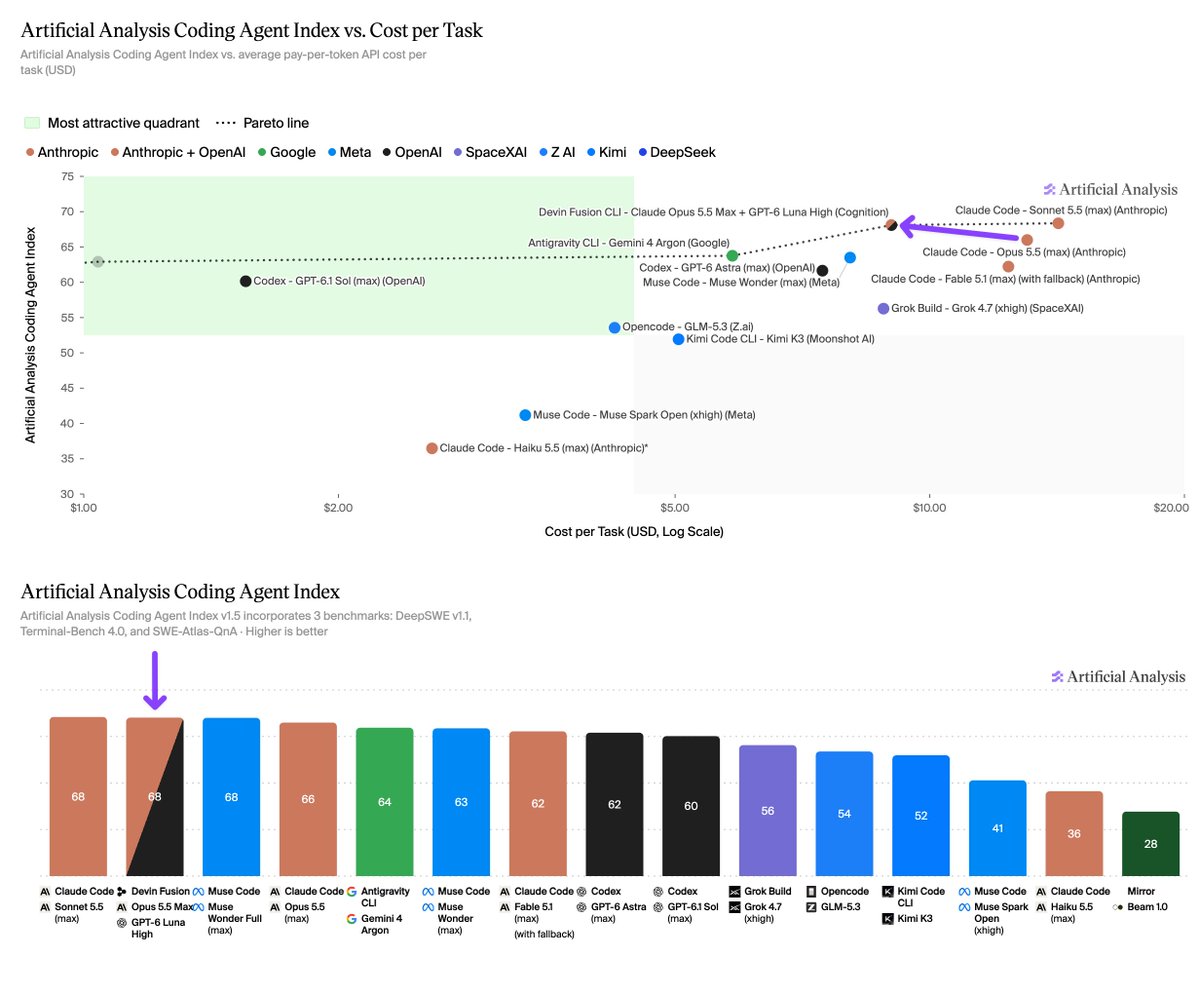
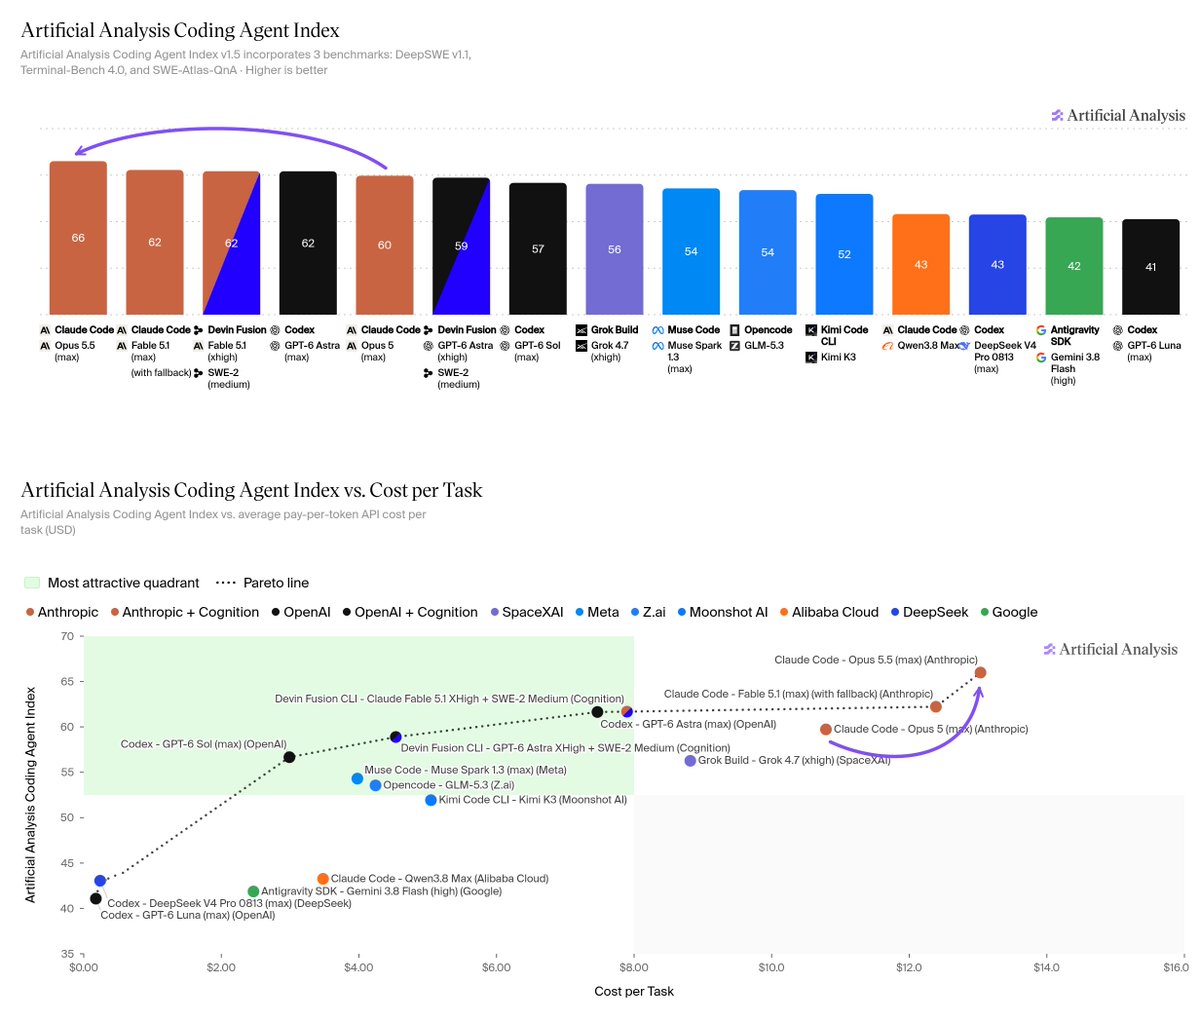
GitHub has released Copilot Fusion in GitHub Copilot, which orchestrates between Anthropic and OpenAI models. It scores 2 points below Opus 5.5 in Claude Code at half the Cost per Task in the Coding Agent Index GitHub describes Copilot Fusion as a runtime orchestration system, which selects and coordinates models to optimize performance, cost, and latency for each task. Copilot Fusion chooses between a number of models from Anthropic and OpenAI, including Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra, and GPT-6 Sol. We benchmarked its max setting in GitHub Copilot CLI in the Artificial Analysis Coding Agent Index v2.0. Token costs are charged based on the underlying models used to complete a request. Key takeaways: ➤ Cost-efficient for near-frontier performance: Copilot Fusion in GitHub Copilot costs $5.59 per task, versus $11.42 for Claude Code with Opus 5.5 (max). Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) scores 62 at $8.00 per task. ➤ Slight lead in Terminal-Bench 4.0: The Coding Agent Index v2.0 weights its three constituent benchmarks equally. Copilot Fusion in GitHub Copilot leads Terminal-Bench 4.0 with a score of 71. It ranks third on FrontierCode in the…

Copilot Fusion routes between Anthropic and OpenAI models and, per Artificial Analysis, scores 2 points below Claude Code with Opus 5.5 at about half the cost per task. Routing across models may cut coding spend with little quality loss.
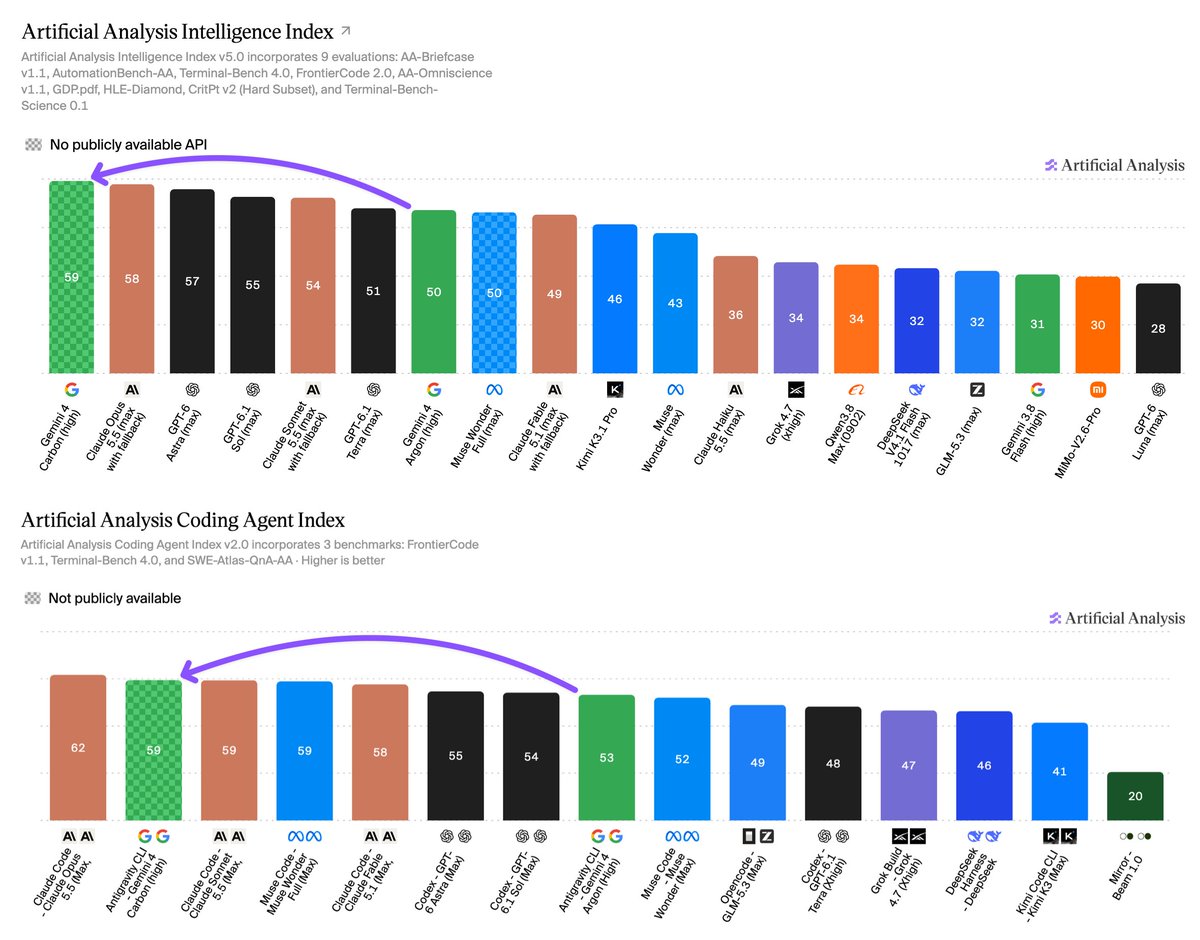 postGemini 4 Carbon takes #1 on Intelligence Index, second on coding agents
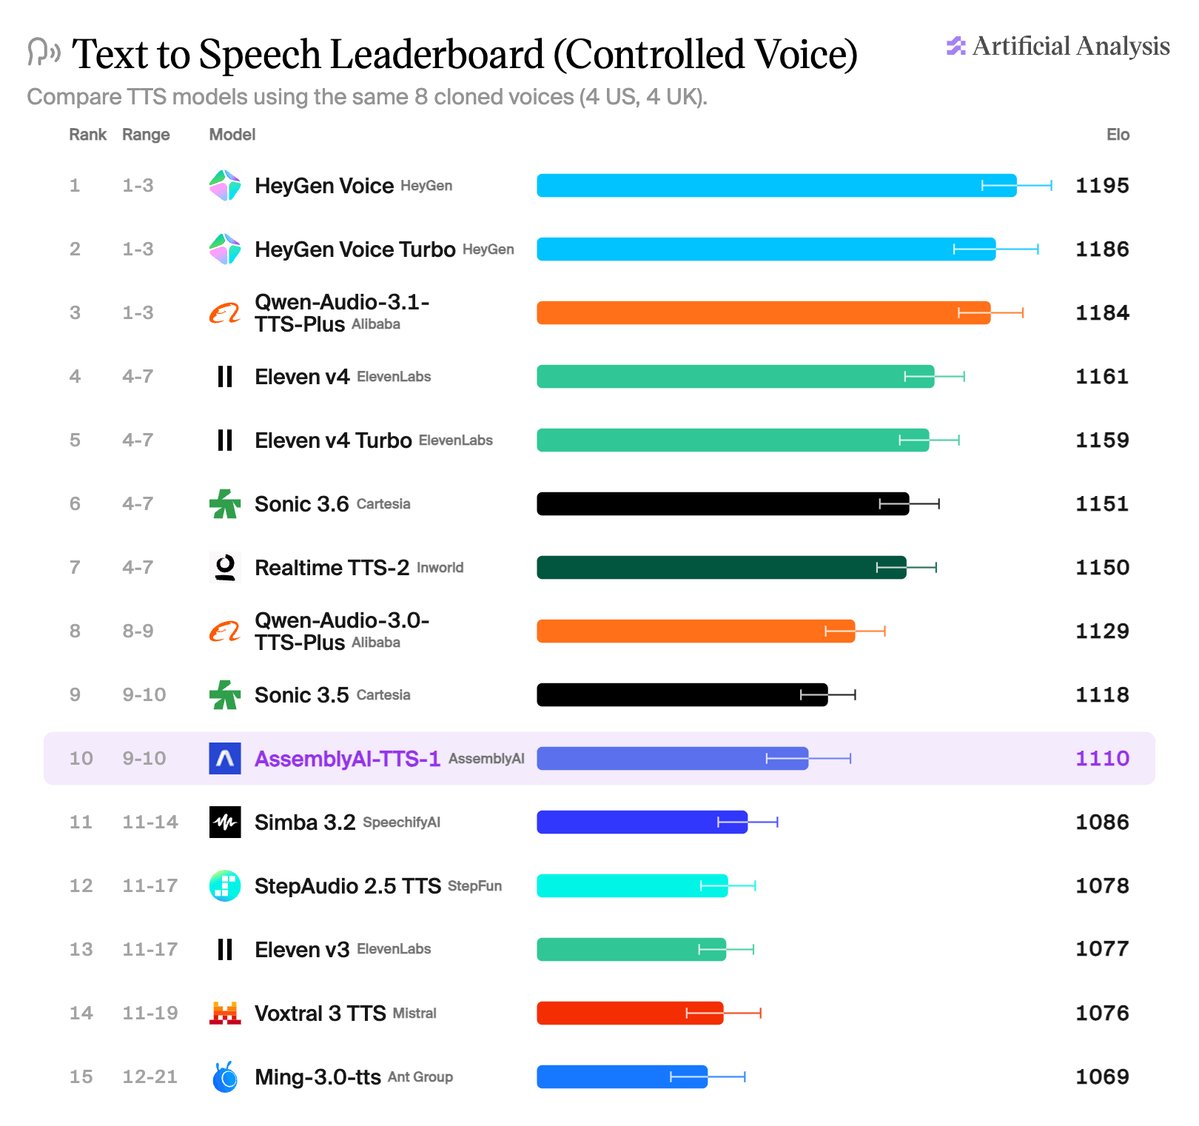 postAssemblyAI-TTS-1 debuts: top-12 voice arena rank at $15 per 1M characters
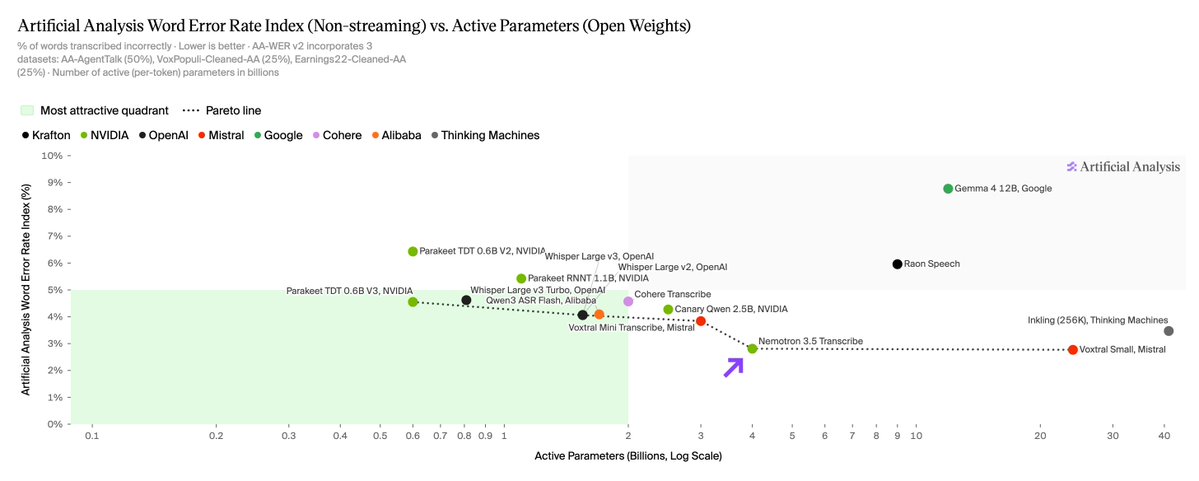 postNemotron 3.5 Transcribe ties for top open-weight STT at 4B active params
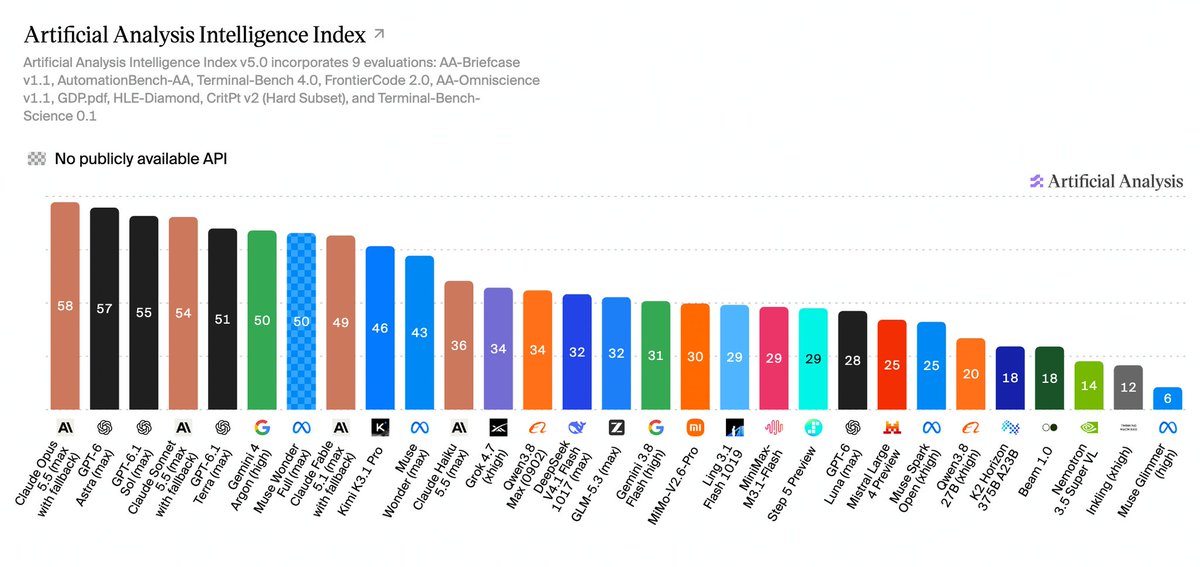 postIntelligence Index v5 goes majority-private and adds agentic coding and science
Checking sign-in…
Loading comments…