Claude Sonnet 5 Agentic Cost
- Source
- artificialanalysis.ai
- Author
- Artificial Analysis articles
- Date
Context
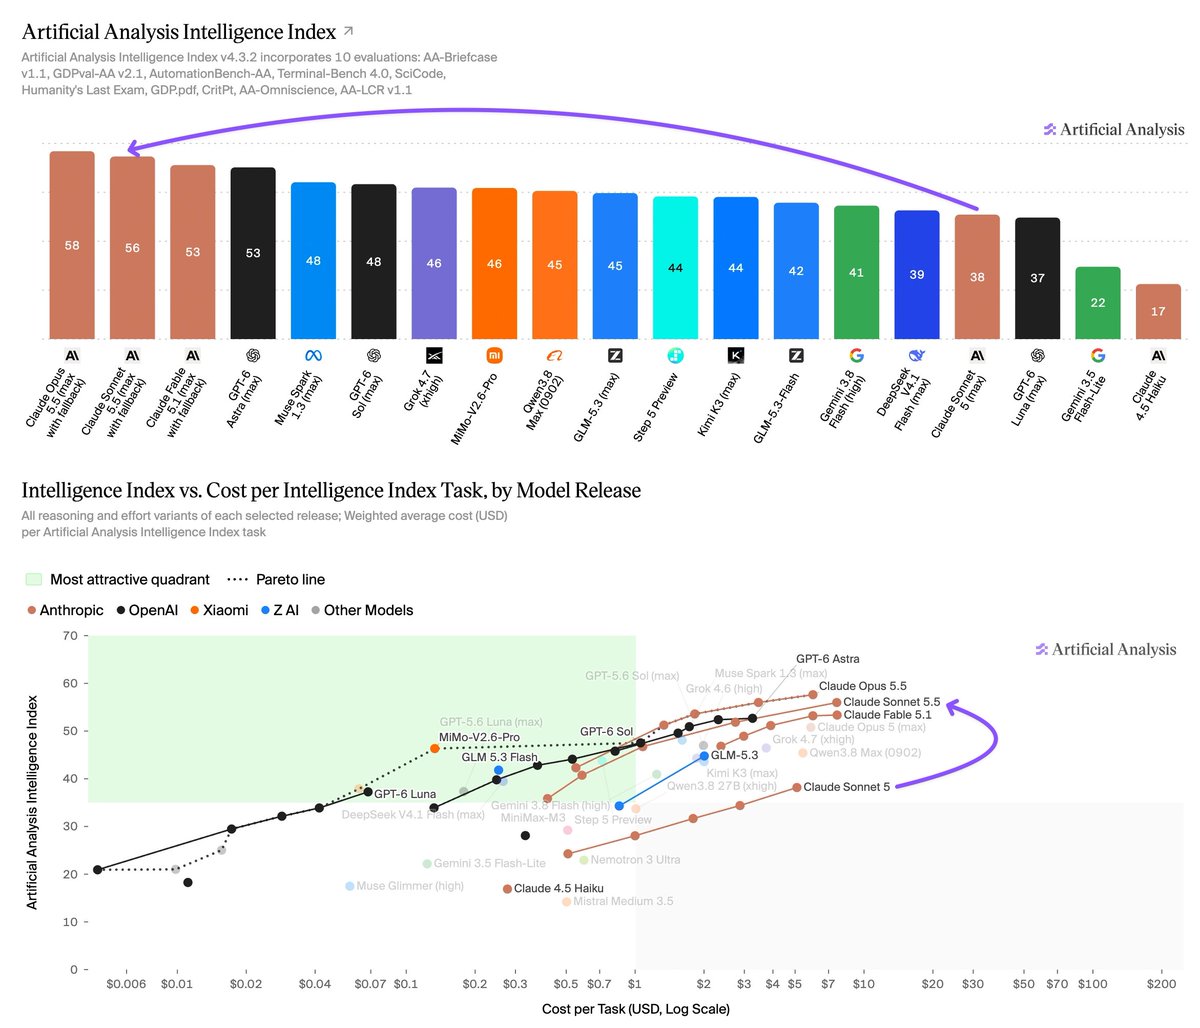
A model's price per and its cost to finish a job are different numbers, because the job's cost also depends on how many tokens the model spends. Artificial Analysis, which says it supported Anthropic in evaluating Claude Sonnet 5 before release, reports that with max effort the model scores 53 on its Intelligence Index, 6 points above Sonnet 4.6. That places it fifth, 2 to 3 points behind GPT-5.5 (xhigh) and Opus 4.8 (max) (artificialanalysis.ai).
Sonnet 5 keeps Sonnet 4.6's standard price of $3 per million input tokens and $15 per million output tokens, against $5 and $25 for Opus 4.8. Even so, Artificial Analysis puts it at $2.29 per Intelligence Index task, about twice Sonnet 4.6 and about 15% more than Opus 4.8, a gap it attributes entirely to higher token usage. At max effort Sonnet 5 used about 40% more output tokens per task than Sonnet 4.6, and about three times the agentic turns on the knowledge-work evaluations AA-Briefcase and GDPval-AA. The effort setting controls how hard it works: on GDPval-AA, max effort used around six times as many turns as low effort.
The extra work does buy results on agentic knowledge work. On both AA-Briefcase and GDPval-AA, which test whether a model can produce accurate, well-presented professional outputs, Sonnet 5 sits just ahead of Opus 4.8 and trails only Claude Fable 5, which was not generally available. On heavy reasoning and knowledge benchmarks Opus 4.8 stays ahead, and on the physics CritPt Sonnet 5 scores 17%. The cost comparison uses standard pricing. Anthropic was offering a reduced $2 and $10 until September 1, and later removed that offer's expiry (intel).
- Claude Sonnet 5 at max effort scores 53 on the Artificial Analysis Intelligence Index, 6 points above Sonnet 4.6 and level with GPT-5.5 (high), but still behind Opus 4.7 and 4.8.
- At standard $3/$15 pricing it costs $2.29 per index task, about 2x Sonnet 4.6 and about 15% more than Opus 4.8, driven entirely by token use: about 40% more output tokens and about 3x the agentic turns on knowledge-work .
- On AA-Briefcase and GDPval-AA it sits just ahead of Opus 4.8, trailing only Fable 5, while Opus 4.8 stays ahead on heavy reasoning and knowledge benchmarks such as CritPt, where Sonnet 5 scores 17%.
- Anthropic cut Sonnet 5 to $2/$10 until September 1, which AA's results do not use. The model adds an xhigh effort setting, matching Opus 4.8's five levels, and max effort uses about 6x the turns of low effort on GDPval-AA.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.




Checking sign-in…
Loading comments…