Step-Audio-EditX opens its training stack alongside the model
- Source
- x.com
- Date

Step-Audio-EditX's update is here! 🚀 Key updates: - Emotion & Style: Huge gains in fidelity → the results speak for themselves. - More Human: New paralinguistic tags make it feel more alive than ever. - Better Flow: Super-smooth control over speech rates. 🔥 Open Training: SFT, DPO, and GRPO code is out. Your data, your model! ⚡ Max Efficiency: Powered by vLLM for lightning-fast training and inference. 🤖 How to start : GitHub: https://t.co/y3nPcjR0N9 Demo page:https://t.co/zbq4bOk2JB Live Demo:https://t.co/9Jd1tNUZ07 Huggingface: https://t.co/akKNpJq0kl ⭐️Star it, fork it, build with it!
Context
StepFun updated Step-Audio-EditX, a speech-editing model, and released the training code behind it: SFT, DPO and GRPO, three different post-training methods for adjusting a model's behavior after its base training, plus a vLLM-based setup the company says speeds up both training and generation. Releasing that code, rather than only the trained weights, is what lets an outside team retune the model's emotion and pacing control against their own recordings instead of accepting StepFun's shipped voice behavior.
StepFun's own description of the update claims fidelity gains in emotion and style control, finer control over speech rate, and new paralinguistic tags, markers for non-word vocal cues like laughter or breathing. Those improvement claims come directly from StepFun's release notes rather than an independent .
 postStepFun Open-Sources Step Code, a CLI Coding Agent Benchmarked on Terminal-Bench
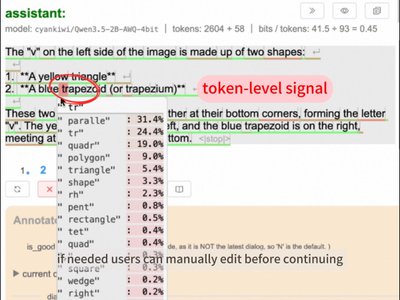 postStepFun Open-Sources onPanda, Its Internal LLM Annotation and Debug Tool
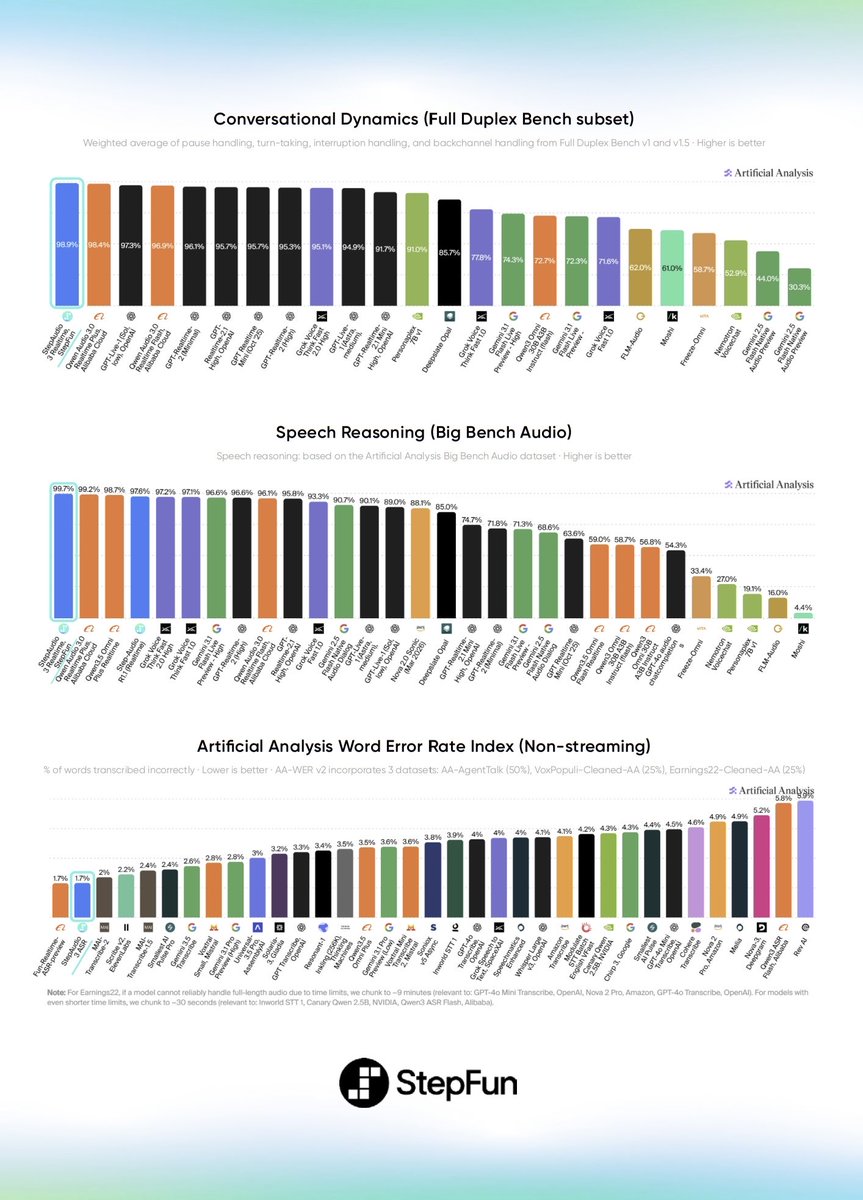 postStepFun debuts StepAudio 3 voice model family, tops real-time benchmarks
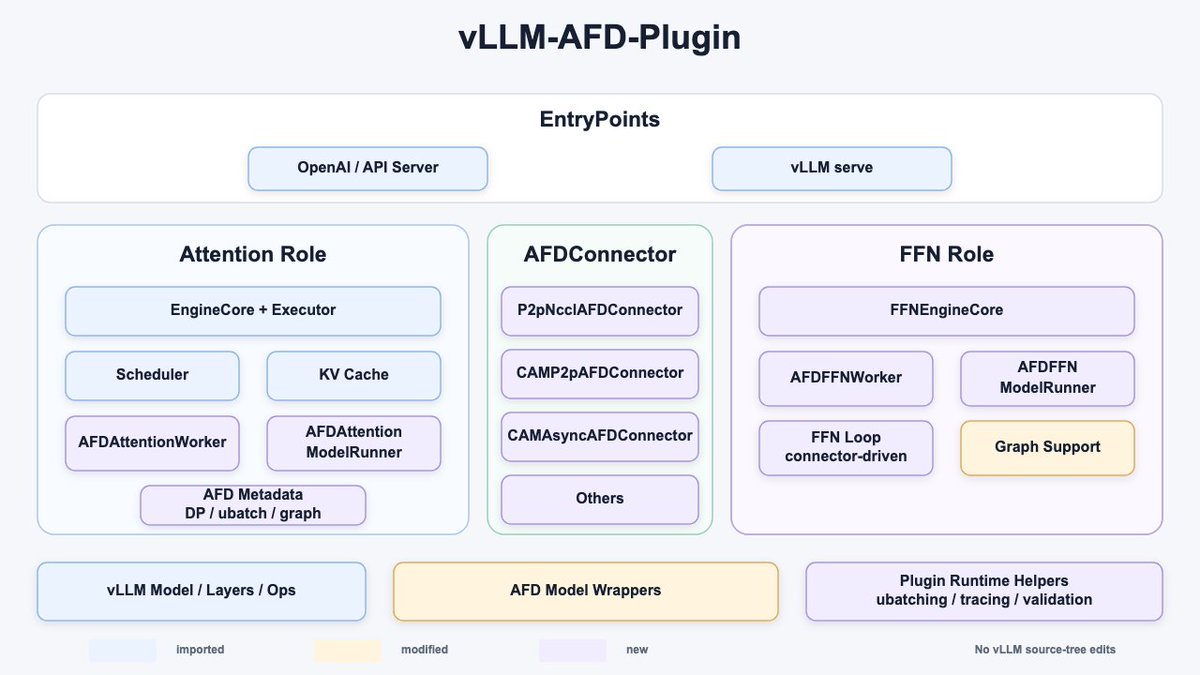 postvLLM gains an experimental Attention-FFN disaggregation plugin for MoE
Checking sign-in…
Loading comments…