Models pass most individual rubric criteria yet rarely deliver a fully acceptable legal work product. All-pass grading shows how far agents are from unsupervised professional output.
Key takeaways · AI-distilled
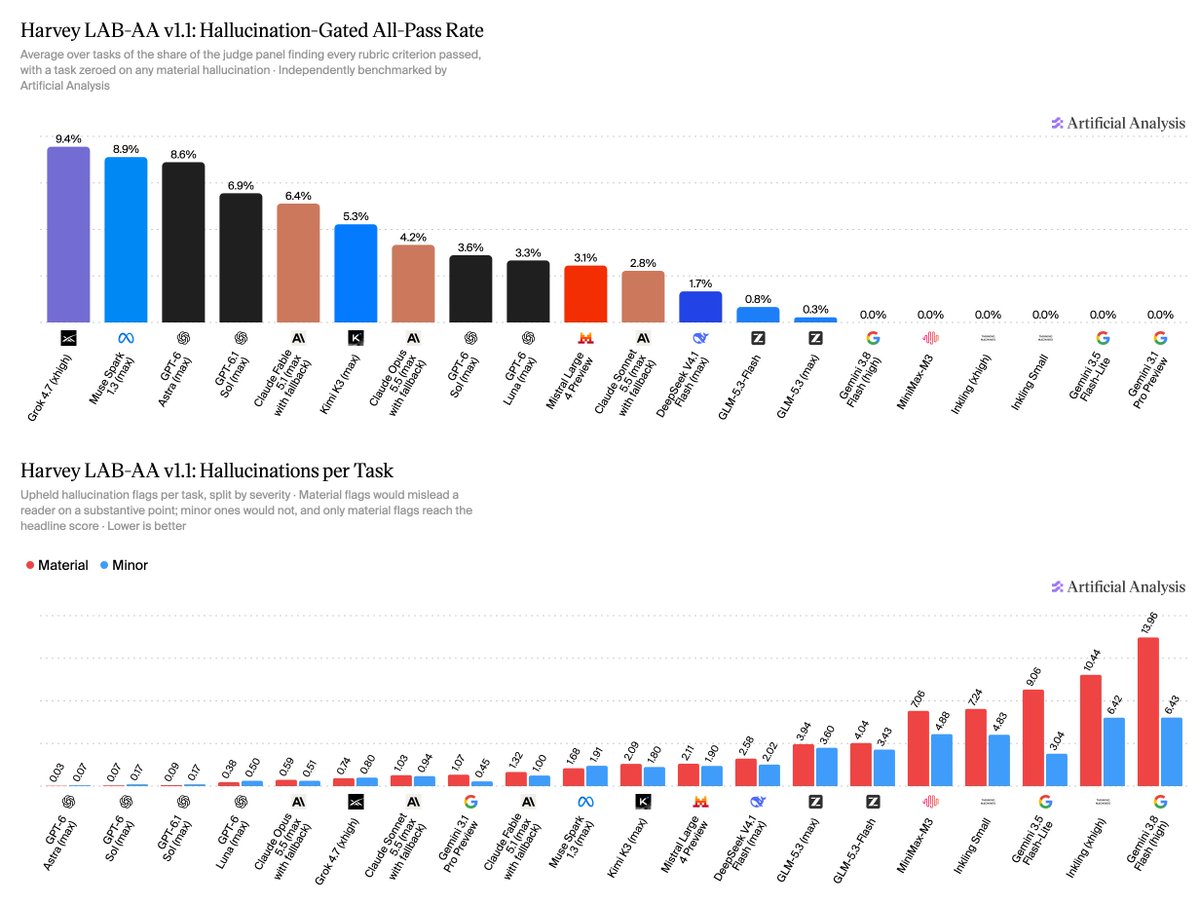
Harvey LAB-AA grades 120 private legal tasks across 24 practice areas on an All-Pass Rate: a task counts only if every binary rubric criterion passes, with no partial credit.
Fable 5 (max; Opus 4.8 fallback on one task) led at launch with 14.2% All-Pass, nearly 2x Opus 4.8 (max) and GLM-5.2 (max) at 7.5%. Most models pass most criteria but fully pass few tasks; the best still leaves ~86% of deliverables incomplete; 13 of 28 passed none.
Costs span ~950x: Fable 5 cost ~$18.9/task. GLM-5.2 matched Opus 4.8's all-pass rate at ~$1.3/task (~15% of Opus's cost). Weighted average decode time was ~5 vs 18.5 minutes; this excludes time to first tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → and overhead.
AA's live leaderboard now reports Harvey LAB-AA v1.1, whose scores are not directly comparable with the launch results in this article.
Terms in this piece · Glossary
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.