Fireworks serves Step 3.7 Flash, a 198B sparse MoE built for inference
- Source
- x.com
- Date

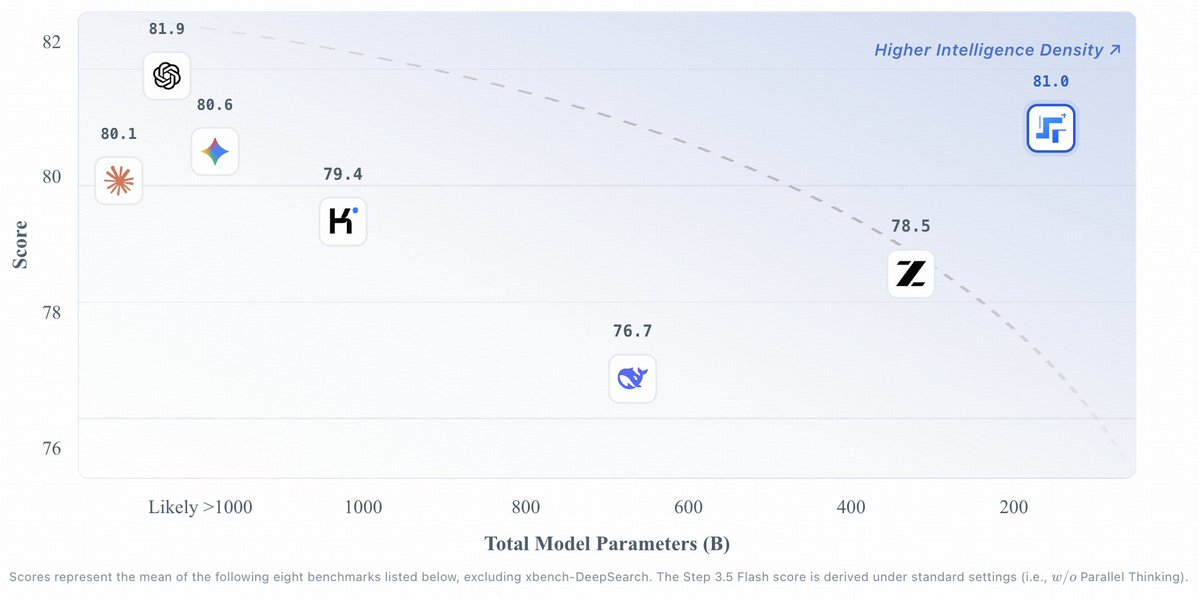
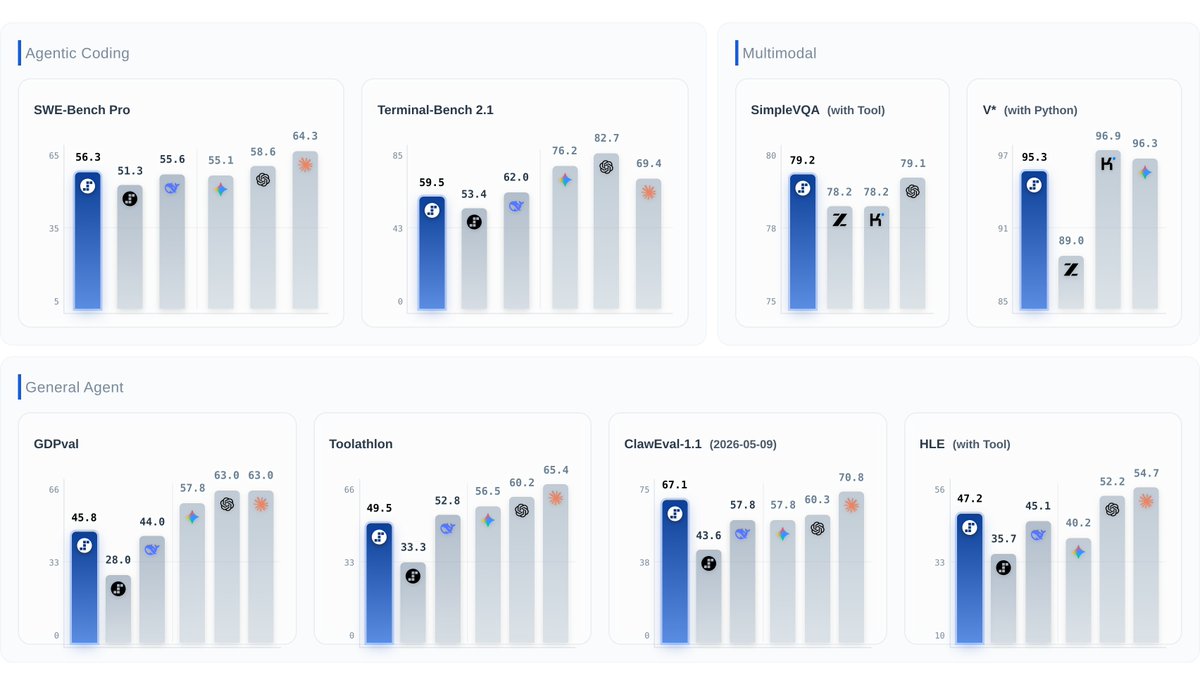
Great to see Step 3.7 Flash live on @FireworksAI_HQ. Designed for inference from day one, Step 3.7 Flash combines a hardware-friendly architecture with MTP-assisted decoding to reach up to 400 tokens/s. Fast, multimodal, and ready to power capable agents in real-world workflows.
Context
Per StepFun's post, Step 3.7 Flash is now live on Fireworks, a model-hosting platform, reaching up to roughly 400 per second through what StepFun describes as a hardware-friendly architecture combined with MTP-assisted decoding. MTP, or multi-token prediction, has the model draft additional candidate tokens ahead of the current position within the same pass, rather than generating strictly one token at a time and running the full model again for each one, cutting the number of passes needed to produce a given amount of text.
This throughput figure is consistent with StepFun's own launch specifications for the model: a 198-billion-parameter sparse model with about 11 billion active parameters per token, which StepFun's original release also reported reaching 400 tokens per second (launch specifications).
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
 postStepFun Open-Sources Step Code, a CLI Coding Agent Benchmarked on Terminal-Bench
 postStepFun Open-Sources onPanda, Its Internal LLM Annotation and Debug Tool
 postStepFun debuts StepAudio 3 voice model family, tops real-time benchmarks
 postvLLM gains an experimental Attention-FFN disaggregation plugin for MoE

Checking sign-in…
Loading comments…