MiniMax open-sources H3 video model ecosystem tooling
- Source
- x.com
- Date

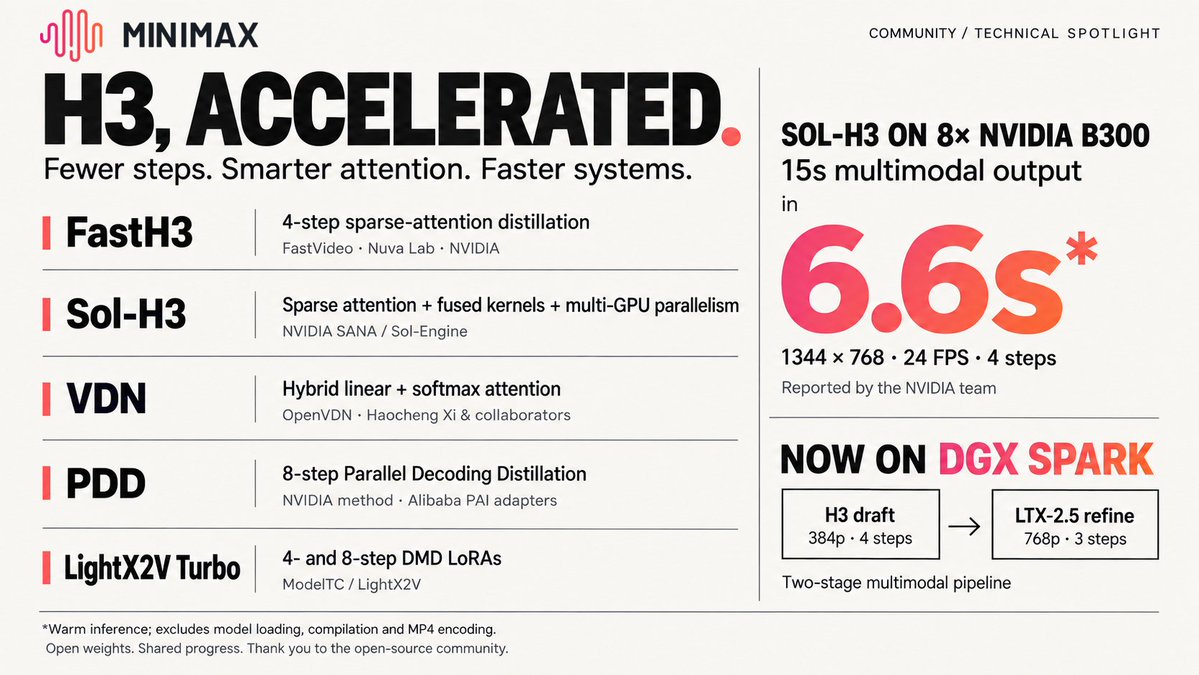
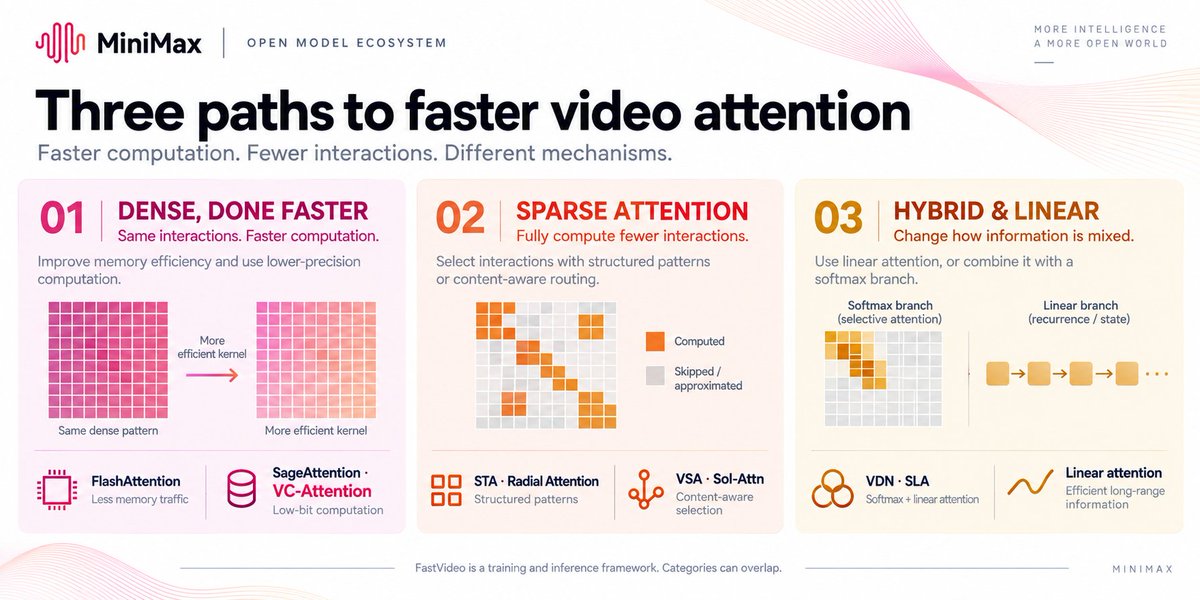
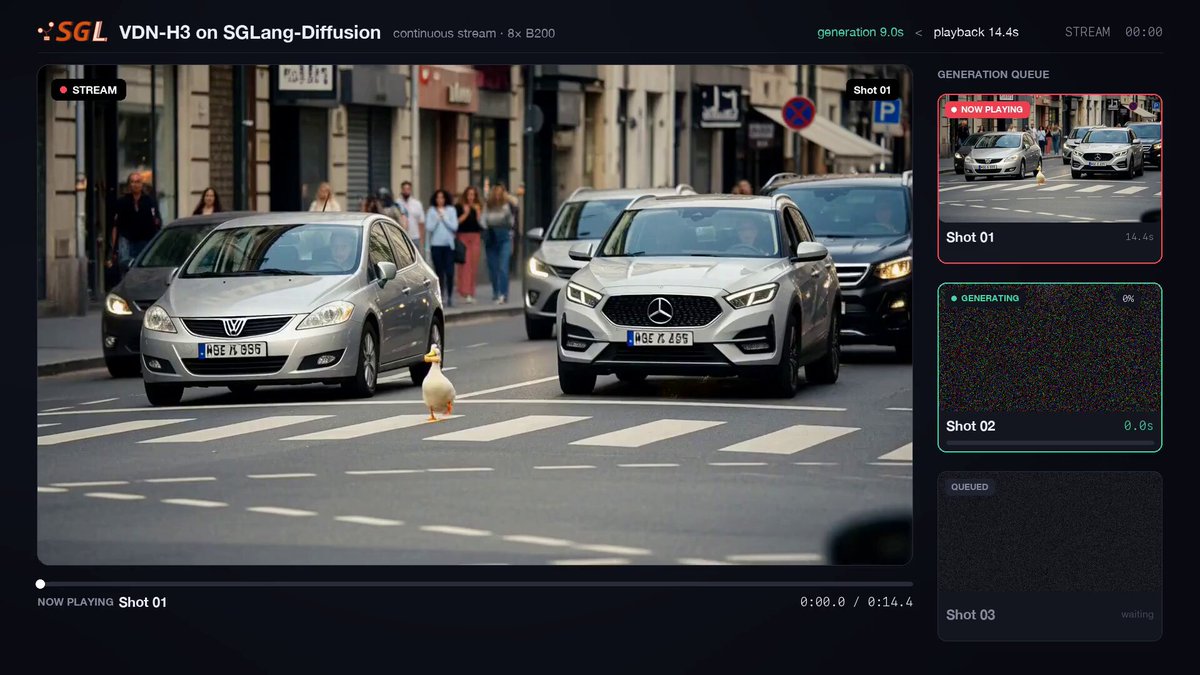
Open weights. Shared progress. MiniMax H3 is moving fast. We built H3 for video generation with native stereo audio and multimodal reference control. The open-source community is making that capability faster, more accessible, and easier to build on. Recent highlights: • FastH3 — FastVideo, Nuva Lab and NVIDIA: 4-step distillation, now running on DGX Spark and Apple Silicon. • Sol-H3 — NVIDIA’s SANA team: 15 seconds of 768p video + audio in 6.6 seconds on 8×B300, in the team’s warm-inference benchmark.* • VDN — Haocheng Xi and the OpenVDN team: rethinking attention for faster H3 inference, with weights, training and inference code released. • PDD — NVIDIA’s distillation method, brought to H3 by Alibaba PAI as 8-step Acc-LoRAs, now supported in ComfyUI. • LightX2V — 4- and 8-step Turbo LoRAs, with workflows for text, image and reference-conditioned video + audio. Behind every release are people training, optimizing, quantizing, testing and sharing. Special thanks to: @haoailab @nuvalab @NVIDIAAI @xieenze_jr @HaochengXiUCB @ArashVahdat @julberner @LightX2V @ComfyUI And to the individual contributors pushing the work forward: @haozhangml @cxlcl1 @lawrence_cjs @yitongli165665…

Context
MiniMax open-sourced its H3 video-generation model, which produces video with matching stereo audio and lets a reference image or clip control a subject, motion or voice across a generated shot. Because the weights are public, outside teams can build their own tools on top of it instead of waiting for MiniMax to ship every optimization itself.
MiniMax's roundup credits several such projects: FastH3, built with FastVideo, Nuva Lab and NVIDIA, which distills H3 down to four generation steps and runs on hardware like DGX Spark and Apple Silicon; Sol-H3, NVIDIA's SANA team's fast- build; VDN, an independently released rework of H3's with its own weights and training code; PDD, NVIDIA's method adapted into ComfyUI-compatible LoRAs by Alibaba PAI; and LightX2V's Turbo LoRAs for faster text, image and reference-conditioned generation.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
Checking sign-in…
Loading comments…