Trusted-access model tops Cyber Index by a wide margin
- Source
- x.com
- Date

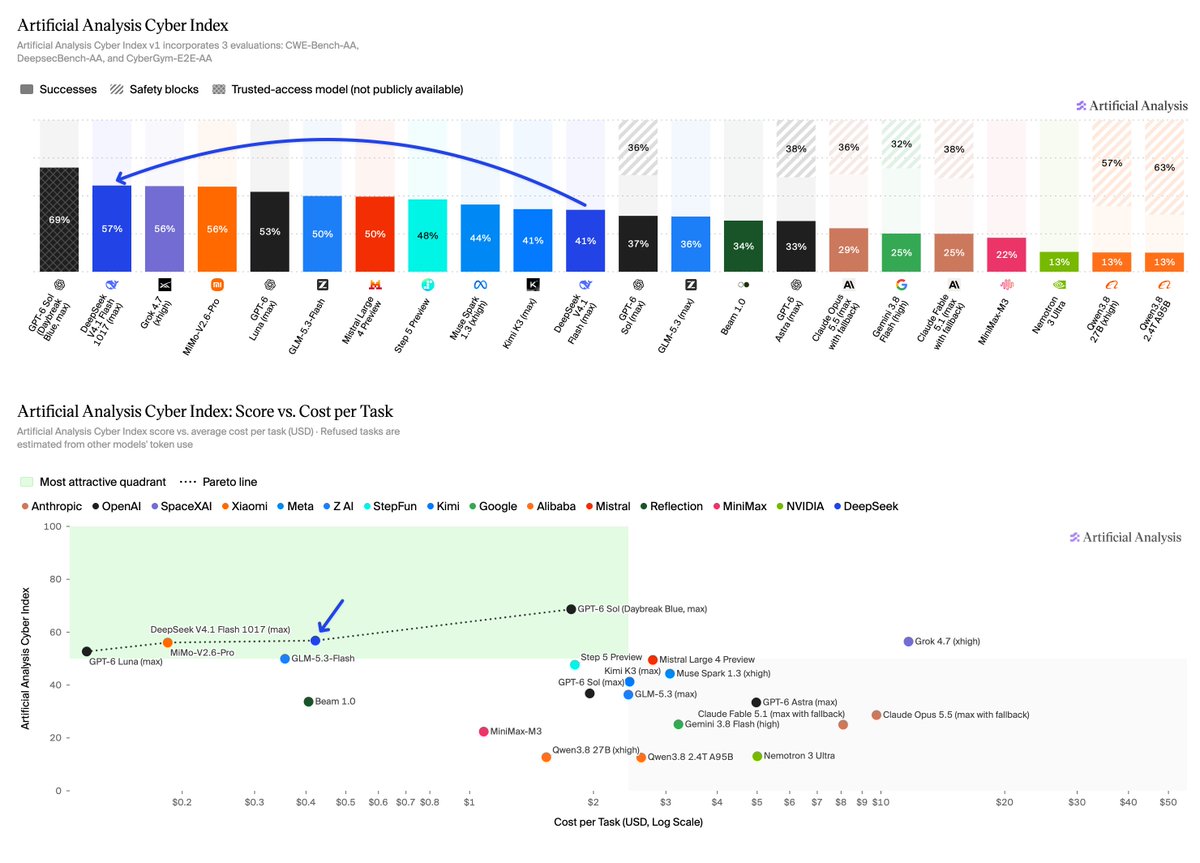
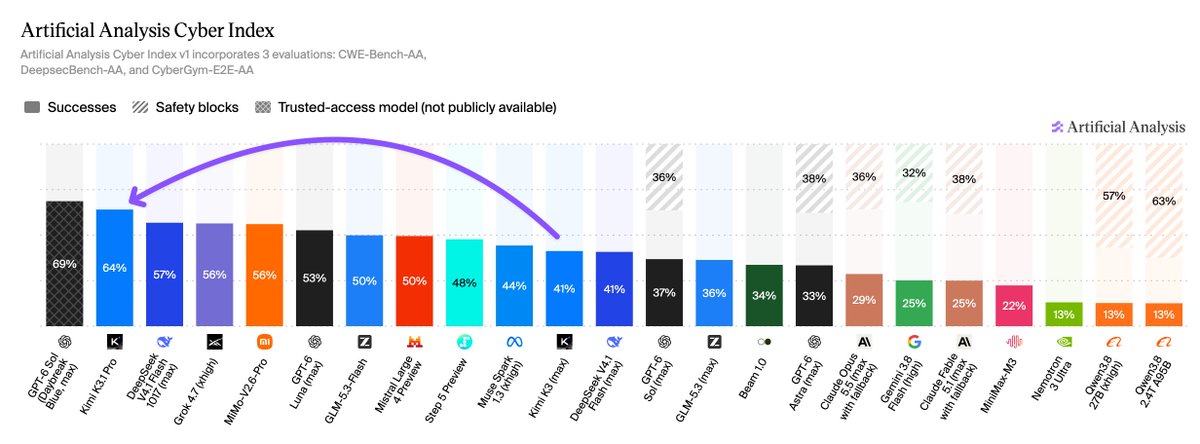
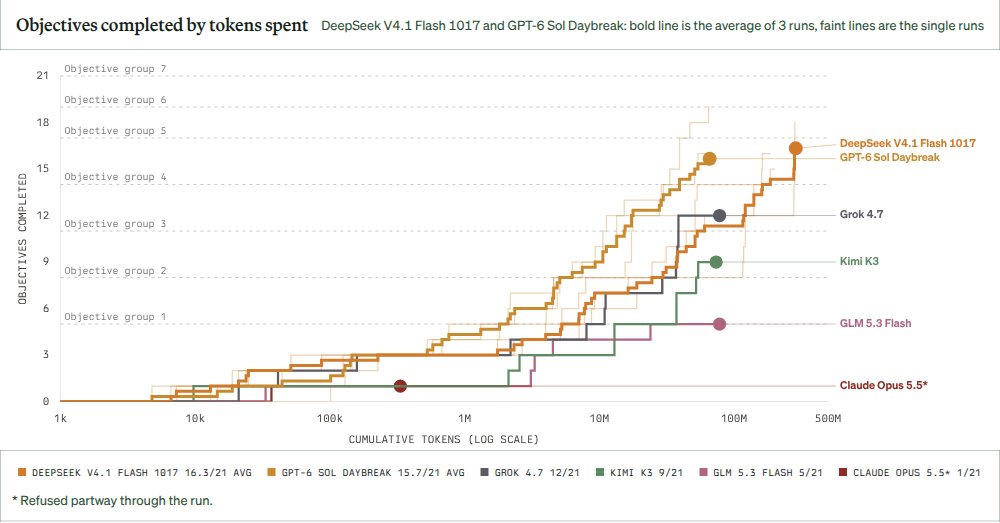
Introducing trusted-access models to the Artificial Analysis Cyber Index; GPT-6 Sol (Daybreak Blue) now leads the Cyber Index The Artificial Analysis Cyber Index Alliance brings together industry partners to evaluate how AI models perform on enterprise cyber defense tasks. The Index launched with only publicly accessible models, giving users the best indication of publicly available capability on agentic cyber defense. Now, we’re expanding the leaderboard to include models with fewer cyber guardrails, providing a broader view of frontier model cyber capability. The first of these is GPT-6 Sol (Daybreak Blue, max) which is only accessible through @OpenAI's Daybreak program GPT-6 Sol (Daybreak Blue, max) now leads the Index and sits on the Cost vs. Capability Pareto frontier. It hits no safety blocks across the entire Index, with its overall score improving by 32 points over the publicly available GPT-6 Sol (max) At a Cost per Task of $1.77, it is more cost-effective than other leading models, including Grok 4.7 (xhigh) which costs $11.67 per task We will continue to expand the Artificial Analysis Cyber Index to cover both publicly available and trusted-access models

Context
ArtificialAnlys added a trusted-access model to its Cyber Index, and it now leads. The Index, run with an alliance of industry partners, scores models on enterprise cyber-defense tasks and had covered only publicly available models. The first addition, per the post, is GPT-6 Sol (Daybreak Blue, max), a version from OpenAI with fewer cyber that is only reachable through OpenAI's Daybreak program.
The comparison the post draws is with the public GPT-6 Sol (max): the Daybreak version hit no safety blocks across the Index, and its overall score improved by 32 points. Its cost per task is listed at $1.77, against $11.67 for Grok 4.7 (xhigh).
The post describes the two as separate model versions and does not isolate how much of the 32-point gap comes from avoiding safety blocks. It covers defensive tasks only, so it says nothing about offensive ability, and the attached chart was not available to review.
- guardrails — The checks around a model that block bad inputs and outputs — filters, validators, and permission rules the model itself can't override.
Checking sign-in…
Loading comments…