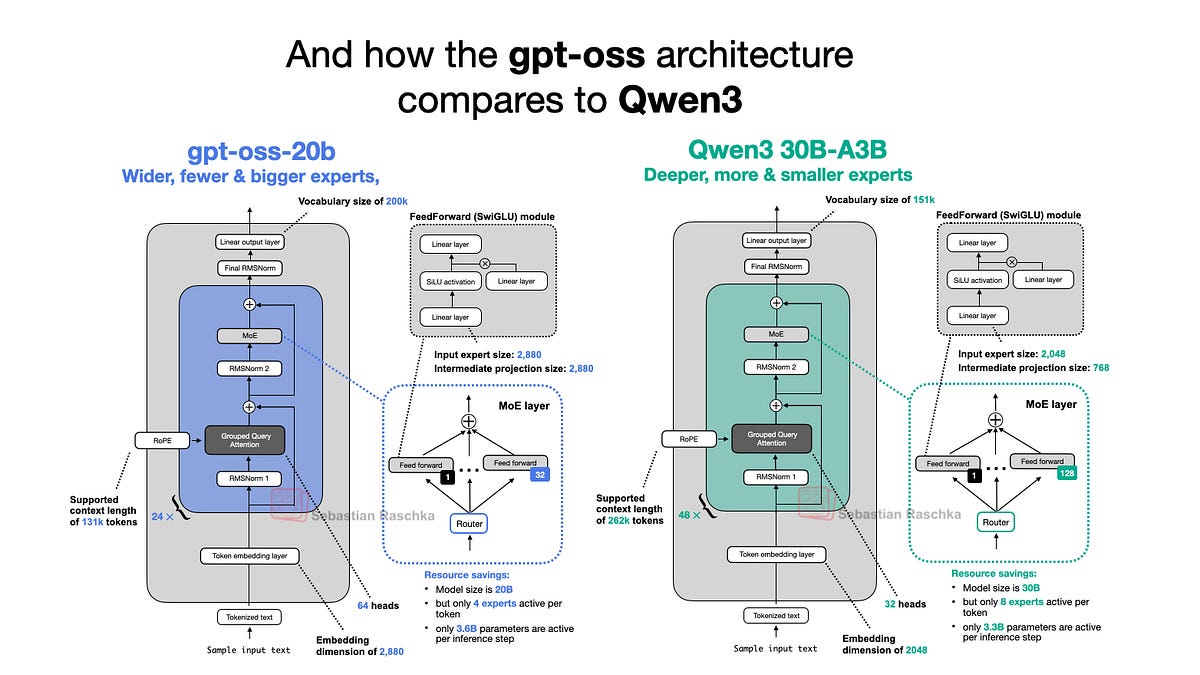
gpt-oss-120b runs on a single H100 and gpt-oss-20b on a laptop-class GPU while scoring competitively. It is the strongest US open-weights option for local deployment at release.
Key takeaways · AI-distilled
Artificial Analysis reported August 2025 native MXFP4 sizes of 60.8 GB for gpt-oss-120b and 12.8 GB for gpt-oss-20b. Weight precision and storage size materially changed which hardware could host the models.
The August 2025 gpt-oss analysis distinguished total from active parameters. The larger model had 117 billion total parameters but activated 5.1 billion per tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →, so total parameter count alone did not describe inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → work.
In Artificial Analysis' August 2025 tests, gpt-oss-120b scored below DeepSeek R1 0528 and Qwen3 235B 2507 but had much smaller memory requirements. The result supported a deployment tradeoff rather than universal model superiority.
Terms in this piece · Glossary
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.