Vals AI's MysteryMechanism Benchmark Tests Scientific Rediscovery
- Source
- x.com
- Date

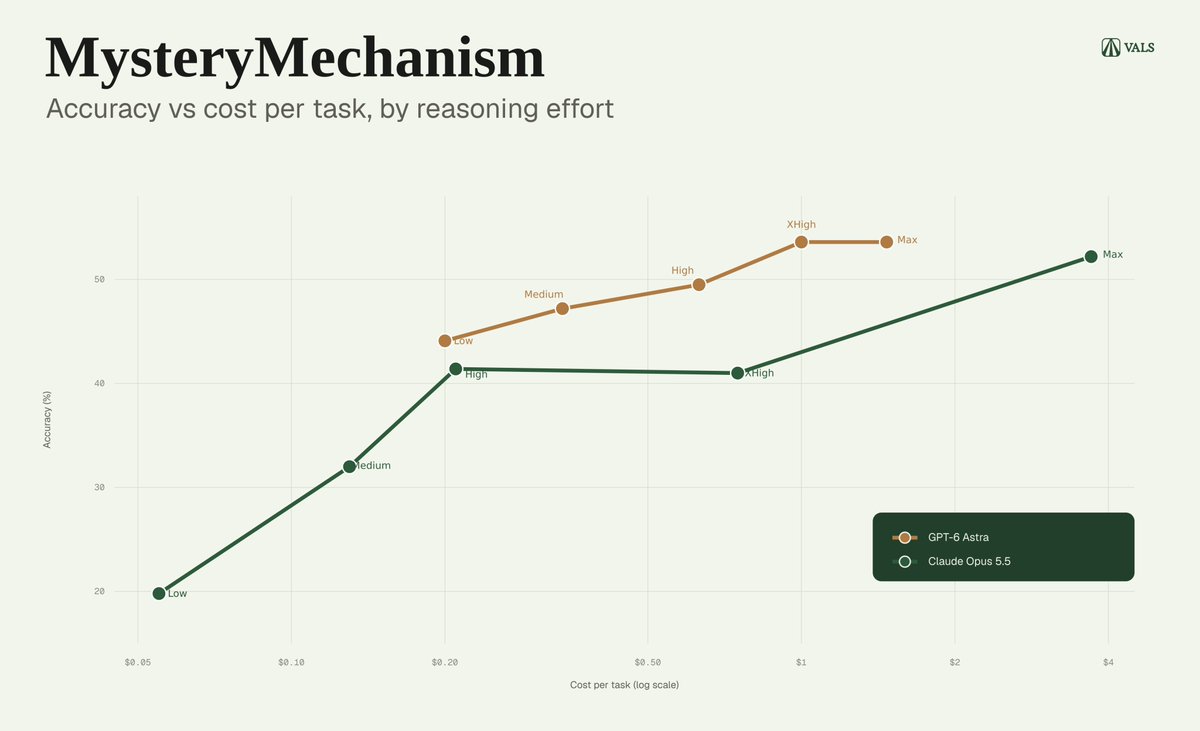
Scientific discovery is the next frontier for AI systems. However, new scientific results are difficult to verify, and therefore hard to measure. Today we're releasing MysteryMechanism, a benchmark that tests whether agents can rediscover sealed mathematical mechanisms through bounded experiments. It cuts sharply across the frontier, with Astra landing roughly 20pp above Sol.

Context
Vals AI released MysteryMechanism, a meant to test scientific discovery rather than recall of already-published results. Vals AI's post explains the difficulty with grading scientific discovery directly: new results are hard to verify, which makes them hard to benchmark. MysteryMechanism works around that by sealing a mathematical mechanism the model must rediscover through its own bounded experiments, rather than asking a question with a known answer, so what gets scored is the model's process of forming and testing a hypothesis. Vals AI reports the benchmark separates frontier models sharply, with GPT-6 Astra scoring roughly 20 percentage points above GPT-5.6 Sol. The chart accompanying the post, which likely shows a fuller model ranking, was not reviewed here, so how other tested models compare beyond that one reported gap is not established.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.

Checking sign-in…
Loading comments…