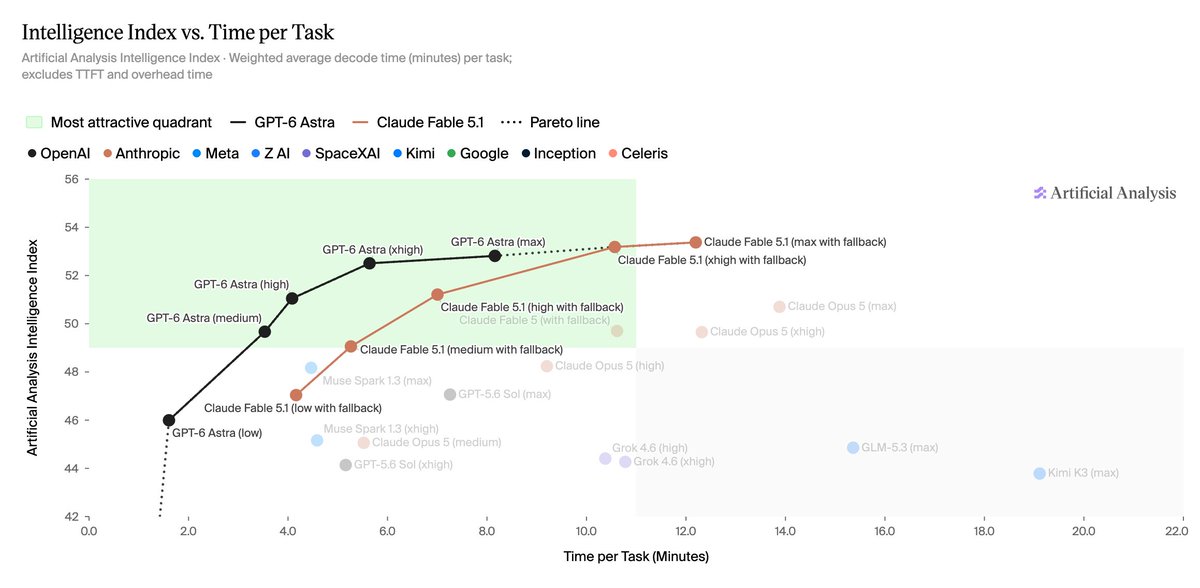
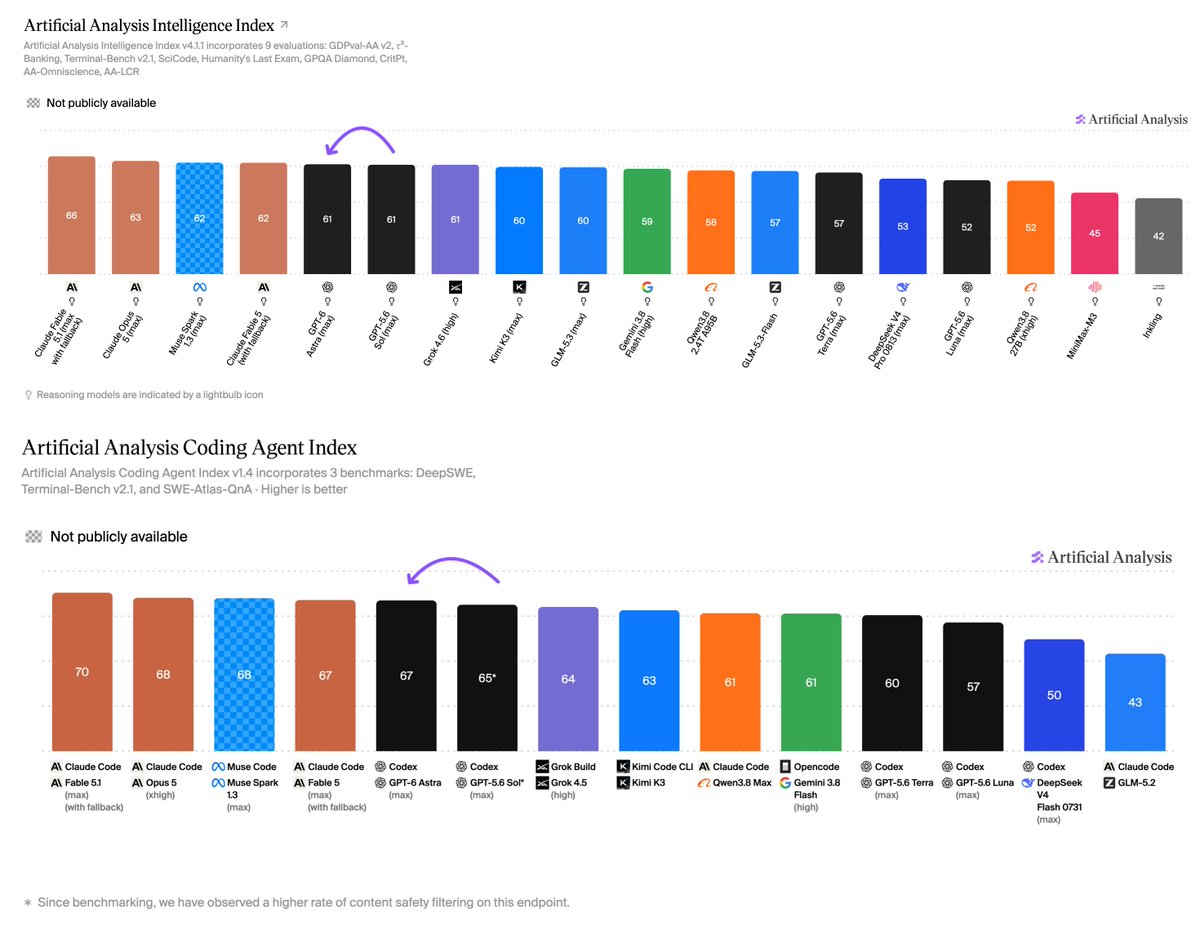
When does more reasoning stop being useful and start becoming overhead?
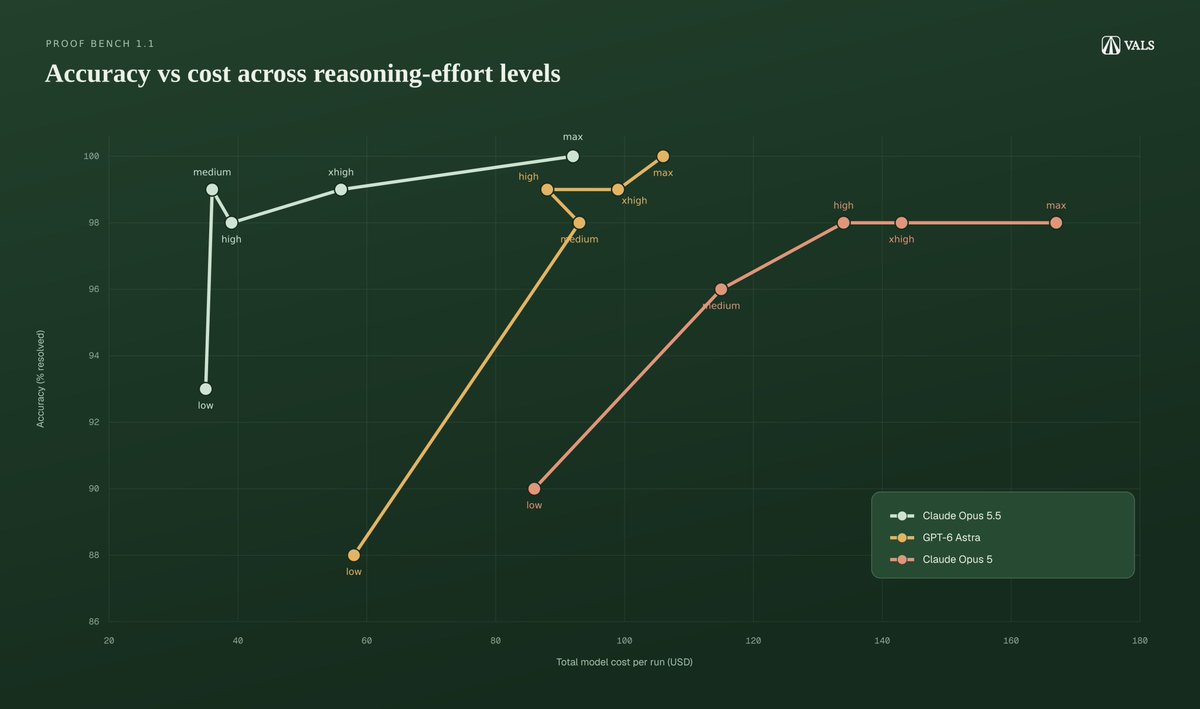
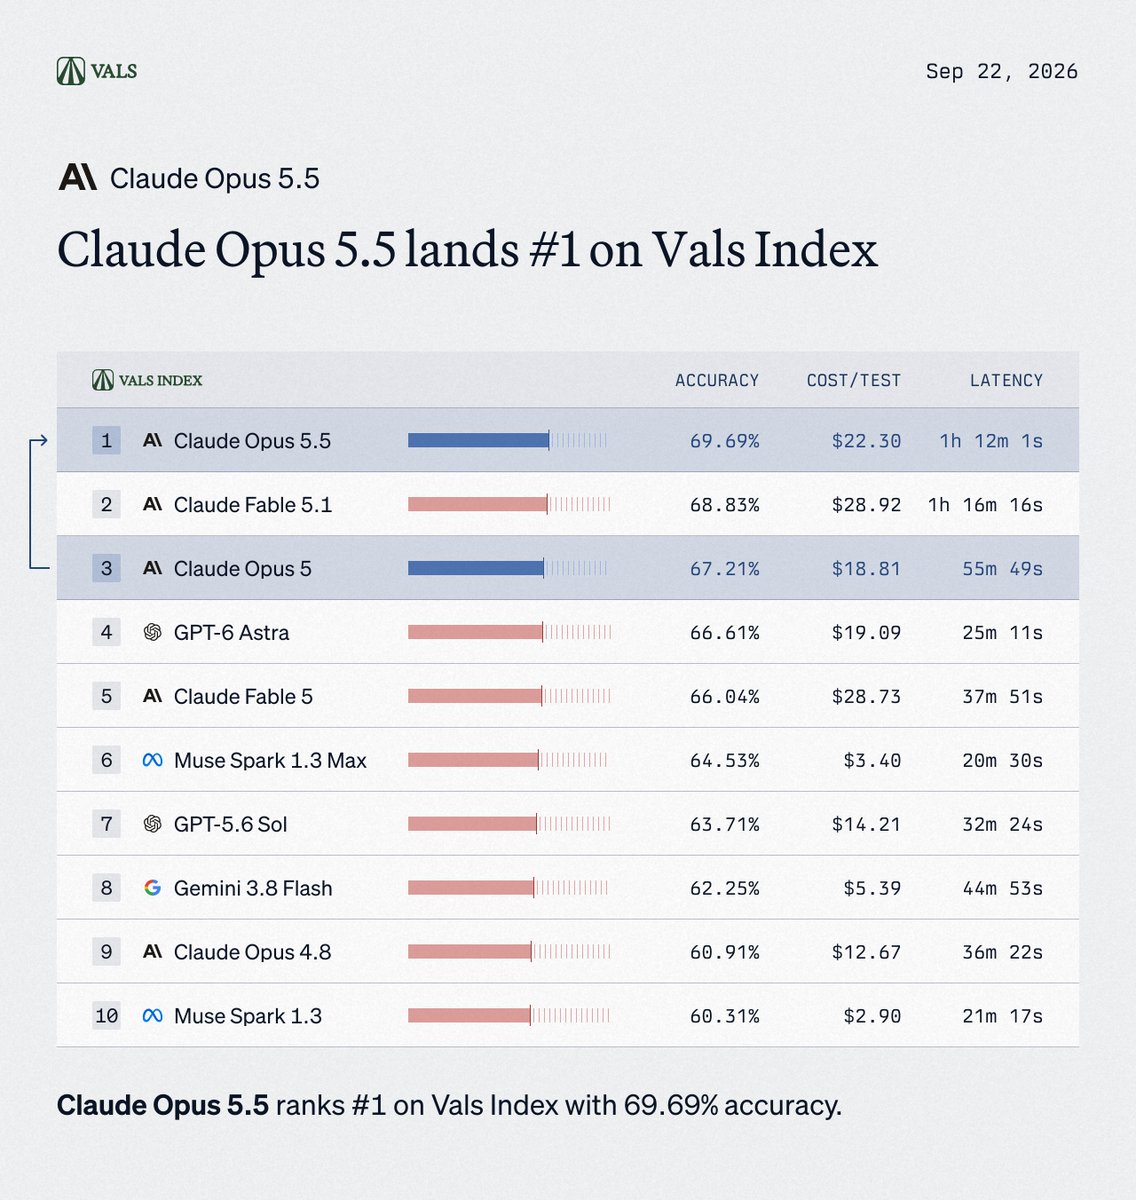
We ran Open AI and Anthropic’s best models: GPT-6 Astra and Claude Opus 5.5 at every reasoning level on our new benchmark, MysteryMechanism.
Thinking longer delivers accuracy gains with the same model at as much as 20x the cost. Inspecting traces, the models use their effort level in very different ways.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Why it matters
Shows that raising reasoning effort on the same model can cost up to 20x more for its accuracy gain, and that GPT-6 Astra and Opus 5.5 use effort differently. Helps you choose reasoning levels by cost, not by default.