Benchmarking AFM-4.5B inference across Xeon, Graviton and Qualcomm CPUs
- Source
- x.com
- Date

As generative AI becomes increasingly central to business applications, the cost, complexity, and privacy concerns associated with language models are becoming significant. At @arcee_ai, we’ve been asking a critical question: Can CPUs actually handle the demands of language models? The short answer: Yes—with the right optimizations. In this piece by @AndrewWalko , @bartowski1182, and @julsimon , we explore hardware and software improvements that make CPU inference viable. Using our latest foundation model, AFM-4.5B, we conduct detailed benchmarks on @intel Xeon, @awscloud Graviton, and @Qualcomm Z1E-80-100 CPUs to identify the most suitable configurations for enterprise AI use cases, whether in the cloud or at the edge. Blog post: https://t.co/vxs4YC4sf9 -- Follow @arcee_ai for the latest news on small language models.

Context
Arcee tested its 4.5-billion-parameter AFM-4.5B model on three CPU families instead of the GPUs language models normally run on: Intel's Xeon Sapphire Rapids, AWS's Graviton4, and Qualcomm's X1E-80-100, using hardware instruction sets such as AVX-512, VNNI, and AMX along with model weights.
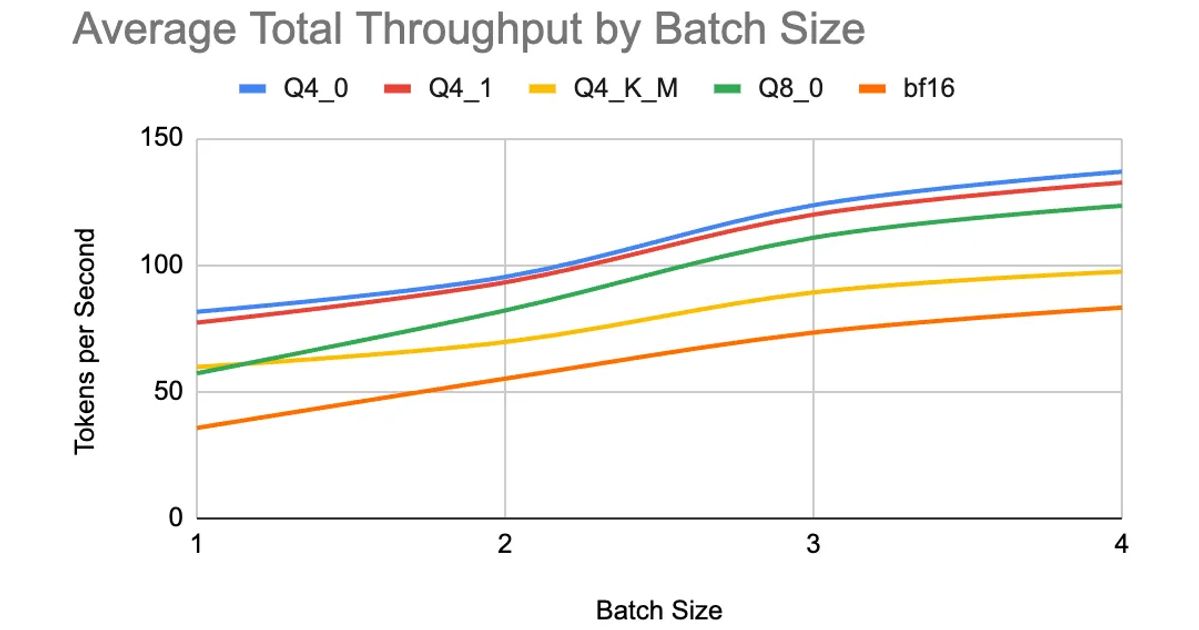
On Xeon Sapphire Rapids with 32 threads, Arcee's blog post reports peak throughput of about 137 tokens per second using 4-bit quantization at a batch size of 4. On Graviton4 with 32 virtual CPUs, peak throughput exceeded 280 tokens per second at the same quantization and batch size, though the unquantized bf16 version ran at only about 2 tokens per second there, due to a lack of matching hardware acceleration. On the Qualcomm chip, time to the first generated token ranged from under a second for short prompts to nearly 11 seconds for a 1,024-token prompt.
Arcee's stated conclusion is that CPU is production-viable for privacy-conscious, latency-tolerant deployments, but only with short lengths, modest batch sizes capped around 4, and quantized models; it says GPU infrastructure remains ahead for high-throughput scenarios.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…