AI Model Co-Design: Hardware-Friendly LLM Design
- Source
- developer.nvidia.com
- Author
- Elizabeth Goodman
- Date
Context
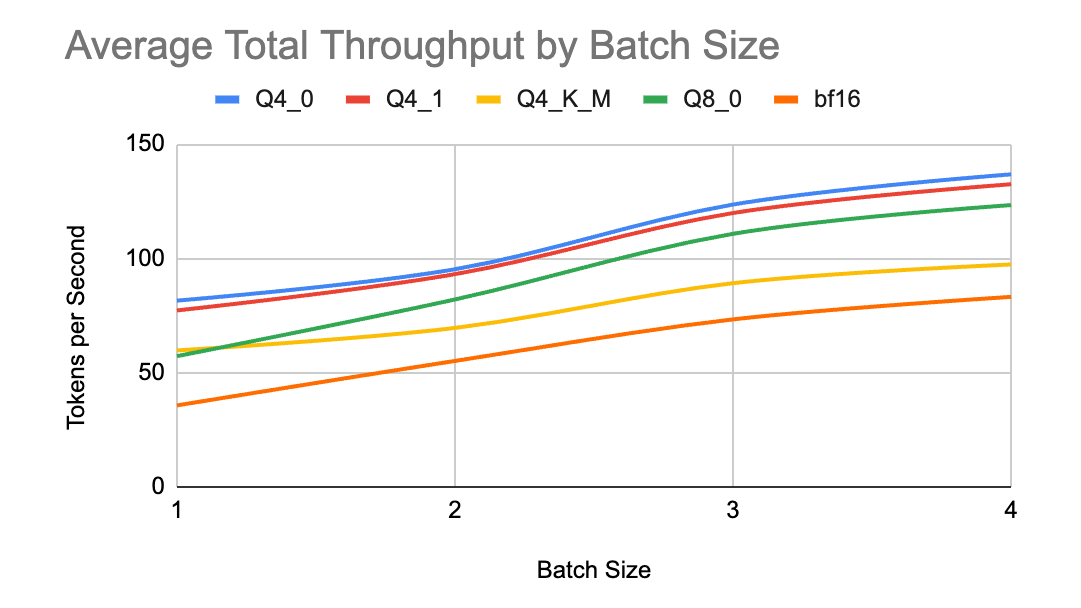
A model can generate plenty of text across a data center while still feeling slow to each person using it. NVIDIA's hardware-design guide separates aggregate throughput from responsiveness, which depends on waiting for the first output and subsequent text. A useful design must meet its response-time target while preserving accuracy. The guide explains this tradeoff.
The model's internal dimensions help determine that balance. GPU computation involves moving data as well as performing arithmetic; poorly chosen matrix dimensions can leave the processor waiting on memory. Designing those dimensions for the hardware can improve utilization. The guide therefore treats deployment requirements as inputs to model design, rather than something to address only after training. Its linear-layer analysis provides the mechanism.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
 articleHow NVIDIA OpenShell Reference Architecture Secures and Governs AI Agent Workloads at Scale
 articleCode, Test, and Deploy on One Machine with NVIDIA RTX Spark
 articleHow to Rewrite Apache Spark UDFs for GPU Acceleration with AI Agents
 articleLower the Cost of Building and Running Visual AI Agents with NVIDIA VSS Blueprint 3.3
Checking sign-in…
Loading comments…