← All IntelIntel / article
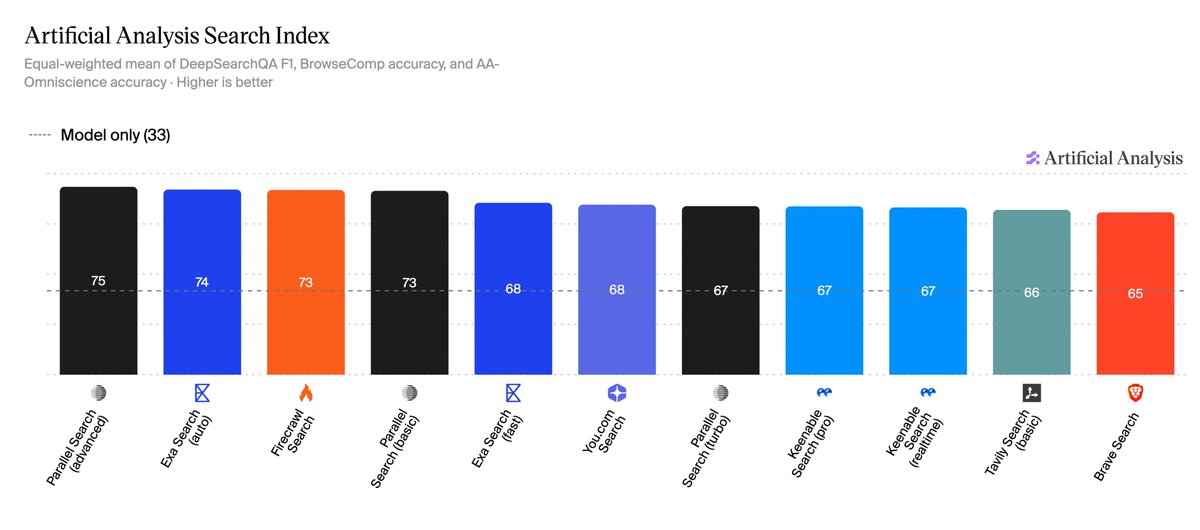
➤ Leaderboard: ➤ Methodology: ➤ Stirrup, our open-source agent harness: Search A
- Source
- artificialanalysis.ai
- Author
- ArtificialAnlys
- Date
Context
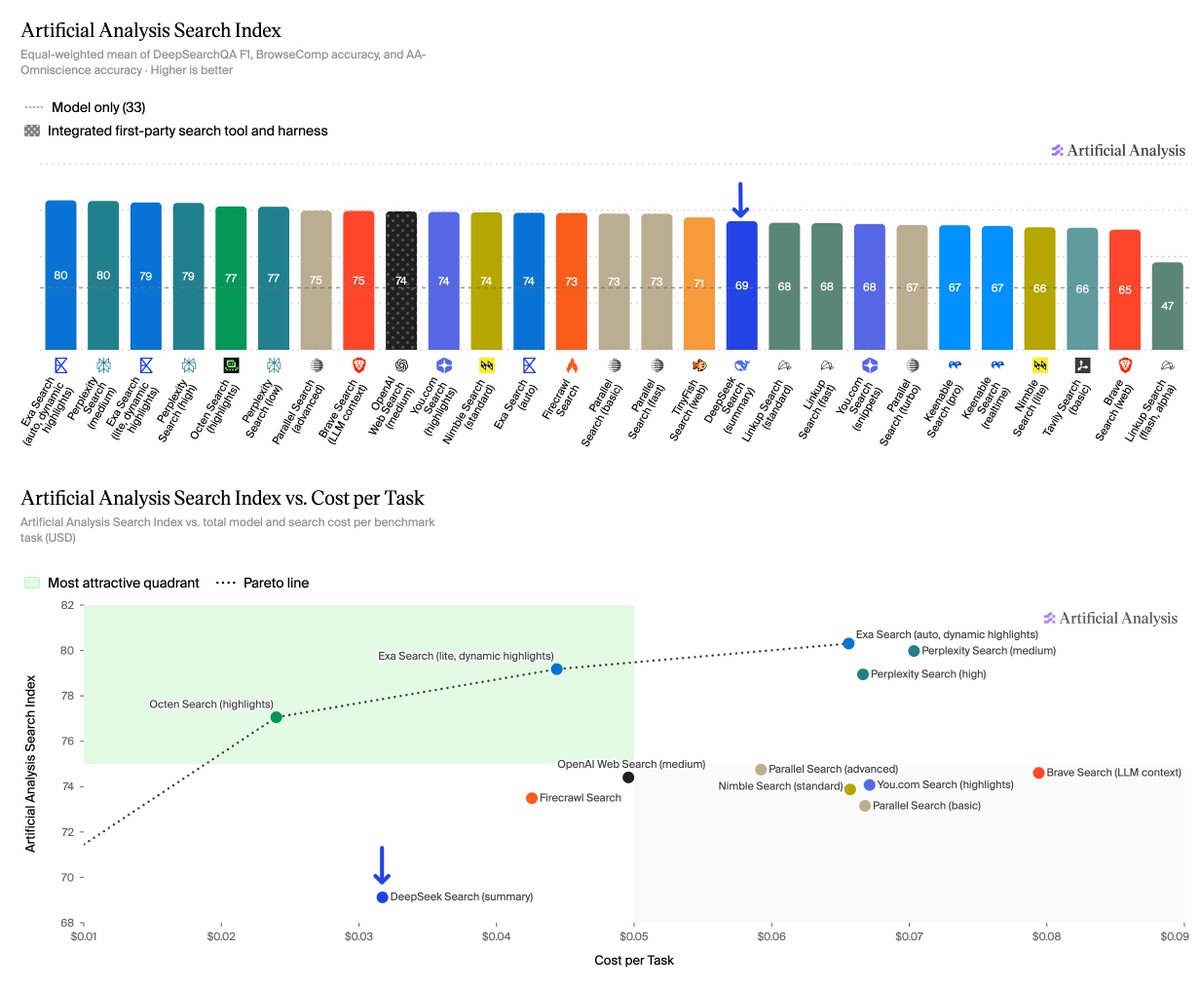
Artificial Analysis evaluates search services by measuring the answers a fixed AI model produces with their help. The method keeps the answer model, GPT-5.6 Luna (medium), and the constant while changing the search provider, then averages results from three benchmarks: DeepSearchQA, AA-Omniscience and BrowseComp. The score therefore describes performance within this setup. Benchmark methodology
Price per search call is only part of the cost of getting an answer. The leaderboard reports search cost and model cost in separate columns, each as the average cost of 1,000 tasks, so a reader can see both parts of the expense of reaching answers rather than only the price of individual searches.
Terms in this piece · Glossary
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Read the source artificialanalysis.ai
More from ArtificialAnlys
Recommended reads
Comments
Checking sign-in…
Loading comments…