PrismML ships Ternary Bonsai 2 small models for on-device agents
- Source
- prismml.com
- Author
- PrismML
- Date
Context
PrismML's new Ternary Bonsai 2 models are compressed versions of Qwen's Qwen3.5 2B, 4B and 9B in which every language-model weight is stored as one of three values, −1, 0 or +1 (PrismML). That works out to about 1.7 bits per weight instead of the usual 16, applied across the whole rather than leaving some layers at high precision, according to PrismML's documentation (docs). The result is files of 0.43GB, 0.95GB and 2GB, which PrismML says is more than nine times smaller than the originals. Size is not the only gain: generating text is limited mainly by how fast weights can be read from memory, so smaller weights also mean faster output, and PrismML reports up to five times the throughput and three times the energy efficiency of the full-precision models on an RTX 4090 and an M5 Pro, and up to 34 tokens per second for the 9B on an iPhone 18 Pro Max. The three join Bonsai 2 27B, released last month with the same approach.
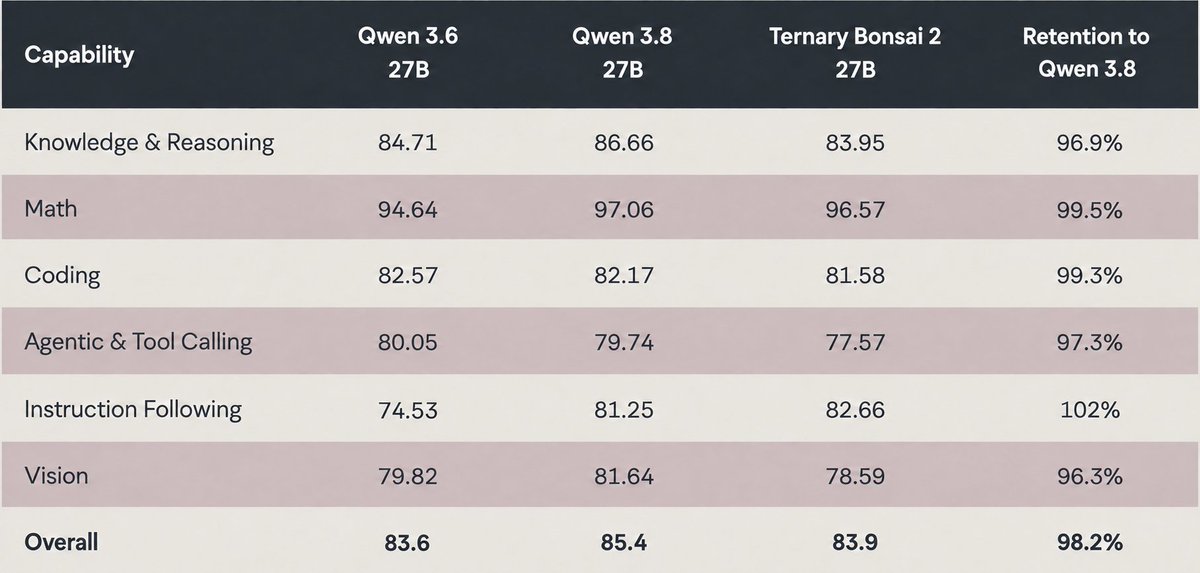
PrismML's own comparison against the uncompressed Qwen3.5 models, across 19 benchmarks, shows where the compression costs little and where it costs more. On math, coding and instruction following the 9B stays essentially level with its original, and the 2B even scores higher on some instruction-following tests, such as 48.00 versus 34.33 on IFBench; PrismML says this release focused on following instructions and avoiding unnecessary output. Knowledge-heavy and agentic tasks lose more: on GPQA Diamond the 9B scores 69.9 against 82.53 for full-precision Qwen3.5 9B, and on the Tau2Bench benchmark the 4B keeps 75.8% of its original score. In the knowledge-and-reasoning category the loss grows as the models shrink, from 93.0% retained at 9B to 82.9% at 2B. These are PrismML's figures; the whitepaper describing its compression and evaluation methods could not be read for this summary, and the demonstration videos were not transcribed.
Running the models takes more than a file that matches the right format. The weights are stored in a rotated form, so the software running them must apply a matching transform to its intermediate values, and PrismML's docs warn that an older llama.cpp build will load the file and produce gibberish rather than refusing it (docs). Upstream llama.cpp now runs one of the three file layouts PrismML publishes, the mlx-vlm library loads the Apple versions natively, and the weights are released under Apache 2.0.
- PrismML's Ternary Bonsai 2 2B, 4B and 9B, built on Qwen3.5, store each weight as -1, 0 or +1, giving footprints of 0.43GB, 0.95GB and 2GB, which PrismML says is over 9x smaller than full precision.
- Retention is uneven by in PrismML's own tables: the 9B keeps about 100% on instruction following and coding but 84.7% on GPQA Diamond and 85.7% on Tau2Bench, and the 2B keeps only 67.7% on GPQA Diamond.
- PrismML reports up to 5x throughput and 3x energy efficiency versus full-precision counterparts on RTX 4090 and M5 Pro, with the 9B reaching up to 34 tokens/s on an iPhone 18 Pro Max and the 2B up to 120.
- PrismML tuned the release against small-model failure modes, repetitive loops, weak instruction following, mobile tool calls and verbosity, and says the 9B uses about 40% fewer tokens on everyday instruction and math tasks.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- tool use — A model's ability to call external functions — run code, search the web, edit files — instead of only generating text.
- agent skill — A reusable instruction file that teaches an agent how to do one job well — the procedure, the tools, and what counts as done.
Checking sign-in…
Loading comments…