Sakana retrains Fugu's conductor on open Gemma 4
- Source
- sakana.ai
- Author
- Sakana AI
- Date
Context
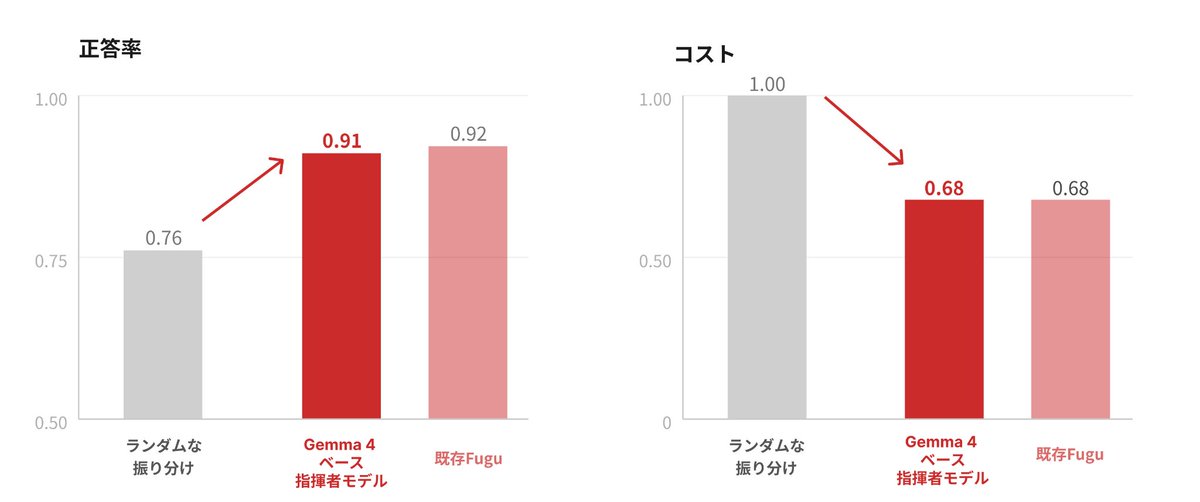
Sakana AI has shown that the small model steering its Fugu product can be rebuilt on a different foundation with comparable results on the company's own tests. Fugu puts several AI models behind one API, and Sakana's report (in Japanese) describes it in two layers: a pool of models, including frontier models with hundreds of billions of parameters, that does the actual work, and a small conductor model trained to decide which pool model handles what and how they cooperate. The pool was designed from the start to be swappable. Until now, the conductor had been trained on a Qwen base model.
Because the heavy knowledge and reasoning sit in the pool, Sakana says the conductor can stay small, which makes it practical to retrain on a new base model. The approach comes from Sakana's ICLR 2026 research, including the Conductor paper, which trained a coordinating model with reinforcement learning to direct a pool of worker models. For this test, Sakana applied the same training method to Gemma 4 E2B, an open model under the Apache 2.0 license, and evaluated it on an in-house set of knowledge questions, code repair, code generation and graduate-level science questions that were kept out of training and used once at test time. Sakana reports that the Gemma-based conductor performed comparably to the existing one and delivered an equivalent cost reduction relative to random routing, meaning requests sent to pool models chosen at random. The results appear only in a chart, and the question set is Sakana's own, so this is a company-reported parity result, not an independent .
The reason for the test is sovereignty. Some customers want to choose pool models by cost, by where the provider is based or by where the system runs, and Sakana already lets the pool change, including adding NVIDIA's Nemotron models through a partnership. The conductor was the one part with no alternative base. Sakana says it will next train conductors on its own models, aiming to offer one built on a model pretrained in Japan for customers who need it, while still giving them access to the strongest overseas models through the pool.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…