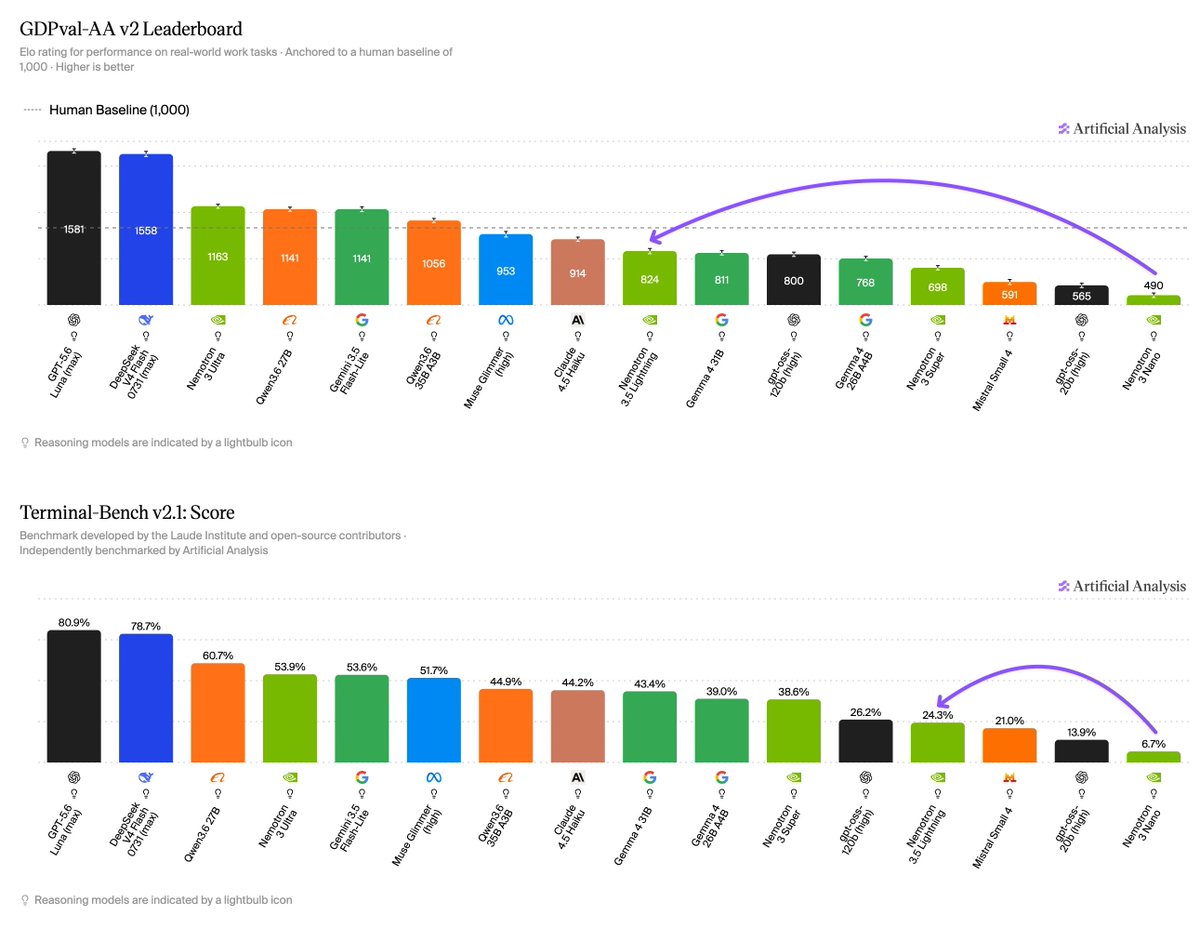
Nemotron 3.5 Lightning matches gpt-oss-120b on the index with about a quarter of the parameters and ~670 tokens/s, under a permissive license, making it a cheap option for high-volume agents.
Key takeaways · AI-distilled
Artificial Analysis reports a nine-point Intelligence Index gain over Nemotron 3 Nano with similar output-tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → use per task. Lightning retains the predecessor’s small hybrid Mamba-transformerThe neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.Full definition → design.
Nemotron 3.5 Lightning's speed of nearly 670 output tokens per second came from pre-release DeepInfra testing with final NVFP4 weights. That setup also underpins the estimated half-minute time per task.
The article reports minimal Intelligence Index degradation from NVFP4 versus BF16 weights, but Lightning still trails more capable small models. Its appeal is the measured efficiency tradeoff, not a lead in overall intelligence.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.