Open models take the top spend share on shell execution and tool dispatch
- Source
- x.com
- Date

Open models have topped 2 new task leaderboards by real spend share: • Shell execution: DeepSeek V4 Pro • Tool dispatch: Kimi K3

Track them all here: https://t.co/S7RXjvQHgQ
Context
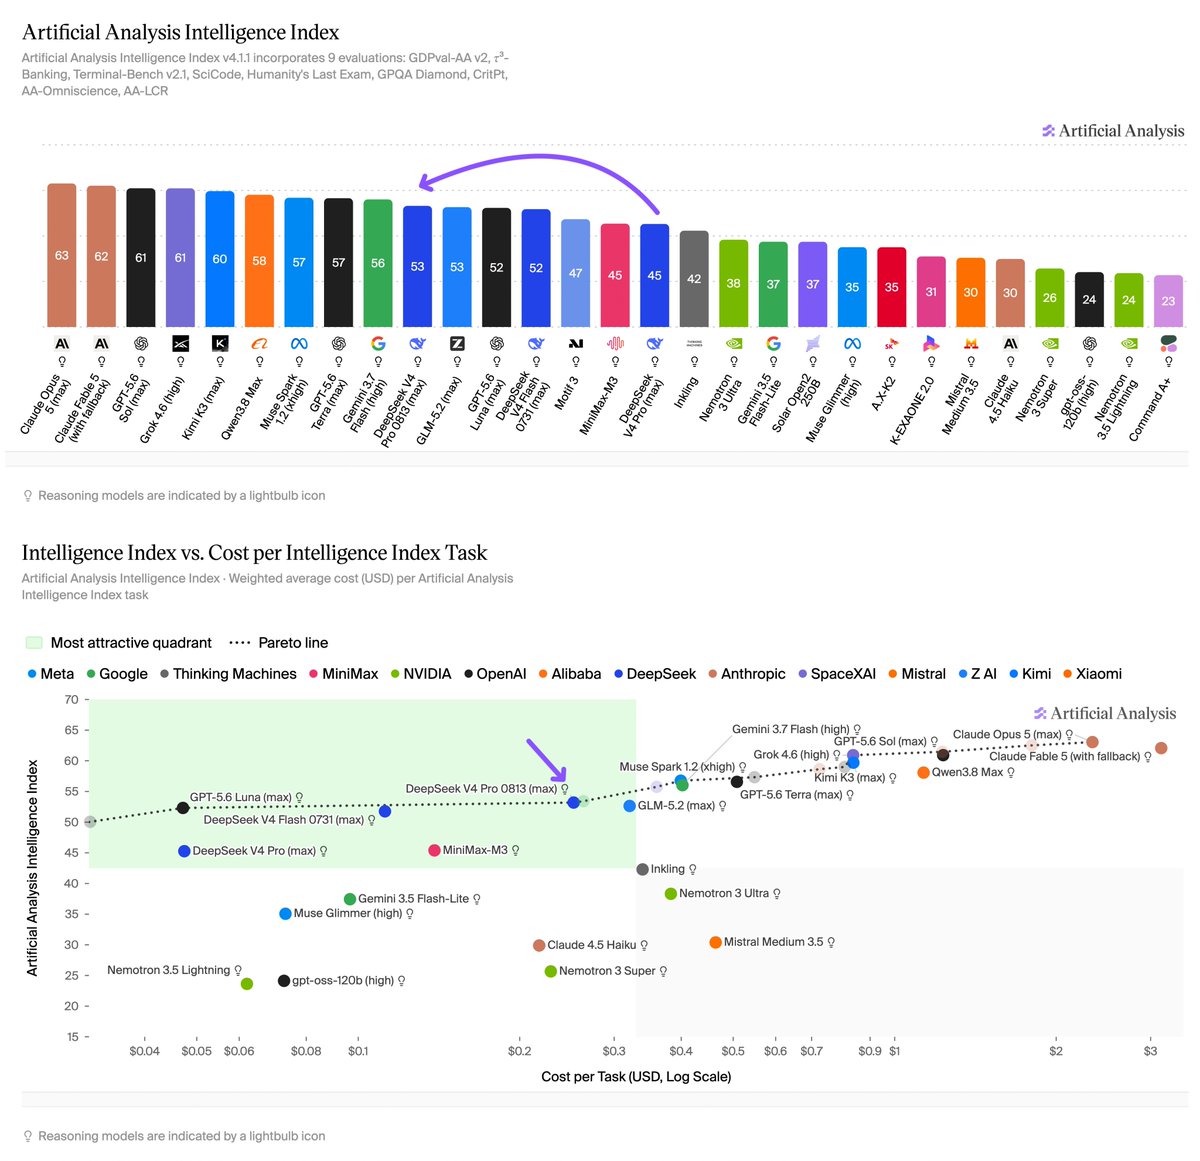
OpenRouter reported that DeepSeek V4 Pro led spending for shell execution and Kimi K3 led spending for tool dispatch in its August 6 snapshot. These categories concern running commands and invoking tools. The attached chart shows DeepSeek V4 Pro at 18.0% of shell-execution spend, just ahead of GPT-5.4 at 16.1%, so the lead is narrow and far from a majority. The result shows where customers allocated money for those workloads on this platform. It does not measure how often the models completed tasks successfully, so a spending lead should not be read as an accuracy ranking.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.




Checking sign-in…
Loading comments…