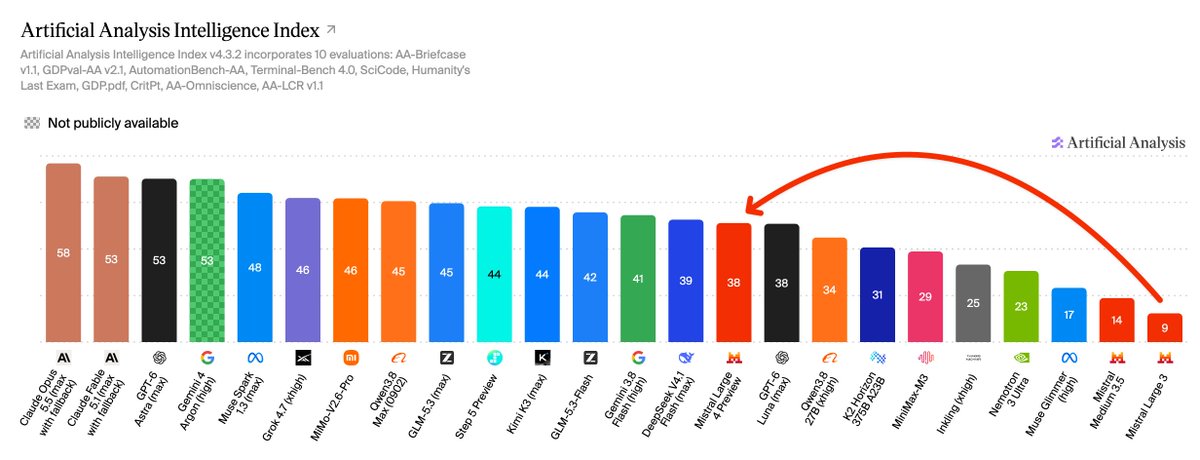
A document benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → measures the model together with what its interface lets it receive. Artificial Analysis' Mistral Large 4 preview evaluation attributed part of the document-reasoning gain to the API, which now accepts 100 images per request, up from 8 for earlier Mistral models.
That matters when interpreting an improvement as pure reasoning progress: an input bottleneck can suppress a capable model's result. The October report concerned Mistral's hosted research preview; downloadable weights were still planned. The result supports evaluating the whole document-processing setup, while keeping announced availability separate from what had actually shipped.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.