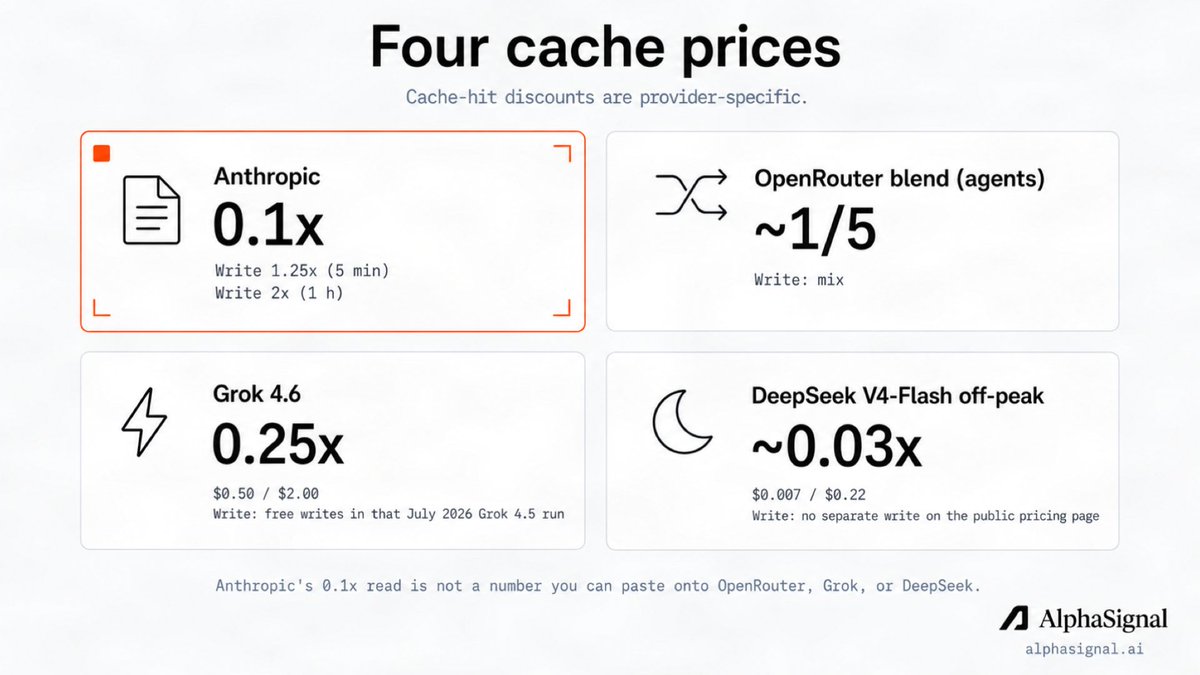
OpenRouter's response cache reuses an entire model response when an identical request arrives before the stored result expires. Caching is opt-in, enabled per request with a header or through a preset, and the feature was described as beta. The first request reaches the provider and is billed normally; a cache hit returns the saved result without another provider call or generation charge. Matching includes the request body, model, API key, and streamingSending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.Full definition → mode, so similar prompts are insufficient. The announcement describes this as useful for repeated tests and retries: completed calls can be replayed while new requests still require generation.
Terms in this piece · Glossary
streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
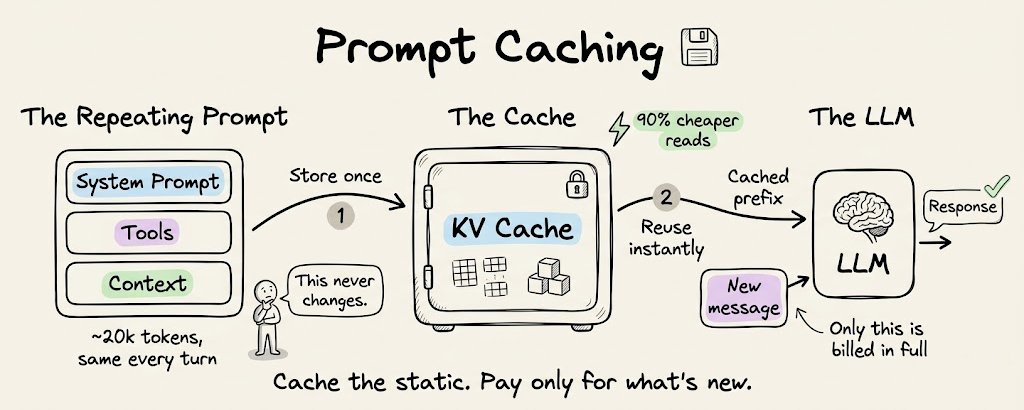
prompt caching — Reusing the model's processed form of a repeated prompt prefix so subsequent calls skip re-reading it, cutting cost and latency substantially.